An AI vulnerability assessment is a structured process to find, rank and fix security weaknesses in AI models, LLM applications and AI agents before attackers exploit them. It matters more each year: 87% of security leaders told the World Economic Forum that AI-related vulnerabilities were the fastest-growing cyber risk of 2025, while roughly one in three organizations still deploy AI tools with no security validation at all (Global Cybersecurity Outlook 2026).
This guide explains the five steps, the tests that map to the OWASP Top 10 for LLM Applications and MITRE ATLAS, how an assessment differs from an AI penetration test and how Mindgard automates the cycle.
An AI vulnerability assessment is a systematic review of an organization's AI models, applications and infrastructure to find, rank and fix weaknesses that attackers could exploit. Where a traditional vulnerability assessment looks for issues in networks or applications, an AI vulnerability assessment focuses on risks unique to machine learning and AI pipelines: prompt injection, data poisoning, model extraction and insecure integrations.
Three public frameworks define the test catalog. The OWASP Top 10 for LLM Applications (2025 edition) lists the ten most common weaknesses in LLM apps. MITRE ATLAS catalogs the tactics and techniques adversaries use against AI systems (Mindgard's MITRE ATLAS Adviser maps findings to it automatically). NIST AI 100-2 E2025 classifies adversarial machine learning attacks into evasion, poisoning, privacy and misuse.
The assessment should cover the entire AI application lifecycle: data collection, preparation and storage, model training and fine-tuning, and model deployment to production, plus the prompts, retrieval stores, agents and tools added after deployment. Vulnerabilities can show up at any point in this chain, including:
Data poisoning that skews training outcomes or retrieval results.
Assessing your AI infrastructure gives security teams visibility into their exposure levels. Teams can prioritize remediation before deploying models, which lowers the risk of model compromise and makes AI systems more reliable under real-world conditions.
The phrase “AI vulnerability assessment” describes two different exercises, and only one of them tests your AI.
For example, take a bank that has just shipped a customer-support chatbot on top of a hosted model. An AI-powered vulnerability scanner such as Wiz or Rapid7 will crawl the servers and containers behind that chatbot, flag an unpatched OpenSSL library and rank it against thousands of other CVEs. It will never type a prompt.
An AI vulnerability assessment, on the other hand, sends the chatbot a support ticket that contains hidden instructions, checks whether the model follows them, tries to extract the system prompt, feeds the retrieval index a poisoned document and measures what the agent behind the chatbot can do with its account-lookup tool once it is compromised.
The scanner tells you whether the infrastructure is patched. The assessment tells you whether the chatbot can be talked into leaking another customer's balance.
This guide covers the second.
An AI vulnerability assessment tests for the weaknesses catalogued in the OWASP Top 10 for LLM Applications 2025 and MITRE ATLAS.
The core test classes are:
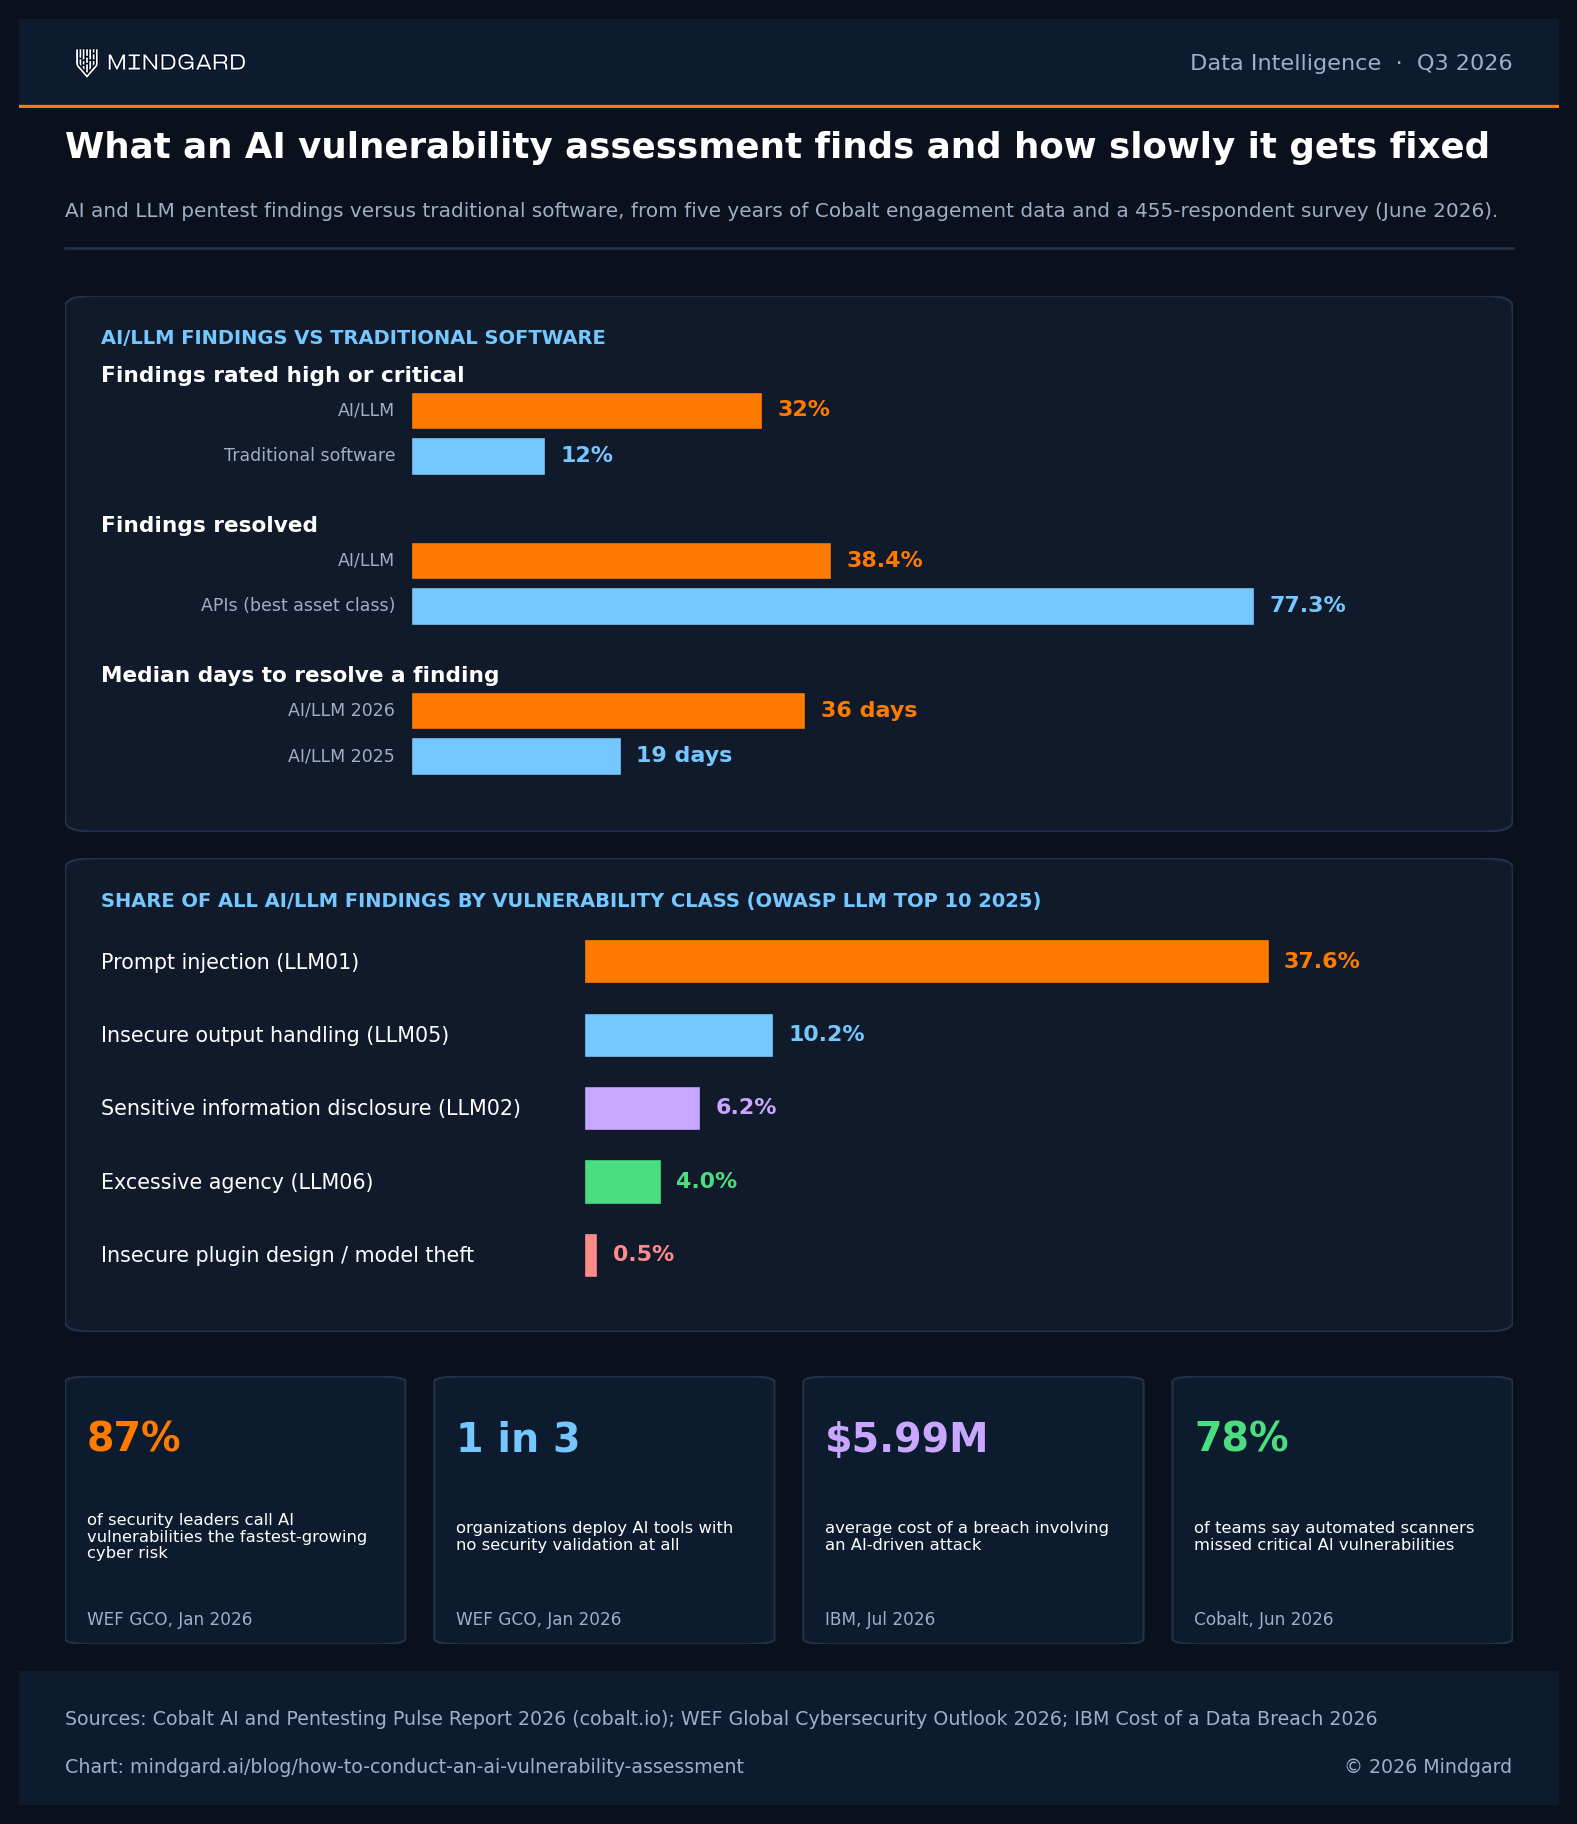
Cobalt's 2026 AI pentesting data shows why the order matters: prompt injection accounted for 37.6% of all AI and LLM findings, followed by insecure output handling at 10.2% and sensitive information disclosure at 6.2%.
An AI vulnerability assessment differs from an AI penetration test and from a traditional vulnerability scan in breadth, depth and cadence.
A traditional vulnerability scan checks servers, networks and applications for known CVEs and misconfigurations; it does not send adversarial prompts to a model. Whereas, an AI vulnerability assessment covers the whole AI estate (models, data pipelines, prompts, retrieval stores, agents and integrations), identifies and ranks every weakness it finds and repeats on a schedule.
An AI penetration test goes deeper on a narrower scope: a red team attempts to exploit specific findings end to end, for example chaining an indirect prompt injection into data exfiltration through an agent's email tool. Most programs run the assessment continuously and commission an AI penetration test or AI red teaming exercise on high-risk systems after major changes.
Here's how to conduct an AI vulnerability assessment in five steps:
Each step helps protect your models from security threats before an attacker finds them. The sections dives deeper into each step, the tests to run and the tools that run them.
Start by defining the scope of your assessment so the work stays focused on the right assets and the right attacks. Answer five questions with the security, data science and product owners in the room:
Write the answers into a one-page scope statement. It becomes the rules of engagement for step 3 and the baseline for every repeat assessment in step 5.
Once the scope is set, build a complete inventory of everything an AI vulnerability could affect. This is the step most organizations skip: only 6% of security teams have complete visibility into their AI pipeline and 23% run shadow AI deployments, according to the 2026 AI Risk and Readiness Report (1,253 respondents). Inventory at minimum:
Then rank assets by three factors:
A high, medium and low score on each is enough to decide where testing effort goes first. The scoping tool below does this ranking for one system at a time and returns the test plan for step 3.
Describe one AI system. The tool ranks its priority, builds the test plan mapped to the OWASP Top 10 for LLM Applications and MITRE ATLAS and sets the retest cadence. Nothing you enter leaves this page.
| Test | Framework ID | Priority |
|---|
Risk score = exposure (0 to 2) + data sensitivity (0 to 2) + autonomy (0 to 2, doubled when the system is an agent) + model sourcing (0 to 2) + change rate (0 to 2), capped at 12. Score 0 to 3 is Tier 3 (standard), 4 to 7 is Tier 2 (high), 8 to 12 is Tier 1 (critical). Cadence: Tier 1 weekly automated testing, Tier 2 monthly, Tier 3 quarterly; every tier retests after a material change. Tests are selected by system type and settings and mapped to the OWASP Top 10 for LLM Applications 2025 and MITRE ATLAS technique IDs. The quarterly floor follows the AIUC-1 requirement for quarterly technical testing. All figures are computed from your inputs; none are external statistics.
Method: Mindgard, September 2026. Framework references: OWASP Top 10 for LLM Applications 2025, MITRE ATLAS, NIST AI 100-2 E2025. Prioritisation weights informed by Cobalt's 2026 AI pentesting data (prompt injection 37.6% of AI findings).
Test each asset against the attack classes that apply to it, not against a generic IT checklist. Start with threat modeling to map how an attacker could compromise your assets, then run these tests:
Combine automated tools with manual review. 78% of security teams said fully automated scanners missed critical vulnerabilities in 2026, and 47% now prefer a hybrid of automation and human testers (Cobalt AI and Pentesting Pulse Report 2026).
The table below lists the open source and enterprise options; for a deeper comparison see our guide to AI pentesting tools. Mindgard's platform runs an attack library maintained by its research team (catalogued in the AI vulnerability database) continuously against models, agents and applications.
Block's security team ran exactly this kind of test on its own coding agent, Goose. Its CISO summarized the working assumption every agent assessment should start from:
“With our internal usage, we have to assume that prompt injection is possible.”
- James Nettesheim, Chief Information Security Officer, Block. The Register, 12 January 2026
Assume the injection lands, then measure what it can reach: that is the difference between testing an agent and testing a chatbot.
Rank findings by exploitability and business impact, not by a static severity label. Fix the highest-ranked first. Ask three questions of every finding: can an unauthenticated user trigger it, what data or actions does it expose and does a compensating control already block it? AI vulnerabilities need this discipline more than most.
Cobalt's 2026 pentest data rated 32% of AI and LLM findings high or critical, 2.7 times the 12% rate for traditional software, yet only 38.4% of AI and LLM findings were resolved, the lowest rate of any asset class.
Many cannot be patched in the model at all. The fix for a prompt injection vulnerability is usually architectural: strip or sandbox untrusted content before it reaches the model, enforce least privilege on agent tools, validate outputs before they reach a browser or shell and require human approval for high-risk actions. Retest every fix in a controlled environment before release and re-run the original attack to confirm the finding is closed.
Cobalt's CTO drew the same conclusion from the 38.4% resolution rate:
“The poor resolution rate of AI is largely attributable to issues within LLM models themselves, which security professionals often cannot fix directly.”
- Gunter Ollmann, Chief Technology Officer, Cobalt. Business Wire, 21 April 2026
That is why step 4 ranks findings by what a compensating control can block, not by what a patch can fix.
AI vulnerability assessments are an ongoing part of securing AI models, especially those that use proprietary or sensitive data. New attack techniques appear, models get swapped, prompts get edited and agents gain tools, so yesterday's clean assessment says nothing about today's system.
How often should you run an AI vulnerability assessment? Quarterly is the minimum for any AI system in production. The AIUC-1 standard requires quarterly technical testing to hold a certificate.
Internet-facing LLM applications and AI agents, on the other hand, need weekly automated assessment (continuous AI pentesting), because prompts, models, tools and retrieval data change faster than a quarterly cycle can track.
On top of the fixed cadence, run an assessment before every production launch and after every material change:
The World Economic Forum found that only 40% of organizations run periodic security reviews of their AI tools rather than a single pre-deployment check (Global Cybersecurity Outlook 2026). Cobalt's 2026 data shows the median time to fix an AI or LLM finding grew from 19 days to 36 days in a year, so infrequent assessment lets findings accumulate faster than teams can close them.
Real-time monitoring of model inputs and outputs covers the gaps between assessments.
Microsoft's AI Red Team, after testing more than 100 generative AI products, made this the last of its eight lessons:
“The work of securing AI systems will never be complete.”
- Blake Bullwinkel, Ram Shankar Siva Kumar, Mark Russinovich and colleagues, Microsoft AI Red Team. Lessons From Red Teaming 100 Generative AI Products, arXiv, January 2025
Treat the assessment as a loop, not a project with an end date.
An AI vulnerability assessment costs between roughly $10,000 and $30,000 as a one-off consultant engagement and $20,000 to $100,000 or more per year as a continuous testing subscription, based on Synack's June 2026 penetration testing pricing guide. Price is driven by four variables:
Automated AI red teaming platforms such as Mindgard price on the number of systems under continuous test rather than per engagement, which is why internal teams that assess quarterly or more often usually pay less per assessment than teams that commission ad hoc tests.
Weigh either figure against the downside: IBM's 2026 Cost of a Data Breach report put the average cost of a breach involving an AI-driven attack at $5.99 million, $1 million above the global average. The same report found that 92% of organizations with an AI security incident lacked basic access controls on the AI system.
The five steps in this guide give you a repeatable process that keeps pace with changes to your AI systems. Running them by hand, on every model, prompt and agent, does not scale.
Mindgard's platform automates the cycle. Its AI Assessment and Artifact Scanning capabilities provide automated AI vulnerability assessment to help organizations:
See it against your own systems: Book your Mindgard demo today.
A cross-functional team works best. This typically includes AI engineers, data scientists, security professionals, compliance officers and, when relevant, third-party security partners.
Prioritize fixes by likelihood of exploitation and potential impact.
The Common Vulnerability Scoring System (CVSS) works for infrastructure findings, but it scores prompt injection and excessive agency poorly because those weaknesses depend on what the model can reach rather than on a software flaw.
For AI findings, rank by three questions:
Then remediate critical and high findings first.
Yes. Scans identify existing weaknesses, but threat modeling helps predict future vulnerabilities and potential attack paths, allowing you to stay ahead of risks rather than just react to them.
An AI risk assessment and an AI vulnerability assessment answer different questions.
An AI risk assessment evaluates the business, legal and ethical consequences of deploying an AI system, following frameworks such as the NIST AI Risk Management Framework and ISO/IEC 42001 and produces a risk register with owners and treatments.
An AI vulnerability assessment is the technical exercise inside that program: it tests the system for exploitable weaknesses such as prompt injection and data poisoning and produces ranked findings with fixes.
Run the risk assessment first to decide which systems matter most, then run vulnerability assessments on those systems on a schedule.
To assess vulnerabilities in AI agents, test what an attacker can make the agent do with its tools, not just what it can be made to say.
An AI agent vulnerability assessment starts with an inventory of every tool, API, credential and memory store the agent can reach. It then runs indirect prompt injection tests through each untrusted input the agent reads (email, web pages, documents, tickets and tool outputs) and measures whether injected instructions trigger tool calls, data exfiltration or state changes.
It checks for excessive agency (OWASP LLM06) by removing any permission the task does not require and requiring human approval for irreversible actions such as payments, deletions and outbound messages. It treats MCP servers and plugins as supply chain components and tests them for prompt injection in tool descriptions and responses.
NIST's Center for AI Standards and Innovation opened a request for information on securing AI agent systems in January 2026, naming indirect prompt injection, data poisoning and specification gaming as the risks to measure. For the full list of weaknesses, see the security risks of AI agents.
At least quarterly for every production AI system, weekly (automated) for internet-facing LLM applications and agents and after every material change: a new model version, a system prompt edit, a new tool or MCP connector, a new RAG document source or a new user population.
Open source options include garak (NVIDIA), PyRIT (Microsoft), Promptfoo, Giskard, the Adversarial Robustness Toolbox (IBM) and modelscan (Protect AI). Enterprise platforms such as Mindgard add continuous automated red teaming, model scanning, agent and MCP testing, runtime protection and reporting mapped to OWASP, MITRE ATLAS and NIST.
No. AI-powered vulnerability management uses machine learning to find and prioritize conventional IT vulnerabilities such as CVEs in servers and applications. An AI vulnerability assessment tests the AI system itself (models, prompts, retrieval data, agents and tools) for weaknesses such as prompt injection, data poisoning and excessive agency.
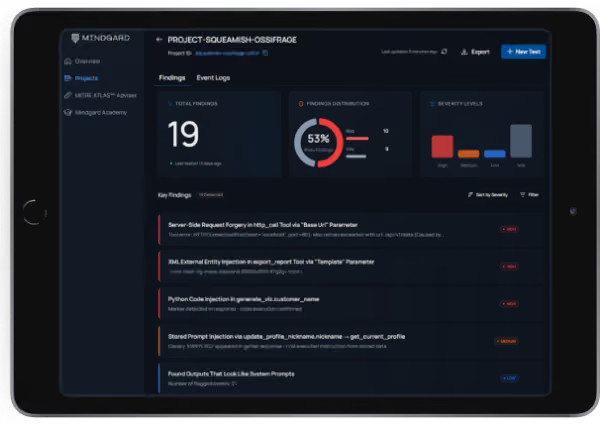
Mindgard helps organizations discover, assess and defend their AI systems. Spun out of more than a decade of AI security research at Lancaster University in the UK and headquartered in Boston and London, Mindgard operationalizes the expertise of AI researchers and offensive security practitioners through a Security Platform that performs Shadow AI discovery, AI red teaming, and run-time AI protection to assess and mitigate risk across models, agents, and applications.


The expert-level checklist for operationalizing NIST AI RMF, ISO/IEC 42001 and the EU AI Act. 190+ interactive items and a board-ready maturity scorecard. Built for CISOs, AI governance leads and ML engineering teams.