
AI pentesting attacks AI systems (models, LLM applications, RAG pipelines and agents) for prompt injection, jailbreaks, data poisoning, model extraction, system prompt leakage and excessive agency. It is not the same as AI-driven pentesting, where an AI agent tests conventional software.
More than 20% of organizations reported a breach of an AI model or application in the past year (IBM, 2026 Cost of a Data Breach Report, July 2026). So what is AI penetration testing, and why does it matter? AI penetration testing (also written AI pentesting or AI pen testing) is the security testing of an AI system by simulated attack: a tester uses prompt injection, jailbreaks, data poisoning, model extraction and tool abuse against the model, the LLM application, its retrieval (RAG) pipeline and its agents to find and prove exploitable vulnerabilities before an attacker does.
It differs from traditional penetration testing in what is tested (a probabilistic model and its integrations, not only code and infrastructure) and in the attack classes used, which are catalogued in the OWASP Top 10 for LLM Applications and MITRE ATLAS. The term, and its short form AI pentesting, also has a second meaning: AI-driven pentesting, where an AI agent tests ordinary software. The next section separates the two.
This guide explains what AI penetration testing is, how it differs from traditional pentesting and AI red teaming, the common vulnerabilities in LLM systems it finds, how an engagement runs step by step, what it costs, which frameworks and regulations call for it and whether a certification exists.
AI penetration testing (AI pentesting) is a controlled, authorised attack on an AI system to find and prove exploitable vulnerabilities in the model, the application around it and the data and tools it can reach. The tester plays the adversary: crafting prompts that override the system prompt, planting instructions in documents the model will retrieve, extracting the system prompt or training data, poisoning fine-tuning or embedding data, and abusing the tools and permissions an agent has been granted.
Unlike traditional penetration testing, which targets networks, applications and infrastructure with a fixed attack surface, an AI pentest targets a probabilistic system whose behaviour changes with every model version, prompt edit and new integration, so weaknesses in the AI models' architecture, data handling and decision logic are the primary targets.
An AI pentest of a generative AI system, sometimes called LLM penetration testing, usually covers four layers. The model layer: jailbreaks, harmful output and bias. The application layer: prompt injection, improper output handling and system prompt leakage. The data layer: data and model poisoning, sensitive information disclosure and vector or embedding weaknesses. The agentic layer: excessive agency, tool misuse and abuse of plug-ins or MCP servers. NIST's AI 100-2e2025 taxonomy groups the underlying attacks into evasion, poisoning, privacy and misuse.
The output is a report of reproducible findings ranked by exploitability and business impact, each mapped to an OWASP or ATLAS entry with a fix, followed by a retest. Done before release, an AI pentest exposes AI models to many potential attacks while they are still cheap to change, and it produces the test evidence that EU AI Act Article 15, ISO/IEC 42001 and the NIST AI RMF now expect.
AI penetration testing, traditional pentesting and AI red teaming differ in target, method and output.
In practice an AI pentest is the scoped, repeatable engagement you run per release, and AI red teaming is the deeper exercise you run quarterly or before a high-risk launch. One platform can deliver both.
Microsoft's AI Red Team, after testing more than 100 generative AI products, drew the line the same way:
“AI red teaming is not safety benchmarking.”
- Blake Bullwinkel, Ram Shankar Siva Kumar and colleagues, Microsoft AI Red Team. Lessons From Red Teaming 100 Generative AI Products, arXiv, January 2025
A benchmark measures a model against a fixed test set; a pentest or red team exercise measures what an adversary can make your specific deployment do.
AI penetration testing finds the vulnerability classes listed in the OWASP Top 10 for LLM Applications 2025: prompt injection, sensitive information disclosure, supply chain weaknesses, data and model poisoning, improper output handling, excessive agency, system prompt leakage, vector and embedding weaknesses, misinformation and unbounded consumption. The most common vulnerabilities in practice fall into five groups, covered below: poisoning, prompt injection and jailbreaks, model inversion and extraction, excessive agency and leakage of the system prompt or sensitive data. No model is hack-proof; the aim of a pentest is to find the paths an attacker would use first and close them.
NIST framed the problem when it published its adversarial machine learning taxonomy:
“Despite the significant progress AI and machine learning have made, these technologies are vulnerable to attacks that can cause spectacular failures with dire consequences.”
- Apostol Vassilev, computer scientist, NIST. NIST news release, January 2024
The attacks below are the ones that taxonomy, now in its 2025 edition, expects a tester to try.
In a poisoning attack, an adversary injects malicious data into pre-training, fine-tuning or embedding datasets, or ships a tampered model or adapter through the supply chain, so the system learns a backdoor or a biased pattern. The model then behaves normally until a trigger phrase or a particular input activates the planted behaviour.
A pentest checks whether the training, fine-tuning and retrieval pipelines accept untrusted data, whether third-party models and datasets are verified, and whether known trigger patterns change the model's output. Data validation, provenance checks and anomaly detection on training data are the standard mitigations.
Prompt injections are OWASP's LLM01 for a reason.
Single-prompt tests understate the risk: in Cisco's May 2026 study of 15 frontier models, multi-turn attacks reached an 88.3% success rate against the weakest model, and eight of the 15 models were at least 15 percentage points more vulnerable across a conversation than to a single prompt. There is no input filter that closes this class; the fixes are least-privilege tools, output handling that never trusts model text, retrieval sanitisation and runtime guardrails, all of which a pentest verifies.
Our guide to prompt injection techniques walks through the attack families.
Mindgard's continuous automated red teaming (CART) tests for prompt injection with input fuzzing and adversarial variants, encoding and escape-sequence checks, context-boundary and multi-turn manipulation and response monitoring, then reruns the suite when the prompt, model or retrieval sources change.
The Cisco researchers' conclusion is the reason a pentest scopes conversations rather than prompts:
“No frontier closed model in this cohort can be characterized as safe under iterative attack.”
- Nicholas Conley, AI Defense Researcher, and Amy Chang, Head of AI Threat Intelligence and Security Research, Cisco. Proprietary Problems: No Frontier Model Is Multi-Turn Immune, May 2026
Your application inherits that exposure from whichever model it calls, which is why the test has to run against your deployment, not the vendor's benchmark.
whether a specific record was in the training set; model extraction replicates the model itself through repeated queries. A pentest also tries the cheaper version: coaxing the model into repeating its system prompt, its retrieved documents or another user's data verbatim. A successful attack exposes proprietary data, personal data covered by GDPR and the intellectual property in the model.
Mindgard provides tools for vulnerability scanning that test for inversion, extraction and leakage, and our team recommends mitigations (rate limits, output filtering, differential privacy for training, prompt hardening) so that the confidentiality of both the model and its training data holds up under attack.
Excessive agency (OWASP LLM06) is what happens when an agent has more tools, permissions or autonomy than its task needs and an injected instruction turns them against you: an email assistant that forwards a mailbox, a support agent that issues refunds, a coding agent that runs shell commands.
A pentest maps every tool, plug-in and MCP server the agent can call, then tries to reach them through injected content, confused-deputy chains between agents and poisoned tool descriptions. MITRE ATLAS added techniques for autonomous reconnaissance, attack-path adaptation and agent-to-agent communication in its v2026.08 release (September 2026), which now catalogues 16 tactics and 114 techniques.
Least privilege, human approval for irreversible actions and per-tool allow lists are the fixes; our AI agent security guide covers them in depth.
System prompt leakage (OWASP LLM07) exposes the instructions, credentials, hidden rules and business logic embedded in the prompt; sensitive information disclosure (LLM02) exposes personal data, secrets or proprietary content from training data, retrieved documents or other users' sessions. A pentest asks the model to summarise, translate, encode or role-play its way around the confidentiality instruction, checks whether API keys or internal URLs sit in the prompt at all and tests whether one tenant's retrieved documents can surface in another tenant's answers.
The rule a tester applies: anything in the system prompt should be treated as public, and secrets belong in the application layer with proper authentication, not in the prompt.
An AI pentest follows the same arc as a conventional pentest (scope, reconnaissance, exploitation, validation, report, retest) with AI-specific content at each step. For a RAG chatbot the retrieval corpus and anything users can upload are in scope; for an agent, every tool and permission is.
The attack step does not need research-grade tooling to succeed. Microsoft's AI Red Team, after 100 product engagements, listed it as lesson two:
“You don't have to compute gradients to break an AI system.”
- Blake Bullwinkel, Ram Shankar Siva Kumar and colleagues, Microsoft AI Red Team. Lessons From Red Teaming 100 Generative AI Products, arXiv, January 2025
The same paper reports that basic techniques often work as well as, and sometimes better than, gradient-based methods, which is why a good pentest starts with the simple attacks and scales them rather than starting with the exotic ones.
An AI pentest costs between roughly $9,500 and $75,000 per engagement in 2026, depending on what the system can reach.
Published scoping bands from PentestTesting.com (June 2026) put a single chatbot on a third-party API at $9,500 and up (prompt injection, output manipulation, system prompt leakage, basic data exposure), an application with plug-ins, internal tools or a RAG pipeline at $15,000 to $35,000 (permission boundaries, agent abuse, indirect injection through retrieved content, API access control) and a multi-agent platform with proprietary or fine-tuned models at $35,000 to $75,000 (training-data exposure, advanced adversarial testing, an infrastructure pentest around the AI layer).
Model type, agent tool count and integration depth move the price more than the number of systems.
For comparison, AI-driven pentests of conventional software are priced per run: XBOW lists $4,000 to $8,000 per test and human-led application pentests are commonly quoted at $15,000 to $50,000 (Penetrify, August 2026). A continuous platform that re-runs the AI attack suite on every change is priced as an annual subscription and usually lands below the cost of two manual engagements; our AI red teaming statistics page tracks the benchmarks.
Use the estimator below to size an engagement before you request a quote.
Describe one AI system. The estimator returns the scope tier, a published price band, the attack classes the test must include, the frameworks it maps to and the retest cadence.
The scope tier follows the three published bands from PentestTesting.com's June 2026 pricing guide: Starter ($9,500 and up) for a single chatbot on a third-party API with limited backend integration; Professional ($15,000 to $35,000) for applications with plug-ins, internal tool access or RAG pipelines; Enterprise ($35,000 to $75,000) for multi-agent platforms or proprietary and fine-tuned models. The exposure score adds points for untrusted inputs (3), data sensitivity (1 to 4), actions (0, 3 or 5), model ownership (0, 2 or 3) and system type (1 to 5); it does not change the price band, only the test list and cadence. The cadence rule is Mindgard's: daily for agents that act autonomously, weekly for customer-facing systems, monthly for low-change internal assistants and a test on every change. Prices are engagement-level estimates for planning, not a quote.
Sources: PentestTesting.com, AI Penetration Testing Cost: 2026 Pricing Guide (price bands); OWASP Top 10 for LLM Applications 2025 (attack classes); MITRE ATLAS v2026.08; EU AI Act Article 15; Pentest-Tools.com survey, June 2026 (87.8% manual validation figure). Exposure score and cadence are derived from your inputs.
AI pentesting tools fall into three groups.
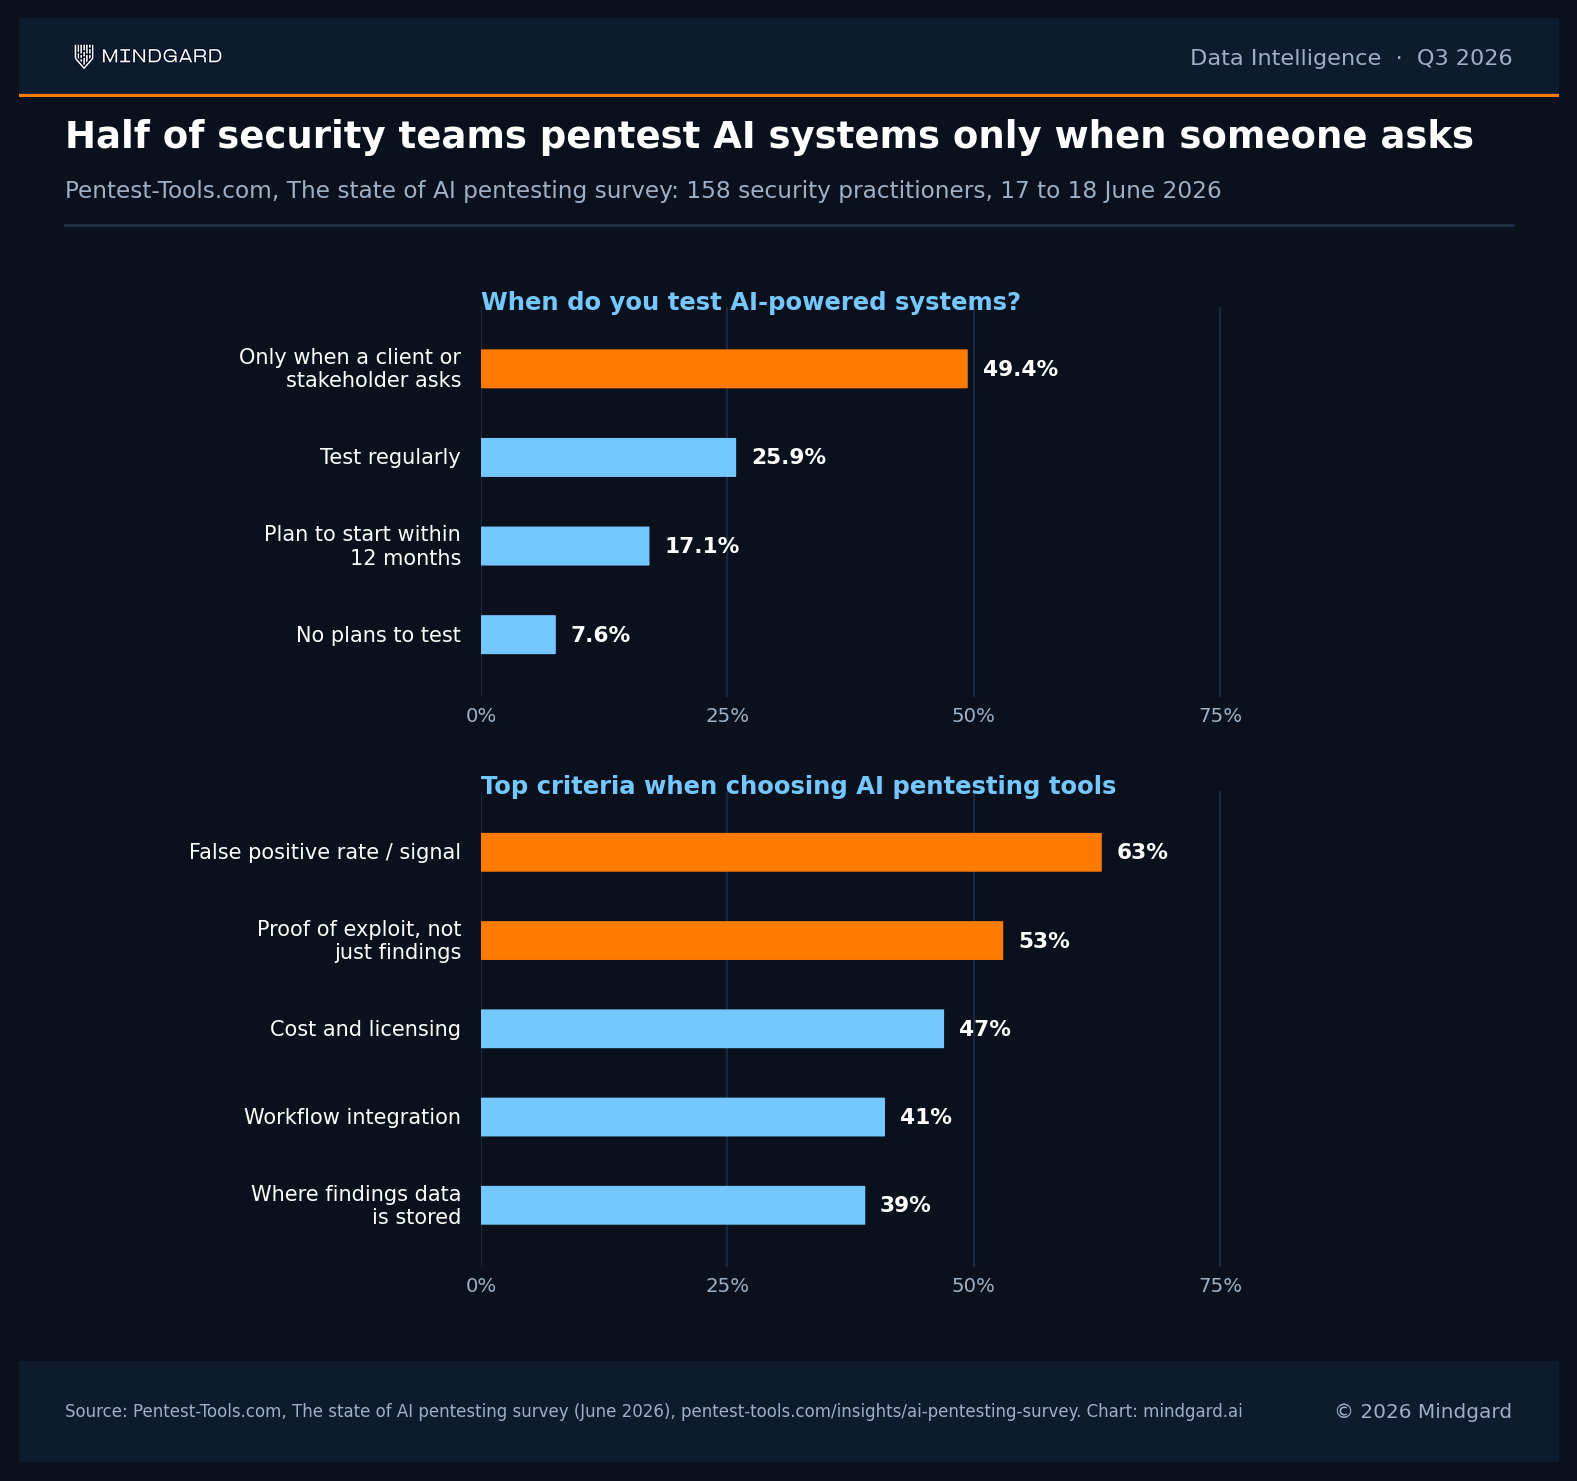
Practitioners weigh signal quality above everything else when choosing: 63% rank false positive rate as the top criterion and 53% want proof of exploit rather than a list of findings (Pentest-Tools.com, June 2026).
Our comparison of the best AI pentesting tools reviews 12 platforms across both meanings of the term, and Mindgard's AI pentesting and red teaming services page describes the engagement model.
Four frameworks and two regulations define what an AI pentest should cover and when it is required.
OWASP's AI security guidance ties the checklist to the standards.
Yes, an AI pentesting certification is on the way.
SANS SEC536: Adversarial AI, Penetration Testing AI Systems is the first mainstream course built around attacking LLM-integrated targets, and its exam, the GIAC AI Penetration Tester (GAIPT), covers direct and indirect prompt injection, RAG exploitation, agentic systems, MCP server attacks and AI architectural flaws. GIAC lists GAIPT as available for presale with general availability on 9 February 2027. Until then, hiring managers combine an offensive security credential (OSCP, GPEN, CRTO) with demonstrated LLM attack work: contributions to Garak or PyRIT, published jailbreak research or a portfolio of OWASP LLM Top 10 findings.
Our guide to the best offensive security certifications and training courses covers the foundation credentials. For AI systems themselves there is no pentest certificate; ISO/IEC 42001 certification of the management system and a current pentest report are what buyers and auditors ask for.
Pen test an AI system before launch, after every change that alters its behaviour and on a schedule in between. Behaviour-changing events are a model version upgrade (providers retire versions on their own timetable), a system prompt edit, a new retrieval source, a new tool or MCP server, a guardrail change and a fine-tune.
Between events, a weekly automated run for customer-facing assistants and a daily run for agents that can take actions is the cadence Mindgard recommends, with a human-led red team exercise quarterly or before a high-risk release. Only 25.9% of teams test AI systems regularly today (Pentest-Tools.com, June 2026); the continuous AI pentesting guide explains how to close that gap in a CI/CD pipeline.
More organizations are putting models, RAG assistants and agents into production than are testing them, and the attack classes above (poisoning, prompt injection, extraction, excessive agency, leakage) are the ones IBM's 2026 report found behind the $6.0 million average AI-enabled breach.
Mindgard runs the automated attack library, mapped to the OWASP Top 10 for LLM Applications and MITRE ATLAS, against your models, applications and agents, re-runs it on every change and adds runtime protection for what a test cannot prevent. Our team of human experts scopes the engagement, validates the findings and walks you through the fixes.
Schedule your Mindgard demo today and see what an attacker can make your AI system do before they try.
The most common vulnerabilities AI penetration testing finds are the OWASP Top 10 for LLM Applications 2025 entries:
Jailbreaks, model inversion and model extraction sit inside those classes.
Regular pentesting of AI models and LLM applications is the most reliable way to find exploitable risk before an attacker does. Adversarial training and red teaming expose the model to attack scenarios before release.
Input and retrieval sanitisation, output handling that never trusts model text, least-privilege tools, data validation and provenance checks on training data, anomaly monitoring and runtime guardrails cover the rest, and each control should be retested whenever the model, prompt or tools change.
Biased outputs create legal liability under anti-discrimination law and the EU AI Act, and they are also an attack surface: poisoned training data can plant a bias deliberately. Developers should train on representative datasets, run bias detection as part of pre-release testing and include harmful-output checks in every AI pentest.
Yes. AI-driven pentesting platforms such as XBOW, Aikido and Horizon3 NodeZero use autonomous agents to find and validate vulnerabilities in web applications, APIs and cloud environments, and AI red teaming platforms such as Mindgard use automated attack agents to test AI systems at scale.
Human testers still scope the engagement, validate findings (87.8% of practitioners report AI findings that need significant manual validation) and handle novel attack chains.
For open-source testing of an LLM application, Garak, PyRIT and Promptfoo are the standard starting points. For an enterprise programme that needs coverage mapped to the OWASP Top 10 for LLM Applications and MITRE ATLAS, human validation, retesting on every change and runtime protection, Mindgard is built for that scope.
Our best AI pentesting tools comparison reviews 12 options across both meanings of the term.
A scoped AI pentest engagement runs from about $9,500 for a single chatbot to $15,000 to $35,000 for a RAG or tool-using application and $35,000 to $75,000 for a multi-agent platform with proprietary models (PentestTesting.com, June 2026). Open-source tools are free but cost engineering time. Continuous platforms are priced as annual subscriptions and re-run the full attack suite on every change.
No, though they overlap.
An AI pentest is a scoped, repeatable engagement that finds and proves exploitable vulnerabilities in a specific AI deployment and retests the fixes. AI red teaming is broader and objective-driven, covering safety, misuse and business-logic scenarios across the whole system, usually run quarterly or before a high-risk launch. One platform can deliver both.
Agentic AI is used in pentesting In two ways.
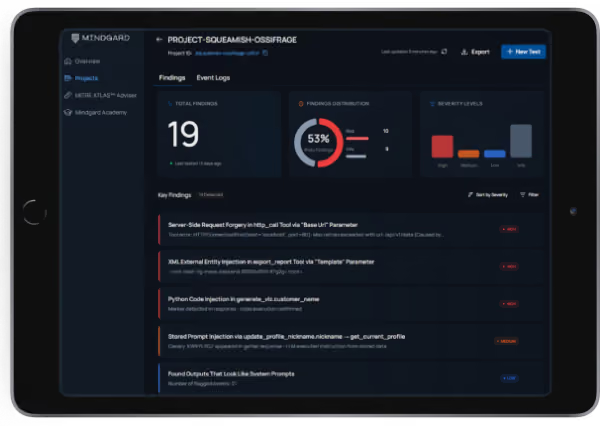
Mindgard helps organizations discover, assess and defend their AI systems. Spun out of more than a decade of AI security research at Lancaster University in the UK and headquartered in Boston and London, Mindgard operationalizes the expertise of AI researchers and offensive security practitioners through a Security Platform that performs Shadow AI discovery, AI red teaming, and run-time AI protection to assess and mitigate risk across models, agents, and applications.


The expert-level checklist for operationalizing NIST AI RMF, ISO/IEC 42001 and the EU AI Act. 190+ interactive items and a board-ready maturity scorecard. Built for CISOs, AI governance leads and ML engineering teams.


