AI application security requires specialized strategies—like strong data governance, secure architecture, hardened infrastructure, continuous threat monitoring, and AI red teaming—to defend against threats such as data poisoning, model theft, and adversarial manipulation that traditional security tools can’t fully address.
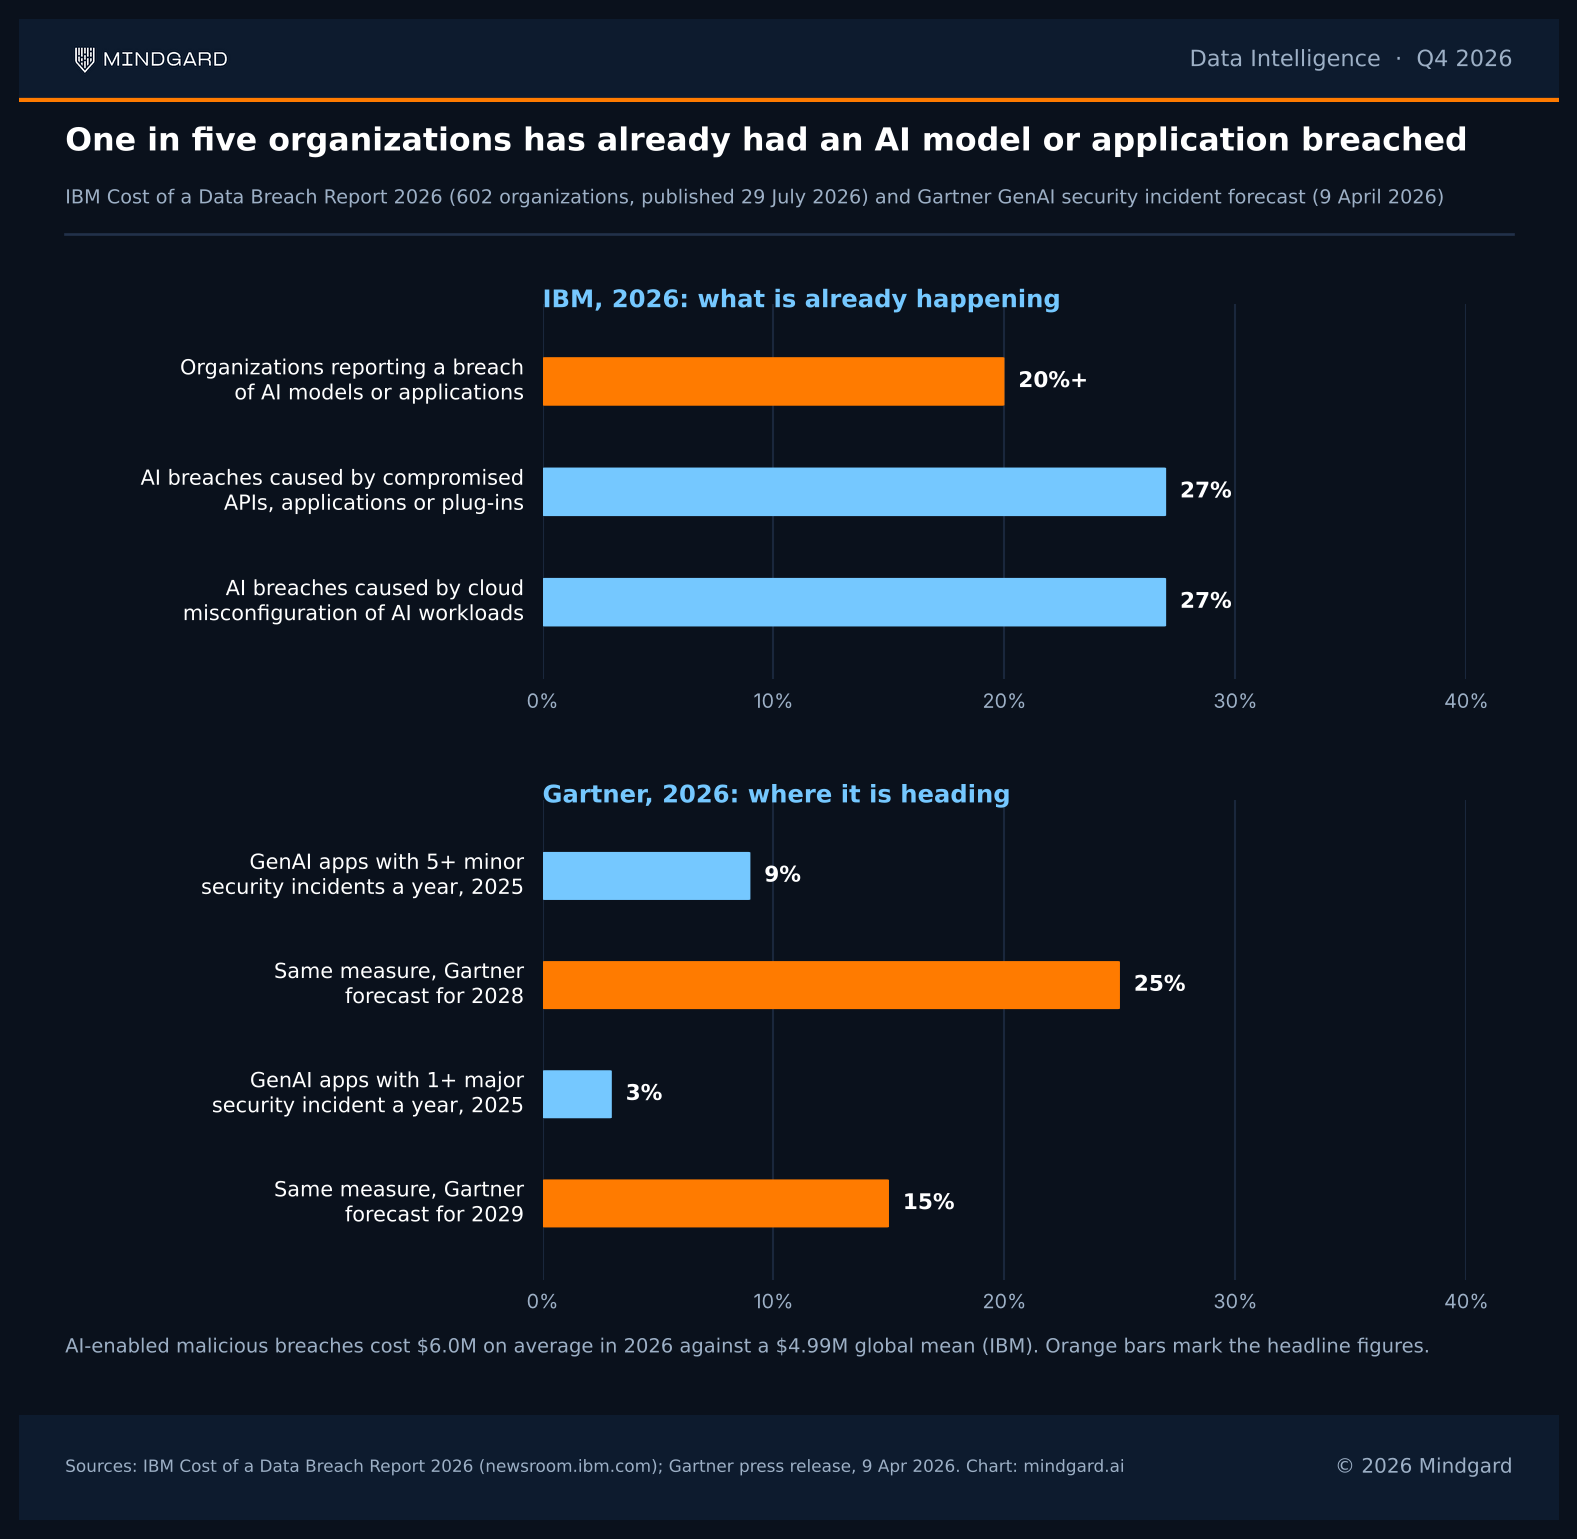
More than 20% of organizations reported a breach that targeted their AI models or applications in IBM's 2026 Cost of a Data Breach Report (July 29, 2026). AI application security is the practice of protecting AI-powered applications, and the models, data pipelines and agents behind them, from attacks that exploit how models behave.
Those breaches are expensive. AI-enabled breaches cost $6 million on average against a $4.99 million global mean, and Gartner forecasts that 25% of enterprise GenAI applications will suffer at least five minor security incidents a year by 2028, up from 9% in 2025.
This guide explains what AI application security is, which 2026 OWASP risks matter and the six steps to secure your models, data, agents and infrastructure.
AI application security is the practice of protecting AI-powered applications and the machine learning models, training data pipelines, retrieval (RAG) systems and agent workflows behind them from attacks that exploit how models behave. Traditional application security defends code, servers and networks against known exploit classes such as SQL injection. AI application security adds a second attack surface: the model's inputs, context, outputs, weights and permissions.
An attacker can:
The 2026 OWASP GenAI LLM Top 10, built from 7,714 recorded AI security incidents, ranks prompt injection, sensitive information disclosure and excessive agency as the three most serious of those risks.
For a customer-facing chatbot, a RAG assistant over internal documents, a large-scale generative AI system or an autonomous agent with tool access, securing the application means securing the model, the data around it and the permissions it holds. Every one of those layers appears in the wide range of risks that AI systems face.
Each one needs a control that traditional security stacks do not provide. Securing them is the subject of this guide.
The OWASP GenAI Security Project published the 2026 edition of its LLM Top 10 on August 3, 2026. Prompt injection kept the number one position for the third list in a row.
Two moves stand out:
The table below maps each risk to the step in this guide that addresses it.
As Steve Wilson, co-chair of the OWASP GenAI Security Project and Chief AI Officer at Exabeam, told SD Times when the list launched:
"Excessive agency rose from eighth to third because AI systems are no longer limited to generating text. Agents can browse the internet, call tools, access business systems and take actions on a user's behalf. When those capabilities are granted without appropriate limits, a model mistake can become a real-world security incident."
- Steve Wilson, co-chair, OWASP GenAI Security Project and Chief AI Officer, Exabeam. SD Times, August 2026
That is the practical definition of an AI application security incident in 2026: a model doing something with the permissions it was handed, rather than a model saying something embarrassing.
AI application security differs from traditional application security in three ways: the attack surface, the testing method and the failure mode.
To secure AI applications, take six steps:
Steps one through three secure the foundation. Steps four through six are the AI-specific controls, and they are where most of the 2026 incident data lives. Firewalls, passwords and a scanner in the CI pipeline are still necessary; they are no longer sufficient.
AI security starts with the data. Without documented data governance, even the best-trained models become high-risk assets, because the data used to train, fine-tune and ground a model is also the easiest layer to poison.
Organizations must ensure that training, fine-tuning and retrieval data is accurate, relevant and securely handled throughout its lifecycle. In practice, data governance for AI applications means four things:
The OWASP 2026 list ranks data and model poisoning fifth and vector and embedding weaknesses ninth, and both start here. With strong data governance in place, you protect the model and the foundation it relies on.
A secure AI application should be built on architectural foundations that treat the model as an untrusted component. Applying established frameworks such as Zero Trust Architecture (ZTA), NIST SP 800-53 and MITRE ATLAS™ ensures that every layer, from data ingestion to model inference, is protected through segmentation, least privilege and continuous validation.
Add the NIST AI Risk Management Framework for governance structure and the OWASP LLM Top 10 for the threat catalog. Three design rules follow from that stance:
Designing your AI systems with these principles in mind improves resilience against model extraction, adversarial inputs and unauthorized access.
Even the smartest AI models are only as secure as the infrastructure they run on. The 2026 IBM data makes the point with numbers: cloud misconfigurations affecting AI workloads caused 27% of AI-targeted breaches, tied with compromised APIs, applications and plug-ins as the leading cause.
Hardening your infrastructure means securing the compute environments, storage and networking layers that support your AI workflows, whether they are in the cloud, on-premises or hybrid. That includes applying OS-level security patches, enforcing container security best practices and isolating workloads through sandboxing and virtual network segmentation.
For AI specifically, add three items:
Runtime protection tools for AI application security fall into four categories:
Monitoring for adversarial behavior, data drift, model misuse and unusual access patterns keeps a production AI system safe after launch. In 2026 that monitoring has to sit in the request path, not only in the logs. In practice that means blocking injection attempts and sensitive data leakage in real time and alerting on model-specific anomalies such as a sudden jump in refusal rates, output length or tool-call frequency.
Static guardrails on their own are not enough, and NIST now has a mathematical proof of why. In a paper published in IEEE Security & Privacy in May 2026, NIST researchers showed that no finite set of guardrails can hold against every adversarial prompt.
As NIST senior scientist Apostol Vassilev put it:
"What this proof shows is that there is no finite set of guardrails that is universally robust against adversarial prompts. You have to commit to a constant search for weaknesses and stay ahead of attackers."
- Apostol Vassilev, senior scientist, National Institute of Standards and Technology. NIST News, 9 June 2026
The practical consequence is a loop, not a gate. Runtime detection feeds findings back into guardrail rules and red team test cases, and red team findings tune the detection.
With tools like Mindgard, teams can implement real-time threat detection tailored to AI environments, including alerts for model-specific anomalies and adversarial attacks. That closes the loop without building the tooling themselves.
Securing AI agents and agentic applications means controlling what an agent is permitted to do, not only what it is permitted to say. Give every AI agent its own identity with least-privilege permissions, allowlist the tools and arguments it may call, require human approval for irreversible actions and cap recursion and spend.
AI agents turn a model mistake into an action. That is why OWASP moved excessive agency from eighth to third in 2026 and why Gartner's April 2026 guidance on the Model Context Protocol (MCP) reads like a security review checklist. An agent should never inherit the permissions of the human user who launched it.
Gartner's recommendation is explicit: use authentication and authorization designed for AI agents, and treat any use case that combines sensitive data access, ingestion of untrusted content and external communication as a no-go zone because of exfiltration risk.
Aaron Lord, Sr. Director Analyst at Gartner, summarized the trajectory this way:
"Growing complexity from agentic AI will eventually lead to complications managing access to data and maintaining compliance."
- Aaron Lord, Sr. Director Analyst, Gartner. Gartner press release, 9 April 2026
Four controls cover most agent risk:
Test each control the same way you would test a web app's authorization layer: by trying to break it. Mindgard's AI agent security guide covers the attack techniques in detail.
Security claims mean nothing until they are challenged, and that means you need to go on the offensive. AI red teaming is the practice of simulating attacks against your models to expose blind spots before real adversaries do.
These exercises uncover vulnerabilities in training data, inference APIs, model outputs, agent tool calls and integration layers, places where traditional pen tests do not reach.
AI red teaming is not guesswork. It requires threat modeling tailored to your use case, the right adversarial testing tools, attack simulations across the AI lifecycle and expert adversarial testing. The attack set includes:
Because models, prompts and retrieved data change weekly, the test has to be continuous rather than annual. Every model update, prompt change or new tool integration is a new attack surface.
Mindgard's Offensive Security solution runs red team operations designed for AI systems. We probe your defenses with current adversarial tactics drawn from a library of thousands of attack techniques, map every finding to OWASP and MITRE ATLAS and help you fix weaknesses before they become incidents.
Five frameworks and standards do most of the work in an AI application security program. They fit together rather than compete.
NIST SP 800-53 and CISA's Zero Trust Maturity Model still govern the infrastructure underneath.
To get started securing your AI app, inventory every model, agent and AI API first, then threat model each one, apply baseline controls, run a first red team and add runtime protection. The 30-day sequence below takes a team from zero to a tested baseline.
This plan leaves you with the core components of an AI security stack:
Mindgard's AI security best practices guide expands each component.
AI applications are remarkable tools, but as organizations rely on them for critical processes, they also need to safeguard those models and agents against manipulation. Best practices such as multi-factor authentication, firewalls and strong passwords are still essential, but the six steps outlined in this guide are what separate a secured AI application from a hopeful one.
AI moves fast. It is not possible to manage these risks manually. Continuous adversarial testing identifies vulnerabilities as your AI systems evolve.
Mindgard helps organizations go beyond generic security practices and develop tested, resilient defenses against current attack techniques. Build AI that is secure by design: Book your Mindgard demo now.
Traditional tools can cover some layers (like network and OS), but they often lack visibility into AI-specific risks like model inversion, data poisoning, or inference manipulation. When in doubt, go with specialized platforms like Mindgard to address the unique challenges of AI app security.
With the right tools and design choices, security doesn’t have to slow you down. In fact, proactive security practices can reduce downtime, improve trust, and support faster go-to-market timelines by minimizing risk.
AI application security goes beyond protecting code and servers. It also includes safeguarding training data, preventing adversarial attacks, monitoring model behavior in production, and protecting intellectual property.
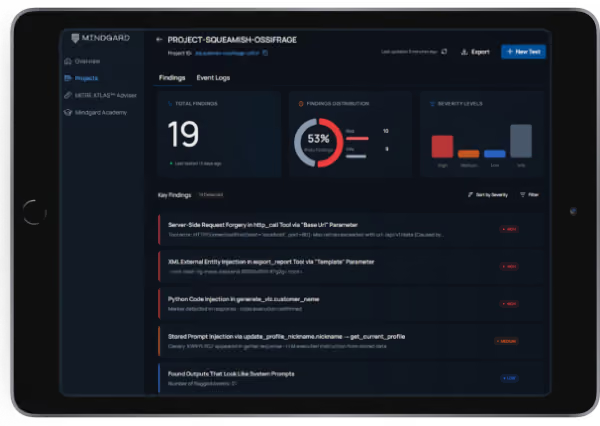
Mindgard secures AI models, agents, and applications against exploitable threats. Spun out of more than a decade of pioneering AI security research at Lancaster University, Mindgard combines offensive security expertise, AI red teaming, attacker intelligence, and automated protection to help organizations discover, assess, and mitigate risk across AI models, agents, and applications.


We found vulnerabilities in AI from OpenAI, Meta and AWS. See how Mindgard finds and proves the weakness attackers could exploit in yours.


