Repeat coverage as systems change
Establish baselines, detect regressions and retest known attack paths across releases.
Emulate real attackers across models, tools, data and workflows. Mindgard finds exploitable attack paths, reproduces them with defensible evidence and helps teams continuously verify that fixes work.
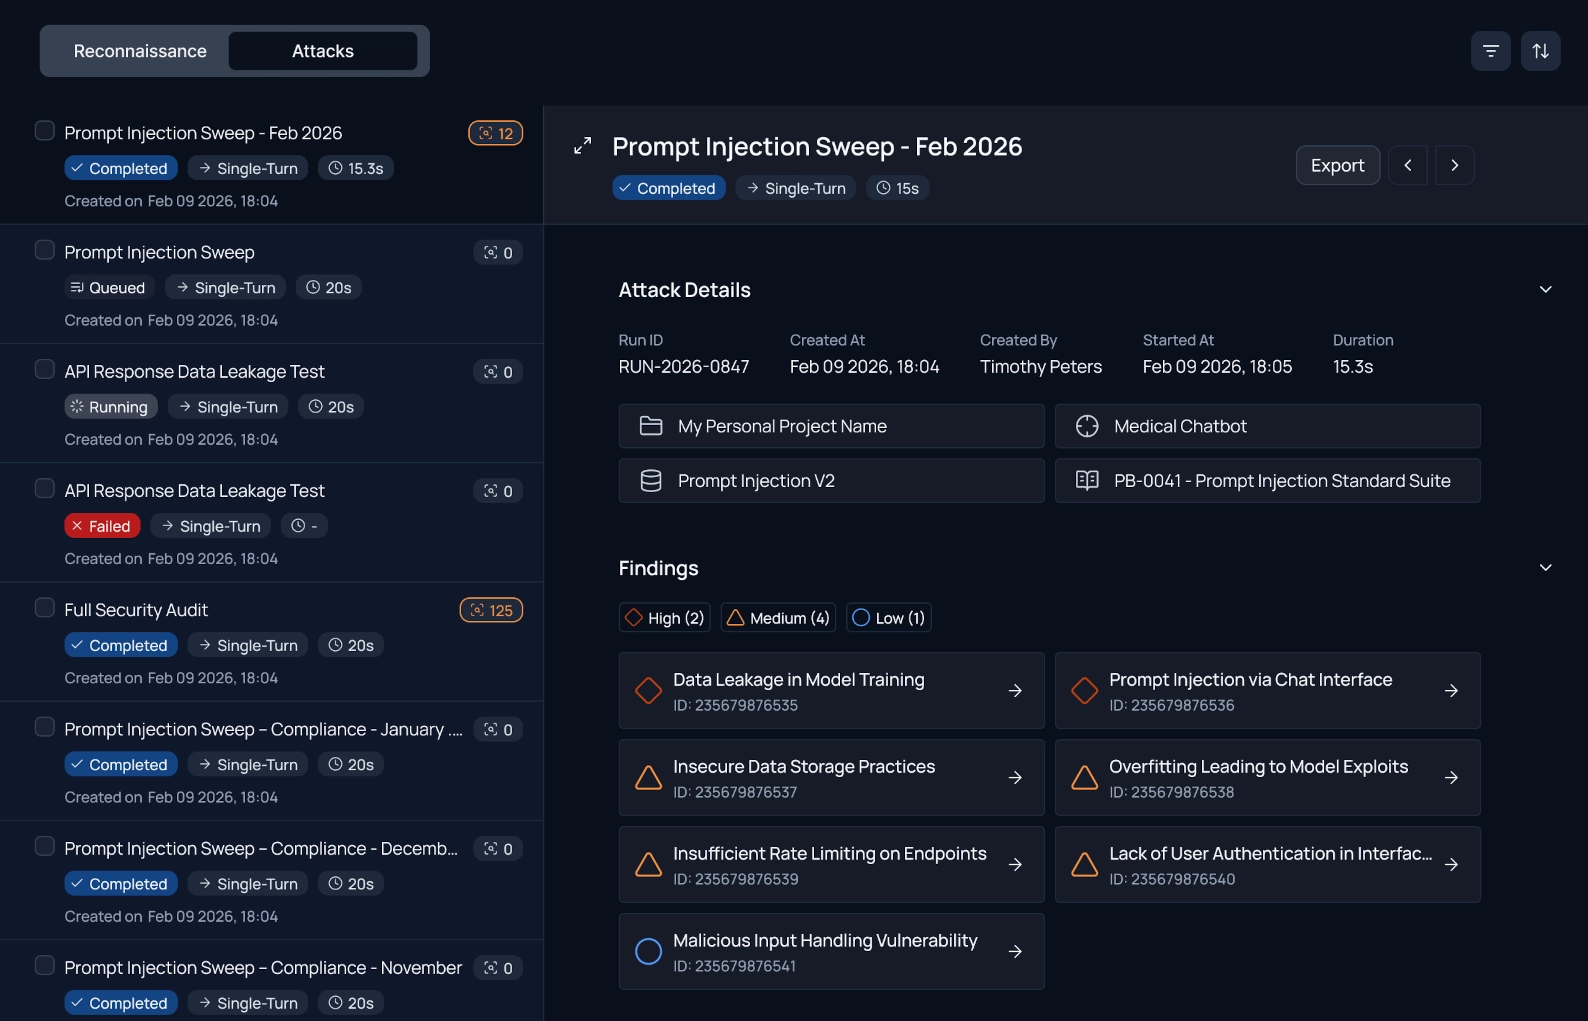
Basic scanners fire known payloads at an isolated model. Mindgard first discovers how the system behaves, then uses that intelligence to pursue realistic attack paths across the complete AI stack.
Agentic systems create risk through permissions and interactions—not just model responses. Mindgard evaluates how an attacker can influence an agent, reach a connected capability and produce downstream impact.
Use APIs and CI/CD to repeat testing, route evidence into security operations and extend offensive workflows through the tools your teams already use.

LLMs are red-teamed because they inherit all the security risks of classical software - and introduce novel failure modes like prompt injection, hallucinated output, training-data leakage, jailbreaks, and agentic misuse. Prompt injections were listed on OWASP LLM Top 10 (2025) alongside sensitive-information disclosure, supply-chain vulnerabilities, improper output handling, harmful levels of agency, and system-prompt leakage.
Attacks with maliciously crafted prompts have also been shown to evade traditional ML defenses better than other evasion techniques according to Microsoft’s research into 100 products in 2025. That’s why red teaming needs to happen against each model generation.
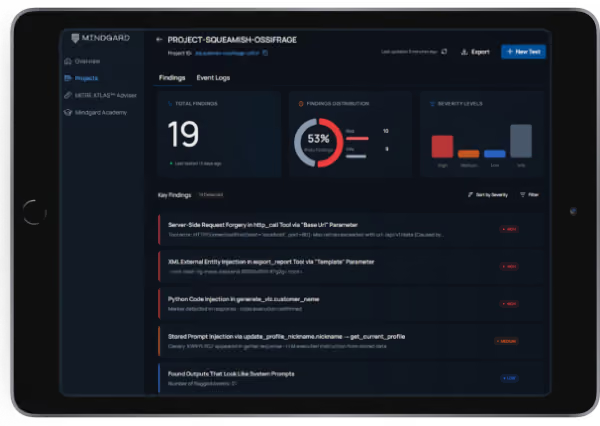
Mindgard is the best platform for continuous, automated AI red teaming of AI agents and LLM applications. It attacks the whole system (models, tools, data and workflows) with adaptive multi-turn attacks, maps findings to the OWASP Top 10 for LLM Applications and MITRE ATLAS and reruns tests in CI/CD on every change. Synack’s 2026 comparison names Mindgard best for continuous automated AI red teaming, and its research team has disclosed more than 150 vulnerabilities in production AI products.
Mindgard uses attacker-style reconnaissance, proprietary vulnerability intelligence, and adaptive attack agents to identify and validate high-impact vulnerabilities across AI systems and agents. Its offensive security platform emulates adversary workflows from reconnaissance through exploitation, then provides evidence, attacker context, and remediation guidance. Mindgard reduces AI risk assessments from weeks to hours and continuously verifies defensive gaps and policy compliance as AI systems change.
The cost of AI red teaming depends on the number and complexity of systems, the assessment scope, the techniques required, and whether testing is manual or automated. Manual engagements can require weeks of specialist work and are usually priced per project. Automated AI red teaming platforms reduce repeated manual effort and support continuous assessment across releases. Mindgard pricing is based on each organization’s environment and requirements.
AI red teaming produces evidence of how systems were assessed, which vulnerabilities were found, whether they were exploitable, and how teams responded. Findings can be mapped to frameworks such as the OWASP Top 10 for LLM Applications, MITRE ATLAS, NIST AI Risk Management Framework, and relevant EU AI Act requirements. This helps organizations demonstrate continuous policy compliance and provide defensible reporting to stakeholders and auditors.
No. Guardrails apply policies to AI inputs, outputs, or actions, while AI red teaming determines whether those controls can be bypassed. Red teaming reveals where guardrails hold, degrade, or fail under adaptive attacks and multi-step interactions. Organizations need both: guardrails to enforce policies and continuous AI red teaming to validate that those policies and defenses remain effective.
AI red teaming should be performed before deployment and continuously in production. AI systems can change when teams update a model, system prompt, dataset, guardrail, tool, permission, or integration. Each change can create a new attack path or weaken an existing control. Continuous AI red teaming helps teams find emerging vulnerabilities and verify that remediation remains effective as the system evolves.
Manual AI red teaming relies on human experts to develop creative attacks and investigate complex behavior. Automated AI red teaming executes adversarial techniques faster, more consistently, and at greater scale. Manual expertise remains valuable for novel and highly contextual scenarios, while automation enables continuous assessment. The strongest approach combines research-led attack intelligence with automation that can adapt and retest systems as they change.
AI model evaluation measures characteristics such as accuracy, quality, reliability, bias, or performance against a defined dataset or benchmark. AI red teaming adopts an adversarial perspective and actively attempts to make an AI system violate its security, safety, or policy requirements. It focuses on finding exploitable attack paths and defensive gaps rather than producing a general measure of model performance.
Traditional penetration testing primarily looks for vulnerabilities in software, networks, infrastructure, APIs, and configurations. AI red teaming examines how AI behavior can be manipulated through prompts, context, data, memory, models, tools, and multi-step interactions. The two practices complement each other: penetration testing secures the conventional technology stack, while AI red teaming addresses the behavioral and system-level risks introduced by AI.
AI red teaming can assess large language models, generative AI applications, chatbots, copilots, RAG systems, multimodal models, autonomous agents, agentic workflows, and systems connected to external tools or APIs. System-level AI red teaming also evaluates components such as prompts, memory, data sources, guardrails, MCP or A2A servers, permissions, and infrastructure rather than examining the underlying model in isolation.
AI red teaming can identify prompt injection, jailbreaks, sensitive information disclosure, system prompt leakage, model extraction, unsafe tool use, excessive agency, data or memory poisoning, and insecure output handling. It can also uncover weaknesses that only become exploitable when models, agents, data, APIs, permissions, and connected tools interact as part of a complete AI system.
Agentic AI red teaming uses autonomous attack agents to perform reconnaissance, plan attack paths, adapt techniques, and chain multiple actions together. It goes beyond running a fixed collection of prompts. Agentic AI red teaming emulates how an attacker explores a target, learns from its responses, and changes tactics to bypass controls or achieve a specific objective.
Automated AI red teaming uses software and autonomous agents to generate, execute, and evaluate adversarial attacks at scale. Unlike a point-in-time manual assessment, automated AI red teaming can run repeatedly as models, prompts, tools, guardrails, and configurations change. It helps organizations expand attack coverage, shorten assessment time, and identify new vulnerabilities without depending entirely on scarce AI security specialists.
AI red teaming is an adversarial security assessment that identifies how attackers could manipulate or exploit AI systems. It examines models, applications, agents, prompts, data, tools, APIs, and workflows to uncover vulnerabilities and defensive gaps. Effective AI red teaming provides evidence of which weaknesses are exploitable, their potential impact, and how security and engineering teams can close them.
Can’t find the answer you’re looking for? Please chat to our friendly team.
Mindgard secures AI models, agents, and applications against exploitable threats. Spun out of more than a decade of pioneering AI security research at Lancaster University, Mindgard combines offensive security expertise, AI red teaming, attacker intelligence, and automated protection to help organizations discover, assess, and mitigate risk across AI models, agents, and applications.