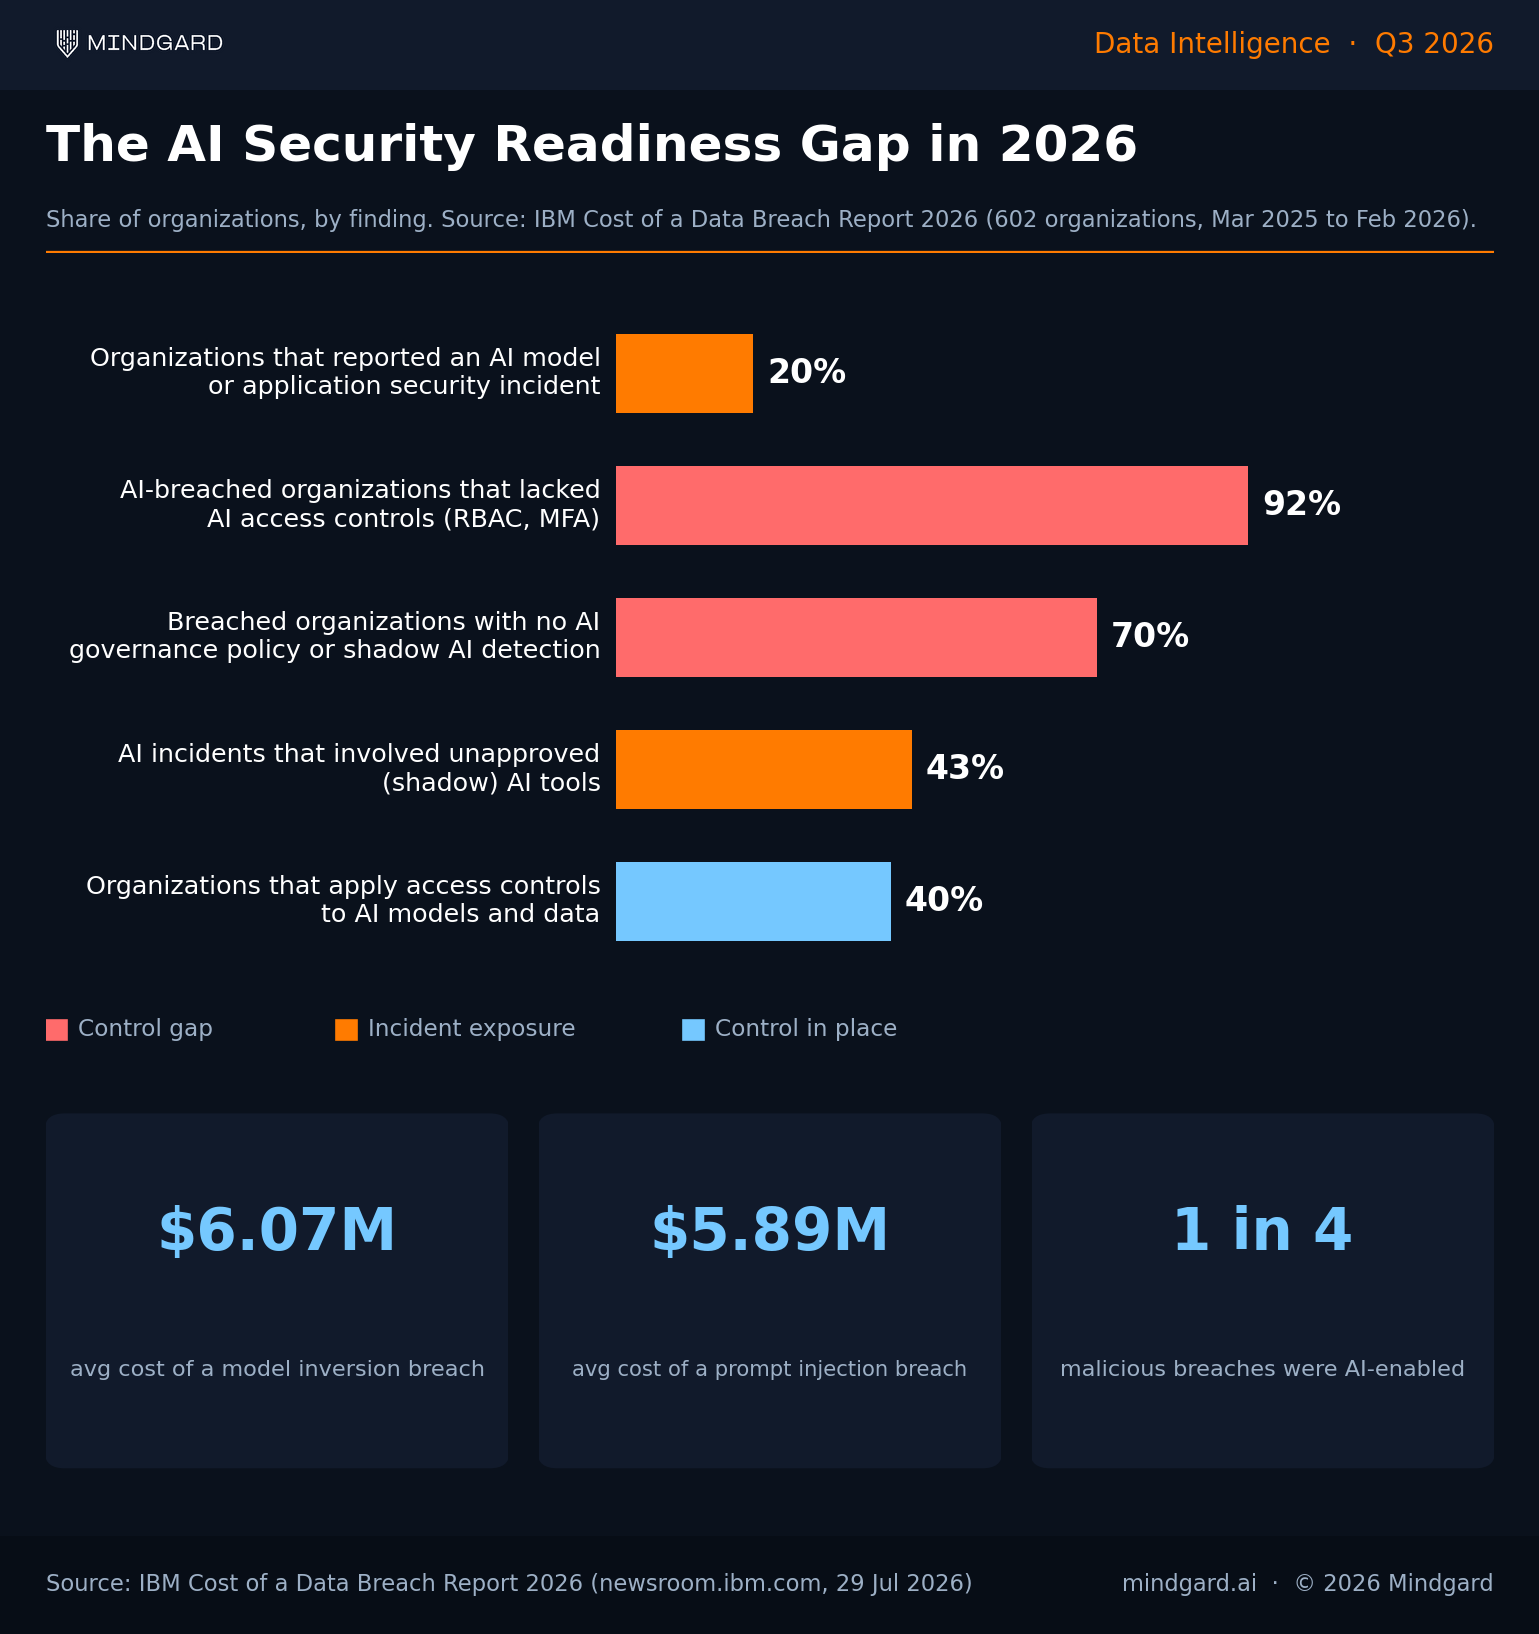
Roughly one in five organizations reported a security incident involving an AI model or application in the past year, up from one in eight the year before, according to IBM's Cost of a Data Breach Report 2026.
So what is AI security? AI security is the branch of cybersecurity that protects artificial intelligence systems from attacks on their models, training data, agents and outputs. It defends against prompt injection, data poisoning, jailbreaks and model theft across the full AI lifecycle. It differs from traditional cybersecurity because the asset under attack is a probabilistic model rather than fixed code.
The attackers are already equipped. 82% of hackers now use AI in their workflow and 74% say it has increased the value of hacking, per Bugcrowd's Inside the Mind of a Hacker 2026 (2,000 hackers surveyed). Defenders have not kept pace: close to seven in ten breached organizations have no governance policy for AI and only two in five apply access controls to their AI models and data (IBM, 2026).
This guide explains what AI security covers, how it differs from traditional cybersecurity, the common AI threats by lifecycle phase, the frameworks that define good practice (NIST AI RMF, ISO/IEC 42001, OWASP Top 10 for LLM Applications) and the controls, monitoring and red teaming practices used to secure AI models and agents.
AI security is the branch of cybersecurity that protects artificial intelligence systems from attacks. It covers machine learning models, large language models, AI agents, training data and the APIs that expose them. It defends against attacks that manipulate model behavior, extract private data or steal the model itself. NIST's Adversarial Machine Learning taxonomy (NIST AI 100-2, 2025) sorts these attacks into four classes: evasion, poisoning, privacy and abuse.
AI security spans the full lifecycle of an AI system: vetting training data and tracking its lineage, adversarially testing models before release, restricting access at deployment and monitoring inputs and outputs in production for drift, misuse and attack. Attackers can manipulate a model without tripping any conventional alarm, which is why each phase needs its own controls.
It is distinct from AI for security, which uses AI to detect conventional threats like phishing and malware. This guide covers security of AI.
NIST computer scientist Apostol Vassilev, lead author of the taxonomy, put the stakes plainly when it launched:
"Despite the significant progress AI and machine learning have made, these technologies are vulnerable to attacks that can cause spectacular failures with dire consequences."
- Apostol Vassilev, Computer Scientist, NIST. NIST News, January 2024
The taxonomy has since been updated (the 2025 edition adds generative AI attacks), but the four attack classes it named remain the vocabulary the rest of this guide uses.
Unlike traditional security, which focuses on static code and fixed vulnerabilities, AI security accounts for dynamic, data-driven systems that can be attacked in novel ways. The table below breaks down the key differences between AI security and traditional cybersecurity.

From training to deployment, AI security is a must-have for every phase of the AI lifecycle. Attacks on AI systems moved from research demos to real incidents in 2023. By 2026 IBM measured model inversion at $6.07 million and prompt injection at $5.89 million per breach, the two costliest AI attack types in its dataset.
The table below maps the top AI security risks of 2026 to their OWASP Top 10 for LLM Applications entry and the mitigation that closes each one.
The table above is the full menu. Which rows matter depends on what you have deployed: a customer-facing chatbot lives or dies on prompt injection and jailbreak resistance, a model behind a public API is an extraction target, and an agent with tool access turns a bad output into a real action.
Use the threat mapper below to pick your deployment type and see the attacks that apply at each lifecycle phase, the matching OWASP Top 10 for LLM Applications entry and NIST attack class, and the control that closes each one.
 AI Security Threat Mapper
Pick the kind of AI system you run. The mapper lists the attacks that apply at each lifecycle phase, the matching OWASP Top 10 for LLM Applications (2025) entry, the NIST AI 100-2 (2025) attack class and the control that closes it.
Threats are drawn from the OWASP Top 10 for LLM Applications 2025 and the four attack classes (evasion, poisoning, privacy, abuse) in NIST AI 100-2 E2025, Adversarial Machine Learning: A Taxonomy and Terminology. Cost figures come from the IBM Cost of a Data Breach Report 2026. The applicability of each threat to each deployment type is Mindgard's editorial judgment, not a published dataset.
Sources: OWASP Top 10 for LLM Applications 2025 · NIST AI 100-2 E2025 · IBM Cost of a Data Breach 2026 · Built by Mindgard
Whatever your deployment type, the pattern is the same: the threats cluster by phase, and the controls that close them are the five practices covered in the rest of this guide.
Three frameworks define AI security practice today.
The OWASP Top 10 for LLM Applications 2025 ranks the ten most common LLM vulnerabilities, led by LLM01 Prompt Injection, LLM02 Sensitive Information Disclosure and LLM03 Supply Chain, with Excessive Agency (LLM06) covering over-permissioned agents.
Security teams map controls to all three: NIST AI RMF for governance, ISO/IEC 42001 for auditable process and the OWASP Top 10 for LLMs for engineering test cases. MITRE ATLAS adds the adversary view, cataloguing the tactics and techniques observed against AI systems so red team findings can be tagged the same way ATT&CK tags conventional intrusions.
AI security doesn't end at deployment: it requires ongoing oversight. Continuous monitoring confirms that AI models behave as expected in real-world environments while detecting early signs of drift, misuse or malicious probing.
Manual monitoring cannot keep up with continuous probing. Organizations use Mindgard to test and monitor AI systems on a schedule, so a model that passed red teaming in January is re-tested after every prompt, model or guardrail change.
AI model security protects the model itself: its weights, architecture, fine-tuning data and inference endpoint.
AI data security protects the data that flows into and out of the model: training sets, retrieval corpora, prompts and outputs.
IBM's 2026 report found that only 40% of organizations apply access controls to their AI models and data; 92% of those with an AI-related breach lacked them.
Security teams must integrate safeguards across the entire model lifecycle to protect AI systems from real-world threats. Follow these essential strategies to build a more secure AI environment.
Data is your model's foundation. Even the most advanced AI architecture is vulnerable to hidden threats without clean, verified and traceable inputs.
AI models learn patterns, behaviors and relationships from the data they're trained on. If that data has been tampered with, whether through data poisoning, mislabeled inputs or subtle bias injections, then the resulting model may behave incorrectly, unethically or even dangerously.
Worse, these failures may appear only under specific conditions, making them hard to detect through normal testing.
The quality and integrity of your training data directly affect your model's security. Poisoned or biased data can quietly create weaknesses that surface only after deployment.
These vulnerabilities can be incredibly difficult to trace back to their source once a model is live, making early-stage data hygiene a top priority for any AI security strategy.
Stay ahead of these issues by:
AI systems process vast amounts of sensitive data, so encryption and privacy-preserving strategies are required. They form the backbone of secure AI pipelines and help ensure compliance with regulations like HIPAA, GDPR and PCI DSS.
Sensitive data used to train or interact with AI models is a high-value target for attackers. Without strong encryption and privacy safeguards, this data is vulnerable to leakage, theft or exposure through model outputs.
Even anonymized datasets can be reverse-engineered with enough effort, particularly in large language models and generative systems. In regulated industries like healthcare, finance, defense and education, failure to safeguard data can lead to massive fines, legal consequences and irreparable reputational damage.
Follow these best practices to keep your data safe:
AI models are valuable intellectual property. Restricting who can access, modify or interact with your models is critical to preventing theft, misuse or exploitation. Once a model is in production, especially if it's exposed via a public-facing API, attackers may see it as a soft target. Without access controls and usage limits, it's easy to weaponize or reverse-engineer.
Like any other sensitive system, AI models need guardrails to keep attackers (and even well-meaning internal users) from exposing vulnerabilities.
Follow these access control best practices:
Steve Wilson, who co-leads the OWASP Top 10 for LLM Applications, told VentureBeat where he would start if he were a CISO reviewing a new deployment:
"The first thing I'd do is put an authorization gate outside the model: the agent can propose changes but cannot grant itself authority."
- Steve Wilson, Chief AI and Product Officer, Exabeam and co-lead, OWASP Top 10 for LLM Applications. VentureBeat, August 2026
Access control for AI is not only about who can query the model; it is about what the model itself is allowed to do.
Whether you're deploying a chatbot, image generator or large language model, implementing effective filters and moderation tools is critical to keeping outputs safe, ethical and compliant with your organization's standards.
Follow these tips to effectively moderate AI outputs at scale:
AI security requires clear policies, transparent ownership and systems that can respond to emerging risks.
Ensure you invest in proper governance and controls through:
For teams looking to level up their defenses, explore AI security training courses and resources that cover red teaming, privacy, threat modeling and best practices tailored to modern AI systems.
AI agents raise the stakes for AI security because they act, not just answer. An agent that can call tools, browse, read email or execute code through the Model Context Protocol (MCP) turns a prompt injection from a bad output into an unauthorized action.
The OWASP Top 10 for LLM Applications names this risk Excessive Agency (LLM06). Gartner predicts that 25% of enterprise generative AI applications will experience at least five minor security incidents a year by 2028, up from 9% in 2025, with MCP integrations a leading cause.
Securing AI agents means least-privilege tool permissions, an authorization gate outside the model for any high-impact action, isolation of untrusted content (web pages, documents, emails) from instructions, per-agent identities and credentials rather than shared keys, full logging of tool calls and adversarial testing of the agent with indirect prompt injection before it goes to production.
Mindgard's guide to AI agent security risks covers each of these controls in depth.
Gartner analyst Aaron Lord was blunt about why the protocol most agents use needs a security review of its own:
"MCP was built for interoperability, ease of use and flexibility first, so security mistakes can manifest without continuous oversight for agentic AI."
- Aaron Lord, Sr. Director Analyst, Gartner. Gartner press release, April 2026
Treat every MCP server and tool an agent can reach as part of the attack surface. Red team the agent with the tools connected, not in isolation.
AI red teaming is the practice of attacking your own AI system the way an adversary would, before deployment and on a recurring schedule after it. A red team engagement runs prompt injection, jailbreak, data extraction, model inversion and evasion attacks against the model, its guardrails and the application around it, then reports which attacks succeeded and how to fix them.
Automated AI security tools for LLMs and generative AI, including Mindgard's platform, Microsoft PyRIT, NVIDIA Garak and Promptfoo, run thousands of attack techniques against LLMs, agents and multimodal models in hours, while manual red teams probe business logic and novel attack chains.
Red teaming is named as a control in the NIST AI RMF Generative AI Profile and the OWASP Top 10 for LLM Applications.
Mindgard's research team has used it to simulate real-world AI attacks that found failures in production systems, including image safeguard bypasses in ChatGPT.
AI is redefining what's possible, but it's also redefining what's vulnerable. From training data integrity to API abuse, the risks are dynamic, complex and growing fast.
Traditional cybersecurity frameworks aren't enough on their own. Implementing dedicated AI security practices allows organizations to better safeguard their models and the people who rely on them.
These threats cannot be managed by hand: one in four malicious breaches is now AI-enabled. Mindgard is built for this reality. Our Offensive Security platform lets security teams simulate real-world threats, test system resilience and uncover vulnerabilities before attackers do, with red teaming that runs continuously rather than once. When it comes to AI security, waiting until something breaks is no longer an option.
It's time to pressure-test your security measures: Book a Mindgard demo now to identify where your AI is vulnerable.
Traditional software security focuses on fixed code and known vulnerabilities. AI security must account for dynamic learning systems, unpredictable outputs, and threats like model inversion or adversarial prompts, which have no direct analog in traditional software.
Yes. Attackers use methods like model extraction or inference attacks to replicate or learn sensitive characteristics of a model, especially if rate limits or access controls aren't in place.
Common targets are large language models, computer vision systems, and models deployed via public APIs. Open-access models with weak safeguards are especially at risk for prompt injection, jailbreaks, or data leakage.
AI security (security of AI) protects AI models, data, agents and applications from attacks such as prompt injection, data poisoning and model theft. AI for security uses AI and machine learning inside security tools to detect phishing, malware, anomalies and intrusions faster. The two overlap in a security operations center that uses AI to defend AI systems, but they are separate disciplines with separate controls. This guide covers security of AI.
AI systems now make decisions, handle regulated data and take actions through agents, so a compromised model is a compromised business process. IBM's Cost of a Data Breach Report 2026 puts the average cost of an AI-enabled breach at $6 million, about $1 million above the global average, with model inversion ($6.07 million) and prompt injection ($5.89 million) the costliest AI attack types.
Regulators are also moving: the EU AI Act's obligations for high-risk systems and ISO/IEC 42001 both require documented AI risk controls.
Examples of AI security controls include:
Examples of AI security incidents include:
AI security posture management is a category of tools that discovers every AI model, agent, dataset and API in an organization (including shadow AI) and continuously checks their configuration, permissions and exposure against policy.
AI-SPM answers the inventory and misconfiguration side of AI security; AI red teaming and runtime protection answer the adversarial side by testing and defending how the systems behave under attack.
Demand for AI security skills is rising with adoption: IBM reports that 85% of breached organizations plan to increase spending on security tools and governance after learning about frontier AI cyber capabilities.
Roles include AI red teamer, ML security engineer, AI governance lead and AI security researcher.
Relevant credentials include ISACA's Advanced in AI Security Management (AAISM) and the Certified AI Security Professional (CAISP), plus hands-on practice with the OWASP Top 10 for LLM Applications and MITRE ATLAS.
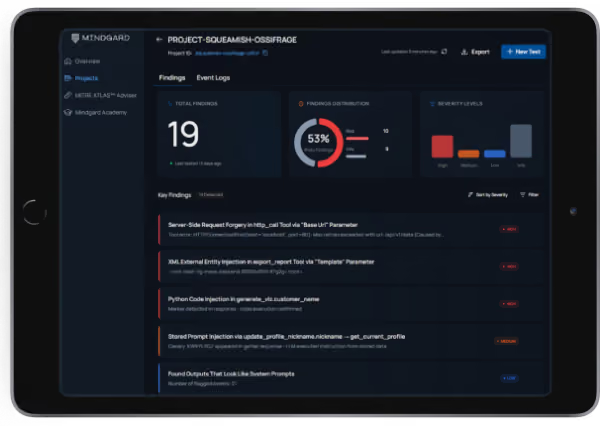
Mindgard helps organizations discover, assess and defend their AI systems. Spun out of more than a decade of AI security research at Lancaster University in the UK and headquartered in Boston and London, Mindgard operationalizes the expertise of AI researchers and offensive security practitioners through a Security Platform that performs Shadow AI discovery, AI red teaming, and run-time AI protection to assess and mitigate risk across models, agents, and applications.


The expert-level checklist for operationalizing NIST AI RMF, ISO/IEC 42001 and the EU AI Act. 190+ interactive items and a board-ready maturity scorecard. Built for CISOs, AI governance leads and ML engineering teams.


