AI data security is the practice of protecting the sensitive data that trains and runs artificial intelligence systems and the AI models themselves at every stage of the AI lifecycle.
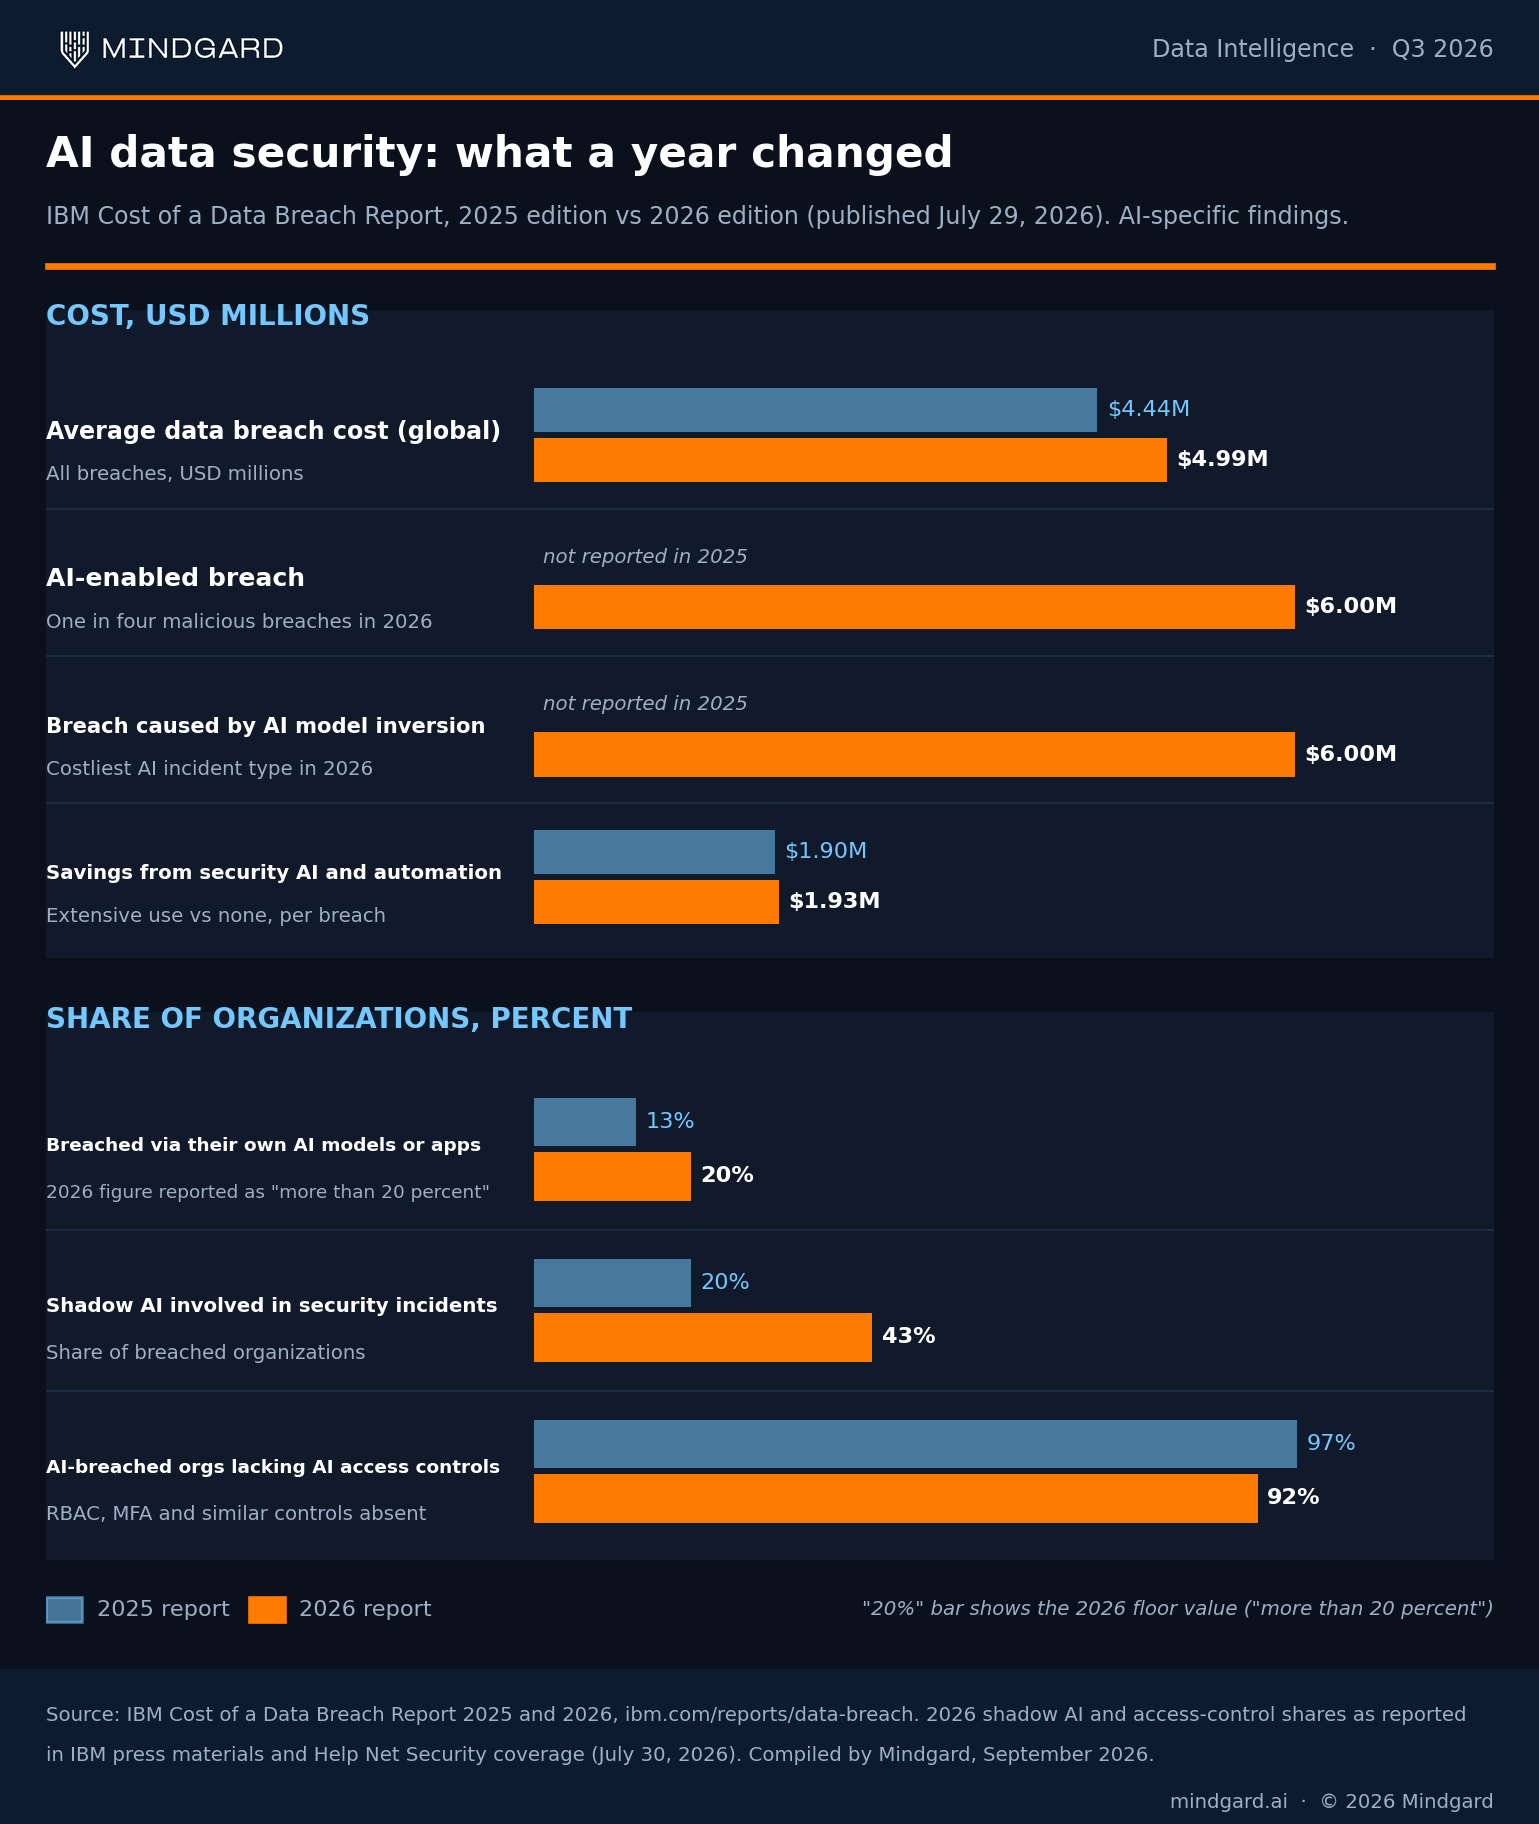
The cost of getting it wrong is now measured. IBM's 2026 Cost of a Data Breach Report puts the average AI-enabled breach at $6.0 million, about $1 million above the $4.99 million global average. One in four malicious breaches in the study was AI-enabled. More than 20 percent of organizations reported a breach involving their own AI models or applications. 92 percent of those organizations lacked role-based access, multifactor authentication or similar controls on their AI systems.
AI data security covers the full lifecycle: data collection, training, fine-tuning, inference and agent deployment. It treats training data, prompts, embeddings, model weights and outputs as security-sensitive assets and defends them against data poisoning, prompt injection, model inversion, training-data leakage, model theft and shadow AI exposure. None of those threats is stopped by legacy security tooling on its own.
The control set combines traditional data protection (encryption, role-based access, data classification, masking and DLP) with AI-specific controls: data provenance, prompt filtering, output sanitization, model behavior monitoring and continuous AI red teaming. Those controls are defined in the NIST AI Risk Management Framework, the OWASP Top 10 for LLM Applications (2026) and the CISA / NSA Joint Cybersecurity Information on AI Data Security (May 22, 2025).
AI data security risks are not a single list of vulnerabilities. They are twelve distinct attacks against four different surfaces. The control that stops one rarely stops another.
Data poisoning and training-data leakage attack the training set. Model inversion, membership inference and model extraction attack the model. Direct prompt injection, jailbreaking, adversarial inputs and improper output handling attack inference. Indirect prompt injection, excessive agency and shadow AI attack the agent and RAG pipeline. Ten of the twelve carry an identifier in the OWASP Top 10 for LLM Applications (2026). The other two, adversarial inputs and shadow AI, come from MITRE ATLAS and IBM's 2026 breach data.
The table below gives each threat its attack surface, a severity rating and the primary control that stops it. Filter by severity or by AI surface to see only what applies to the systems you run.
Three attacks account for most AI data security incidents. Each one targets a different point in the lifecycle.
None of the three requires stolen credentials or a foothold on the network. The input is the attack surface.
Model inversion is also the costliest of the twelve: IBM's 2026 report puts the average breach caused by one at $6 million, the highest of any AI incident type in the study. Let's look at each of the top threats in detail.
In data poisoning attacks, the adversary inserts crafted examples into training data, fine-tuning data or retrieval corpora used by RAG models. Data poisoning aims to affect what the model has learned.
The dose required is small. A joint study by Anthropic, the UK AI Security Institute and the Alan Turing Institute found that as few as 250 malicious documents can plant a backdoor in a large language model regardless of model size or training-data volume (October 2025). Earlier, researchers at NYU Langone showed in Nature Medicine that replacing 0.001 percent of training tokens with medical misinformation raised a 4-billion-parameter model's harmful outputs by 4.8 percent while it still passed standard medical benchmarks.
Once compromised, a model keeps functioning normally while producing biased or manipulated results. Prevention measures include data provenance, dataset signing, version control and anomaly detection on training sets.
Prompt injection happens when user input or content extracted from another source contains instructions for the model that bypass the limitations set in its system prompt. As a result, the model ignores its guardrails, leaks data or performs unauthorized actions. Prompt injection can be direct or indirect.
For indirect prompt injection, an adversary embeds instructions into a document, email, webpage or a database entry. As the model trusts information provided by its own pipeline, it follows the instructions. Mitigation strategies include system prompt isolation and sanitization of content from untrusted sources, structured input/output format and gated tool calls.
Model inversion is a privacy threat in which an adversary uses specially selected queries to deduce some parts of the model's training data. Model inversion exploits the fact that models carry signatures of their training datasets. PII, medical or proprietary data pose the most threat to the model due to being especially sensitive.
It is also the most expensive AI incident type on record: IBM's 2026 report puts the global average cost of a breach caused by an AI model inversion attack at $6 million.
AI data security is the practice of protecting the data inside AI systems, meaning training data, prompts, embeddings, model weights and outputs, together with the AI models themselves, across the entire AI lifecycle. That lifecycle covers collection, preprocessing, training, fine-tuning, inference and decommissioning.
The definition aligns with the CISA / NSA Joint Cybersecurity Information on AI Data Security published May 22, 2025.
"Data security is a critical enabler that spans all phases of the AI system lifecycle. Successful data management strategies must ensure that the data has not been tampered with at any point throughout the entire AI system lifecycle. The data must be free from malicious, unwanted and unauthorized content. It must not have unintentional duplicative or anomalous information."
- Source: CISA, NSA, FBI, Australian Signals Directorate, UK NCSC and New Zealand GCSB. Joint Cybersecurity Information: AI Data Security, May 22, 2025.
These three terms get used interchangeably, but they aren't the same. Here's how the differ from one another.
AI data security sits at the intersection. It treats training data, prompts, embeddings, model weights and outputs as security-sensitive assets in their own right.
Protecting AI training data and inference data means applying a different control set at each stage of the AI lifecycle, because the data changes shape as it moves. Training data security starts with provenance: record where every dataset, fine-tuning set and retrieval corpus came from, sign it and version it so tampering is detectable and scan it for poisoned or duplicated records before a training run.
The CISA / NSA Joint Cybersecurity Information on AI Data Security calls for exactly this, plus encryption of training datasets and model weights at rest and in transit. Inference data security protects what enters and leaves the model in production: prompts, retrieved documents, embeddings and outputs. The controls are input filtering for prompt injection, output redaction for training-data leakage, query rate limits against model inversion and model extraction plus least-privilege access to vector databases and model APIs.
Continuous AI red teaming tests both halves against the OWASP Top 10 for LLM Applications before an attacker does.
Provenance matters more each year because the training corpus itself is increasingly synthetic or scraped. Tools such as Nightshade exist specifically to poison scraped image data. Gartner expects verification of AI-generated data to become a governance requirement.
Gartner's data and analytics practice put the same point in governance terms in January 2026:
"Organizations can no longer implicitly trust data or assume it was human generated. As AI-generated data becomes pervasive and indistinguishable from human-created data, a zero-trust posture establishing authentication and verification measures, is essential to safeguard business and financial outcomes." - Wan Fui Chan, Managing Vice President, Gartner. Gartner press release, January 21, 2026.
Gartner predicts that half of organizations will adopt a zero-trust posture for data governance by 2028 for that reason. For AI training pipelines, provenance and signing are how that posture is implemented.
Traditional approaches to data security depended on manual effort and predefined rules. Firewalls, signature-based detection and static access permissions cannot keep up with zero-day exploits, insider threats or the new class of attacks targeting AI systems.
AI data security extends traditional cybersecurity with machine learning, real-time anomaly detection and continuous automated red teaming. That last control is specifically recommended by the NIST AI Risk Management Framework's MEASURE function.
It is also expected of high-risk AI systems under Article 15 of the EU AI Act, which applies to stand-alone high-risk systems from December 2, 2027. The result is a control set that adapts as fast as the attack surface.
Four authoritative frameworks define what an AI data security program should look like in 2026.
The NIST AI Risk Management Framework is the U.S. National Institute of Standards and Technology's reference for managing AI risk. It is organized around four functions.
IBM's 2026 study found that close to seven in ten breached organizations lacked a governance policy for managing AI or spotting unapproved use. Fewer than one in five coordinate their AI governance teams with their security teams. The GOVERN function exists to close that gap.
The OWASP Top 10 for LLM Applications (2026) is the de facto industry list of the most critical risks in large language model deployments. The 2026 edition, released September 2, 2026, is the first to weigh the community ranking against a large body of real incident data.
Prompt Injection (LLM01) and Sensitive Information Disclosure (LLM02) hold the top two positions. Excessive Agency climbs to LLM03. Data and Model Poisoning is LLM05, Vector and Embedding Weaknesses is LLM09 and Improper Output Handling is LLM10.
Seven of the ten map directly to data inside the AI system, which is why the threat table above uses the 2026 identifiers. A companion OWASP Top 10 for Agentic Applications adds Memory and Context Poisoning (ASI06) for agent pipelines.
The CISA / NSA paper published May 22, 2025 was the first multi-agency multi-country guidance focused specifically on data security in AI systems. It is co-signed by U.S. CISA and NSA, the FBI, the Australian Signals Directorate, the UK NCSC and New Zealand's GCSB. The paper calls for cryptographic protection of training datasets and model weights at rest and in transit. It also calls for digital signatures on training data so any tampering becomes detectable.
Article 15 of the EU AI Act requires that high-risk AI systems be designed and developed to be resilient against attempts to alter their use, behavior or performance by exploiting their vulnerabilities. The Article specifically calls out data poisoning, model poisoning and adversarial examples as attacks that high-risk systems must resist. Continuous red teaming is the established way to demonstrate that resilience.
The timeline moved in 2026. The Digital Omnibus on AI, in force since July 27, 2026, defers the obligations for stand-alone high-risk systems (Annex III) to December 2, 2027 and for AI embedded in regulated products (Annex I) to August 2, 2028. Non-compliance with high-risk obligations carries fines of up to EUR 15 million or 3 percent of worldwide annual turnover, whichever is higher.
IBM's 2026 Cost of a Data Breach Report makes the financial case for AI data security in four numbers.
A second set of numbers explains the gap. More than 20 percent of organizations reported a breach involving their own AI models or applications, most often through compromised APIs, applications or plug-ins (27 percent) or cloud misconfigurations (27 percent).
Of those organizations, 92 percent were missing role-based access, multifactor authentication and similar controls on their AI systems. Mean time to identify and contain a breach rose to 247 days, reversing five straight years of decline.
Organizations that used AI and automation extensively in security saved $1.93 million per breach compared with organizations using none. That remains the single largest cost-reducing factor in the study. One in four organizations has still not adopted those tools.
IBM's own reading of the numbers is blunt:
"What's changing is the economics of cyberattacks. AI is making attacks faster and cheaper, while breaches keep getting more expensive."
- Suja Viswesan, Vice President, IBM Security Software. IBM Newsroom, July 29, 2026.
The lag she describes is exactly where AI data security controls pay for themselves: access controls stop the breach, red teaming finds the gap first and runtime monitoring closes the discovery window.
Shadow AI refers to the use of AI tools and services without the knowledge or approval of the organization's security and governance teams. Common examples include employees pasting customer data into a consumer chatbot, developers integrating an undocumented LLM API into a production service and product teams shipping AI features without a model security review.
IBM's 2026 study found that workers using unapproved AI tools figured in 43 percent of security incidents, more than double the prior year's share. Those incidents cost more than they did a year earlier.
The volume behind that number is large. Zscaler ThreatLabz logged 18,033 terabytes of enterprise data sent to AI and machine learning applications in 2025, a 93 percent year-over-year increase, plus 410 million data loss prevention violations tied to ChatGPT traffic alone. Netskope found the average organization now generates 223 GenAI-related data policy violations per month and that 47 percent of GenAI users still reach those tools through personal, unmanaged accounts.
The cause is simple. Shadow AI tools sit outside DLP, IAM, logging and incident-response coverage. When something goes wrong the security team often does not know the tool exists.
Gartner expects more than 40 percent of organizations to suffer a security or compliance incident from unauthorized AI tool use by 2030. Its prescription maps to the three controls below:
"To address these risks, CIOs should define clear enterprise-wide policies for AI tool usage, conduct regular audits for shadow AI activity and incorporate GenAI risk evaluation into their SaaS assessment processes."
- Arun Chandrasekaran, Distinguished Vice President Analyst, Gartner. Reported by Infosecurity Magazine, November 20, 2025.
Mitigation involves three controls working together.
AI data security involves the following core components:
AI model security also defends large language models (LLMs) against adversarial attacks such as model inversion attacks, data poisoning and bias. Addressing these risks is essential for effective AI data security and for building safe, compliant AI systems.
AI is used in data security for four operational jobs: real-time monitoring, anomaly detection, data loss prevention and insider-threat detection.
Examples of AI in data security include machine learning models that baseline normal user and agent behavior and flag outliers, classifiers that find and label sensitive data at rest and in motion, runtime AI security tools that detect prompt injection and data exfiltration in model traffic. A fourth example is behavioral analytics that spot compromised credentials.
IBM's 2026 Cost of a Data Breach Report found that organizations using AI and automation extensively in security saved $1.93 million per breach compared with organizations using none.
AI data security best practices start with visibility and end with continuous testing. Security teams should inventory every AI system and its data flows, classify each by risk, restrict access to models and data with role-based access control and multi-factor authentication, apply data loss prevention to prompts and outputs, encrypt training data and model weights, red-team production models continuously and monitor for prompt injection at runtime.
The ten-step checklist below groups these AI data security practices under the four NIST AI RMF functions so it doubles as a maturity model.
Pick a stage. See the threats that target data at that stage, tick the controls you already run and get a coverage score with the framework references you will need for an audit.
Enterprise RAG security and agentic AI security come down to defending against two attacks: indirect prompt injection and data poisoning of the retrieval corpus. In indirect prompt injection an attacker plants instructions in a document, email, web page or database record that the agent will later retrieve.
The model then executes them as if they came from the user. In RAG data poisoning the attacker corrupts the retrieval corpus or the vector database itself so the model grounds its answers in false or malicious content. OWASP ranks prompt injection as LLM01 and vector and embedding weaknesses as LLM09 in the 2026 Top 10 for LLM Applications.
Defense against both requires four controls: document provenance and signing for everything in the retrieval corpus, content sanitization and untrusted-source labeling before retrieved text reaches the model, tool-call gating with human approval for any action that has a real-world side effect plus continuous red teaming of the full agent pipeline rather than the base model alone.
Every tool the agent can call is also an excessive-agency risk. Every embedding in the vector database is a potential model-inversion target, so log every retrieval, tool call and output to a SIEM with rules tuned for AI-specific anomalies. Our guide to AI agent security risks covers memory poisoning and privilege misuse in more depth.
Simon Willison, whose 'lethal trifecta' framing is now standard vocabulary for agent security, defines the three features as access to private data, exposure to untrusted content and the ability to communicate externally:
"If your agent combines these three features, an attacker can easily trick it into accessing your private data and sending it to that attacker. The only way to stay safe there is to avoid that lethal trifecta combination entirely."
- Simon Willison, independent researcher and creator of Datasette, 'The lethal trifecta for AI agents,' June 16, 2025.
Tool-call gating and untrusted-source labeling break the trifecta at its weakest link. Continuous red teaming proves that they hold as the agent's tools and corpus change.
"Traditional penetration testing assumes a fixed attack surface. AI systems do not have one. Every new prompt, every new tool the agent is given and every new document in the RAG index expands the surface. The only way to keep up is continuous automated red teaming that runs against the production system, not a one-off audit." - Dr. Peter Garraghan, CEO and CTO, Mindgard.
Automated LLM red teaming frameworks test whether an AI system leaks, poisons or misuses data before an attacker does.
Three tools cover most enterprise programs in 2026.
Open-source frameworks suit one-off assessments; continuous automated red teaming is the control that NIST AI RMF MEASURE and EU AI Act Article 15 expect for production systems.
For a longer comparison, see our round-ups of the best AI security tools for LLM and GenAI and the top AI pentesting tools.
Five regulatory pressures now shape AI data security obligations.
Start with the two controls that the IBM numbers single out. Put role-based access and multifactor authentication on every model API, fine-tuning job and vector database, because 92 percent of organizations with an AI incident had not. Then test the systems you already run: continuous red teaming finds the poisoned corpus, the leaky prompt and the over-privileged agent before an attacker does. It is the evidence the NIST AI RMF and Article 15 of the EU AI Act ask for.
Mindgard's Offensive Security solution runs that testing against production AI systems and feeds the findings into the SIEM your team already uses. Book a demo today.
Yes. Modern AI data security tools integrate with SIEM platforms such as Splunk, Sentinel and Chronicle. They also integrate with SOAR, EDR/XDR, IAM, CSPM and DLP tools via OpenAPI, webhook or native connectors. Findings from AI red teaming and runtime protection appear alongside traditional findings in the same workflow.
AI cannot directly analyze encrypted data content. It can detect suspicious patterns in metadata, access logs and user behavior associated with encrypted files. Examples include unusual download patterns or access from unknown devices.
Yes. AI systems face threats traditional software does not. The OWASP Top 10 for LLM Applications (2026) enumerates ten of them, including prompt injection, sensitive information disclosure and excessive agency. Defense requires data provenance, model integrity verification, query rate limits, output validation and regular red-team testing.
Data poisoning is an attack where an adversary inserts crafted examples into training, fine-tuning or RAG data to change a model's behavior. Research shows the dose is small: 250 malicious documents were enough to backdoor models of any size in a 2025 Anthropic study. 0.001 percent of training tokens raised harmful medical outputs by 4.8 percent in a Nature Medicine study.
AI data security extends traditional cybersecurity with machine-learning anomaly detection, automated response and continuous red teaming of the model and pipeline. It also protects AI-specific assets such as training data, model weights, embeddings and agent tools that traditional cybersecurity does not address.
IBM's 2026 Cost of a Data Breach Report puts the global average at $4.99 million. The average AI-enabled breach cost $6.0 million, about $1 million more. The average breach caused by an AI model inversion attack cost $6 million. The U.S. average across all breaches was $11.5 million.
The four most commonly used are the NIST AI Risk Management Framework, the OWASP Top 10 for LLM Applications (2026), the CISA / NSA Joint Cybersecurity Information on AI Data Security (May 22, 2025) and Article 15 of the EU AI Act for high-risk AI systems operating in or selling into the EU, enforceable from December 2, 2027.
You can protect your data from AI by controlling what you share with AI tools and what those tools are allowed to reach.
If you run AI systems for an organization, protect your data from AI misuse with an acceptable-use policy, a sanctioned AI gateway with data loss prevention, role-based access and multi-factor authentication on every model API and vector database plus encryption of training data and model weights.
IBM's 2026 Cost of a Data Breach Report found that 92 percent of organizations with an AI-related incident lacked those access controls.
Data security posture management for AI is the continuous discovery, classification and monitoring of the data that AI systems can reach: training sets, fine-tuning data, vector databases, prompt logs and model outputs.
DSPM for AI answers three questions: which sensitive data is exposed to which models and agents, who and what can access it and whether that access matches policy. It complements AI red teaming, which tests whether the model itself can be made to leak or misuse that data.
The CISA / NSA guidance frames the same requirement as tracking data provenance and integrity across the AI lifecycle.
AI data security protects data and models from unauthorized access, tampering, leakage and theft through technical and operational controls. AI data privacy governs whether an organization may collect and process personal data in an AI system at all and on what lawful basis, under regimes such as GDPR and HIPAA.
A system can be secure and still violate privacy if it trains on data it had no right to use; it can be privacy-compliant and still insecure if that data is exposed through prompt injection or model inversion.
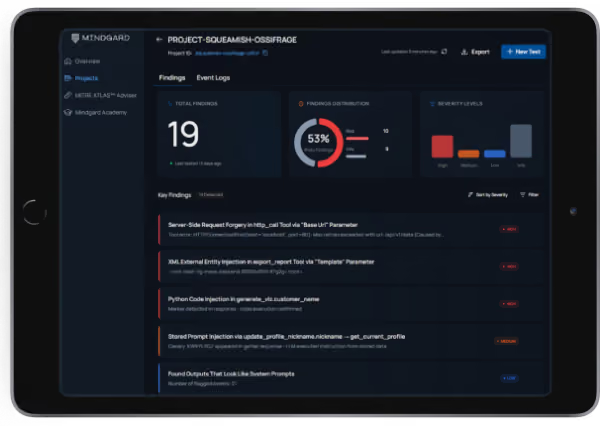
Mindgard helps organizations discover, assess and defend their AI systems. Spun out of more than a decade of AI security research at Lancaster University in the UK and headquartered in Boston and London, Mindgard operationalizes the expertise of AI researchers and offensive security practitioners through a Security Platform that performs Shadow AI discovery, AI red teaming, and run-time AI protection to assess and mitigate risk across models, agents, and applications.


The expert-level checklist for operationalizing NIST AI RMF, ISO/IEC 42001 and the EU AI Act. 190+ interactive items and a board-ready maturity scorecard. Built for CISOs, AI governance leads and ML engineering teams.


