Contact Us

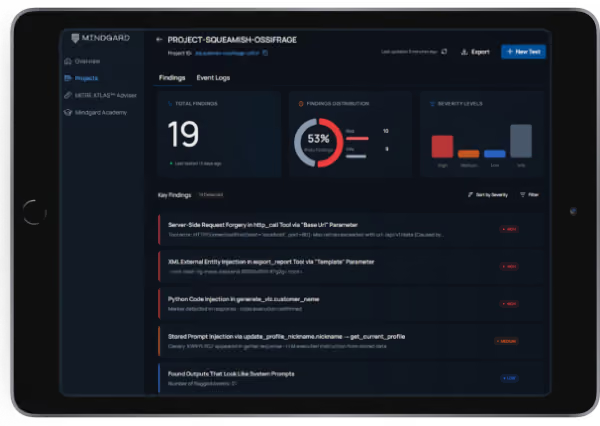
Mindgard's researchers attack your AI systems the way a motivated adversary would: prompt injection, agent hijacking, tool abuse, data extraction and guardrail bypass, chained into the attack paths that matter to your business. You get reproducible findings, a remediation roadmap and a platform that keeps testing after we leave.
A Mindgard AI security expert replies within one business day.
Every Mindgard red team engagement ends with five things your security team can act on the same week:
Mindgard red teams the whole AI system, not just the model. Scope typically covers:
The techniques below are the core of every engagement. Each maps to a public taxonomy so your findings speak the same language as your auditors and your engineering backlog.
Five phases. Typical elapsed time from kickoff to final readout is four to six weeks for a single AI application.
Red teaming is now a named obligation, not a nice-to-have. Article 55 of the EU AI Act requires providers of general-purpose AI models with systemic risk to perform and document adversarial testing. ISO/IEC 42001 asks for AI risk assessment and treatment with evidence. The NIST AI RMF Measure function expects AI systems to be evaluated for security and resilience against adversarial input.
A Mindgard red team engagement produces the evidence each of these asks for: the threat model, the test record, the findings mapped to a public taxonomy and the retest confirming remediation. If your governance team needs a specific artifact, tell us during scoping and we build the report to fit. Talk to us about compliance-ready red teaming.

Yes. The report is structured as adversarial-testing evidence: threat model, test record, findings mapped to OWASP and MITRE ATLAS and a retest record. It supports EU AI Act Article 55 obligations, ISO/IEC 42001 risk treatment evidence and the NIST AI RMF Measure function.
Engagements are priced by scope: the number of AI systems, the attacker profiles emulated and whether retest and platform onboarding are included. A single-application engagement is typically a four to six week project. Tell us what you are deploying and we will send a scope and a quote within two business days.
LLM chat applications, RAG pipelines, AI agents and multi-agent systems, MCP tool integrations, guardrail products, fine-tuned and open-weight models and multimodal systems that accept images, audio or documents.
Rules of engagement are agreed before any testing starts. We test against a staging mirror where one exists and use rate limits, safe payloads and agreed windows when production is in scope. Destructive actions are simulated, never executed.
No. Most engagements run black-box or grey-box through the same interfaces an attacker would use: the chat endpoint, the API, the agent’s tools. Where you want deeper coverage we can work white-box under NDA.
Red teaming is objective-driven and adversarial: we pick a goal (exfiltrate customer records, make the agent send money) and use any technique to reach it, chaining findings into attack paths. A pentest is scoped, checklist-driven coverage of a defined application against a standard such as OWASP Top 10 for LLM Applications, scored and reported for audit. Most teams start with a pentest and move to red teaming once the basics hold.
An AI red teaming service emulates a real attacker against your AI system to find exploitable weaknesses before someone else does. Mindgard researchers attack the model, its guardrails, the application around it and any agents or tools it can call, then deliver reproducible findings, severity ratings mapped to OWASP and MITRE ATLAS and a remediation roadmap.
Can’t find the answer you’re looking for? Please chat to our friendly team.
Book a demo to watch the Mindgard platform attack a live AI system, or scope a red team engagement with our researchers. Either way you leave with a clearer picture of your AI risk than you had this morning.
A Mindgard AI security lead replies within one business day to confirm scope and set a 30-minute call.
Mindgard secures AI models, agents, and applications against exploitable threats. Spun out of more than a decade of pioneering AI security research at Lancaster University, Mindgard combines offensive security expertise, AI red teaming, attacker intelligence, and automated protection to help organizations discover, assess, and mitigate risk across AI models, agents, and applications.