Generative AI security is the practice of protecting generative AI systems, meaning LLM applications, foundation models, fine-tuning and retrieval data, plugins and AI agents, from adversarial attack, misuse and data exposure.
It matters now because AI is already in the breach data: shadow AI was involved in 43% of breaches in IBM's 2026 Cost of a Data Breach Report, twice the share of a year earlier, and 92% of organizations that suffered an AI-related breach lacked proper AI access controls. The OWASP Top 10 for LLM Applications 2026 ranks prompt injection as the top risk for the third year running.
GenAI also has a tremendous impact on security as a defensive tool, and this guide covers that too. Below you will find the risks, the controls, the frameworks (NIST AI RMF, ISO/IEC 42001, the AWS Generative AI Security Scoping Matrix), a policy checklist and the red teaming and runtime protection steps that prove a GenAI deployment is secure.
Generative AI security is the set of controls, tests and governance processes that protect generative AI systems from attack, misuse and data exposure. A generative AI system includes the foundation model or LLM, the prompts and system instructions, the retrieval-augmented generation (RAG) pipeline and vector database, fine-tuning and training data, plugins and tool integrations plus any agents that act on the model's output.
NIST's Adversarial Machine Learning taxonomy (NIST AI 100-2 E2025, March 2025) groups attacks on these systems into evasion, poisoning, privacy and misuse. It gives generative AI its own section covering direct and indirect prompt injection, supply chain poisoning and agent exploitation. The OWASP Top 10 for LLM Applications 2026 turns that taxonomy into a ranked list of the risks practitioners actually meet: prompt injection, sensitive information disclosure and excessive agency are the top three.
Generative AI security is therefore a subset of AI security, which also covers predictive models, and it is distinct from using generative AI inside security tooling. Both matter. The controls in this guide are for the first problem: keeping the GenAI you deploy from becoming the attacker's way in.
Generative AI security differs from traditional application security in four ways.
Traditional controls such as authentication, least privilege, encryption and logging still apply. GenAI adds model-specific controls: input and output filtering, adversarial testing (AI red teaming), retrieval and memory integrity checks, agent permission scoping and continuous runtime monitoring of model behavior.
The Biggest Generative AI Security Risks in 2026
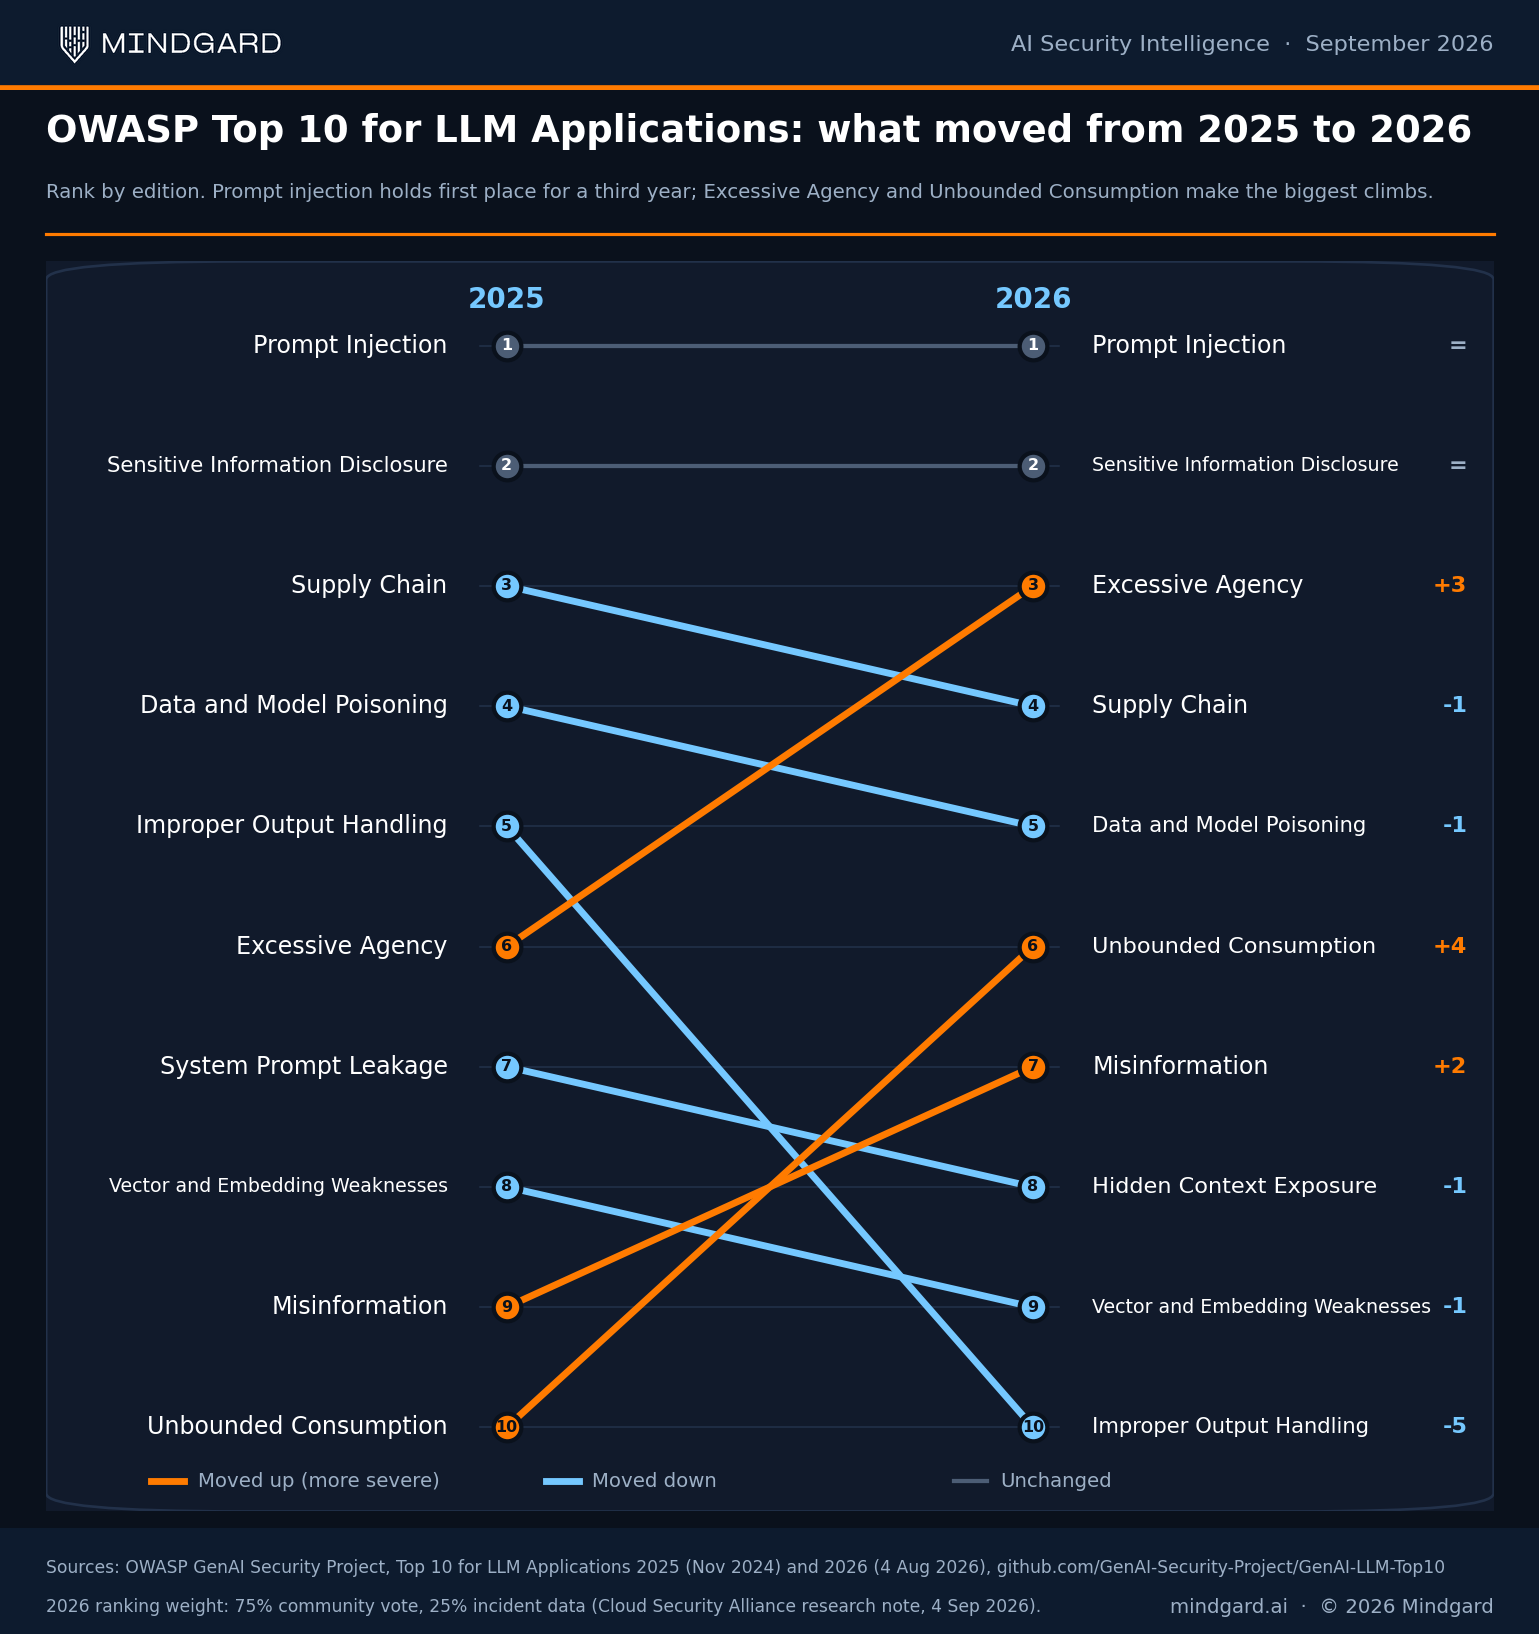
The OWASP Top 10 for LLM Applications 2026, released on 4 August 2026, is the most cited list of generative AI security risks. For the first time the ranking combined community voting (75%) with analysis of 6,639 cataloged real-world AI security incidents (25%).
The 2026 list is:
Prompt injection has held first place for three consecutive editions. Excessive Agency made the largest move because agents now hold credentials and tools: the Cloud Security Alliance found that 53% of organizations had seen an AI agent exceed its intended permissions and 47% had a security incident involving an AI agent in the past year.
OWASP's separate Top 10 for Agentic Applications (December 2025) adds agent behavior hijacking, tool misuse and identity and privilege abuse.
Steve Wilson, who leads the OWASP GenAI Security Project, explained why the 2026 ranking carries more weight than earlier editions:
This update is grounded in much more than expert opinion. OWASP now has a database containing roughly 10,000 real-world AI security incidents."
- Steve Wilson, Co-chair, OWASP GenAI Security Project and Chief AI Officer, Exabeam. SD Times, August 2026
That incident database is why the 2026 list, rather than a vendor's threat model, is the right baseline for a generative AI security program.
Generative AI is used in cybersecurity to analyze threats, generate attack simulations, draft incident responses and surface hidden vulnerabilities, using large language models (LLMs) and code generation tools. Defenders apply GenAI to penetration testing, threat modeling, behavioral analytics and alert triage, which helps teams facing a talent shortage scale defenses, automate threat analysis and reduce response times.
IBM's 2026 Cost of a Data Breach Report found that half of breached organizations were already using AI agents for threat hunting.
Attackers use the same capability: 87% of security professionals in Darktrace's State of AI Cybersecurity 2026 survey say AI is significantly increasing the sophistication and success rate of malware, and 33% of the malicious emails Darktrace observed in 2025 ran over 1,000 characters, a sign of LLM-written phishing.
Every GenAI tool a security team adopts is also a new GenAI system that needs securing, which is why the rest of this guide focuses on protecting the models rather than deploying them.
Organizations need effective guardrails in place to use AI effectively in a high-stakes environment like cybersecurity. The seven controls below map to the OWASP Top 10 for LLM Applications 2026 and to the NIST AI RMF functions of Govern, Map, Measure and Manage.
Partner with vendors that prioritize enterprise-grade security, model explainability and compliance. Reputable providers will offer documented APIs, user access controls and integration support while aligning with industry standards like ISO 27001 or SOC 2. Avoid tools that lack clear privacy policies or allow unchecked data retention.
Mindgard offers continuous protection for AI models. Safeguard your data with continuous automatic red teaming (CART), Offensive Security and Artifact Scanning, complete with our team's expert guidance. It is the best way to blend human expertise with the efficiency of always-on AI.
Protect input and output data through encryption, strict access control, anonymization and data minimization. Establish rules around what types of data can be fed into GenAI tools, especially when dealing with customer records, intellectual property or sensitive internal documentation. Access control is where most programs fail: 92% of organizations that suffered an AI-related breach lacked proper AI access controls in IBM's 2026 report. Our guide to AI data security covers classification, retention and RAG permissions in detail.
Establish internal policies to govern how your team selects, evaluates and uses GenAI. Maintain documentation on:
Map that documentation to the NIST AI Risk Management Framework and its Generative AI Profile, or to ISO/IEC 42001 if you need a certifiable management system. Transparency builds trust internally and externally and ensures responsible use, particularly if you work in a regulated industry.
Simulate adversarial attacks against GenAI systems to uncover vulnerabilities. Red teaming helps expose potential misuse, such as prompt injection attacks, data leakage or harmful outputs. Incorporating GenAI into red team exercises can also reveal weaknesses in how your broader security stack responds to AI-generated threats. The OWASP GenAI Red Teaming Guide structures tests across the model, the implementation, the surrounding system and runtime behavior, and MITRE ATLAS gives red teams a shared language for the techniques they find.
You don't have to figure this out internally, either. Mindgard's off-the-shelf solution combines generative AI security features to keep your business safe and compliant with red teaming as a service.
Microsoft's AI Red Team, after testing more than 100 generative AI products since 2021, reached a conclusion that shapes how red teaming should be scheduled:
"The work of securing AI systems will never be complete."
- Microsoft AI Red Team (Blake Bullwinkel, Ram Shankar Siva Kumar, Mark Russinovich and 23 co-authors). Lessons From Red Teaming 100 Generative AI Products, arXiv 2501.07238, January 2025
That is the argument for continuous automated red teaming over a single pre-launch assessment: every model update, prompt change and new tool integration reopens the attack surface.
Attackers try to manipulate digital infrastructure, including AI models themselves, for nefarious purposes. While the right security setup can prevent most attacks, many hackers target untrained employees for unauthorized access.
From phishing attempts to malware, your team should know the risks. The biggest training gap in 2026 is shadow AI: 65% of organizations had discovered employees using unapproved AI tools with sensitive data in Kiteworks' 2026 survey. GenAI security software can do a lot of the heavy lifting, but it only helps if your team knows which tools are approved and what must never be pasted into them.
Runtime protection inspects every prompt, retrieved document, model output and tool call while the GenAI application is in production. Input filters catch direct and indirect prompt injection and jailbreak attempts. Output filters redact secrets, personal data and system prompt fragments before they reach a user or a downstream system, which addresses OWASP LLM02 (Sensitive Information Disclosure), LLM08 (Hidden Context Exposure) and LLM10 (Improper Output Handling).
Rate limits and token budgets address LLM06 (Unbounded Consumption). Log prompts, outputs and tool calls with user identity so incidents can be reconstructed. Runtime protection complements red teaming: testing finds the weaknesses, runtime controls stop the attacks that testing cannot predict.
Keep an inventory (an AI bill of materials) of every model, dataset, plugin and agent in use, with an owner for each. Give agents their own identities and the minimum permissions their task needs, and require human approval for actions that move money, delete data or send external communications.
The Cloud Security Alliance's 2026 study found 53% of organizations had seen an AI agent exceed its intended permissions, yet only 15% had defined ownership for most of their agents. Excessive Agency is now the third-ranked OWASP LLM risk. Scoping agents is the control that addresses it.
Hillary Baron, who led the Cloud Security Alliance's 2026 agent security study, put the governance gap plainly:
"AI agents are already operating at scale as part of the enterprise digital workforce, but security and governance haven't kept pace with their autonomous actions."
- Hillary Baron, AVP of Research, Cloud Security Alliance. Cloud Security Alliance press release, April 2026
An agent inventory with named owners and scoped permissions is the direct answer to the gap Baron describes.
Six frameworks structure most generative AI security programs.
A generative AI security policy states which GenAI tools and models staff may use, what data may be entered, who owns each system and how it is tested and monitored. Kiteworks' 2026 Data Security and Compliance Risk report found 65% of organizations had discovered employees using unapproved AI tools with sensitive data, and IBM's 2026 report found 68% of breached organizations lacked AI governance to manage AI or detect unsanctioned use.
A working GenAI security policy covers eight items.
Generative AI security tools fall into four categories, matching the control layers in the OWASP AI Security Solutions Landscape.
Most enterprises need one tool from each category; no single product covers testing, runtime and posture together. Use the interactive control mapper below to see which risks and controls apply to your deployment scope.
Pick how you deploy GenAI, what data it touches and how much it can do on its own. The mapper ranks the OWASP Top 10 for LLM Applications 2026 risks that matter most for that profile and names the control and framework reference for each.
Each OWASP 2026 risk starts at its published rank weight (rank 1 = 10 points, rank 10 = 1 point). Deployment scope, data sensitivity and autonomy add points to the risks they expose: agents add to Excessive Agency and Improper Output Handling, RAG adds to Vector and Embedding Weaknesses and Hidden Context Exposure, regulated data adds to Sensitive Information Disclosure and fine-tuned or self-trained models add to Data and Model Poisoning and Supply Chain. The five highest totals are shown. Scores are internally derived from your selections, not survey data.
Sources: OWASP Top 10 for LLM Applications 2026 (rank order) · AWS Generative AI Security Scoping Matrix (scopes) · NIST AI RMF and Generative AI Profile (framework references). Built by Mindgard, September 2026.
Generative AI is changing how organizations approach cybersecurity, automation and decision-making, but its power requires responsible use. You can get GenAI's benefits without compromising your security posture by applying the seven controls above and testing them against the OWASP Top 10 for LLM Applications 2026.
Still, securing GenAI has its challenges. Don't handle everything internally: lean on Mindgard to secure your generative AI systems against adversarial threats.
If you are building, deploying or red teaming with GenAI, our platform helps you identify vulnerabilities before attackers do. Explore Mindgard's AI Security Platform: Book a demo now.
Generative AI security is the practice of protecting generative AI systems, including LLM applications, foundation models, training and retrieval data, plugins and AI agents, from attacks such as prompt injection, data poisoning, sensitive information disclosure and excessive agency. It combines governance (policies, inventories, frameworks such as NIST AI RMF and ISO/IEC 42001), testing (AI red teaming) and runtime protection (input and output filtering, agent permission scoping and monitoring).
The OWASP Top 10 for LLM Applications 2026 ranks the biggest generative AI security risks as prompt injection, sensitive information disclosure, excessive agency, supply chain, data and model poisoning, unbounded consumption, misinformation, hidden context exposure, vector and embedding weaknesses and improper output handling.
Prompt injection has ranked first in every edition since 2023.
The key security concern when using generative AI is data exposure: employees paste confidential data into public tools, models memorize or retrieve sensitive data and return it to the wrong user. Prompt injection tricks an application into revealing it.
IBM's 2026 Cost of a Data Breach Report found shadow AI was involved in 43% of breaches and 92% of organizations with AI-related breaches lacked proper AI access controls.
Generative AI security is tested with AI red teaming: adversarial attacks run against the model, the application and its agents to find prompt injection, jailbreak, data leakage and excessive agency weaknesses. Testing follows the OWASP GenAI Red Teaming Guide and maps findings to the OWASP Top 10 for LLM Applications 2026 and MITRE ATLAS.
Because models change with every update, testing is continuous rather than a one-off assessment.
AI security covers every kind of AI system, including predictive machine learning models used for fraud scoring or image recognition. Generative AI security is the subset that deals with systems that generate content or take actions: LLM applications, image and code generators, RAG pipelines and agents.
GenAI adds risks that predictive models do not have, such as prompt injection, hallucination and agentic tool misuse.
Yes. GenAI systems are vulnerable to adversarial inputs, prompt injection attacks and data poisoning. Security teams should monitor model behavior, validate outputs and apply adversarial testing to mitigate these risks.
Ethical concerns include biased outputs, misuse for surveillance and the potential for automating harmful decisions. Organizations should implement ethical review processes, run bias audits and keep human oversight of automated decisions.
Yes. GenAI can identify behavioral anomalies that suggest insider threats by analyzing communication patterns, access logs and user activity at scale. It complements rule-based tools by spotting subtle indicators that do not trigger fixed rules.
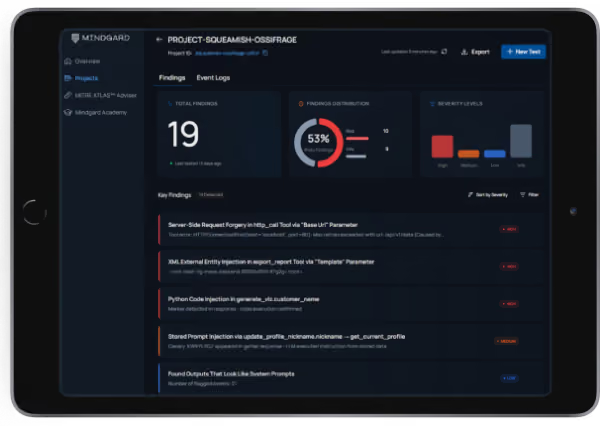
Mindgard helps organizations discover, assess and defend their AI systems. Spun out of more than a decade of AI security research at Lancaster University in the UK and headquartered in Boston and London, Mindgard operationalizes the expertise of AI researchers and offensive security practitioners through a Security Platform that performs Shadow AI discovery, AI red teaming, and run-time AI protection to assess and mitigate risk across models, agents, and applications.


The expert-level checklist for operationalizing NIST AI RMF, ISO/IEC 42001 and the EU AI Act. 190+ interactive items and a board-ready maturity scorecard. Built for CISOs, AI governance leads and ML engineering teams.


