Roughly one in five organizations reported a breach of their AI models or applications in IBM's 2026 Cost of a Data Breach report, and 92% of those had no proper access controls on the AI system. A prompt injection breach now costs an average of $5.89 million. Guardrails are the control most teams reach for first, and the one attackers reach past most often.
LLM guardrails are programmable checks that sit between users, large language models and the tools those models can call. They inspect prompts, retrieved context, model outputs and tool calls, then block, rewrite or escalate anything that breaks policy. Guardrails are a safeguard layer, not the model's own alignment training, and they are not a substitute for testing the model and the application around it.
This guide covers the four layers where LLM guardrails operate, the three mechanisms they use, the frameworks worth knowing in 2026 (NeMo Guardrails, Guardrails AI, Llama Guard 4, OpenAI Guardrails and the cloud-native options), what Mindgard's research found when it attacked six commercial guardrails, and how to implement and test a guardrail stack so it holds up against a real adversary.
LLM guardrails are rule-based or model-based safety controls placed around a large language model to monitor and filter what goes in and what comes out. The guardrail runs outside the model's weights, which means it can be added to a closed API such as GPT-5 or Claude as easily as to an open-weight model you host yourself.
A guardrail layer typically blocks prompt injection and jailbreak attempts on the way in, strips personally identifiable information and off-topic requests, checks outputs for toxicity, hallucinated claims, leaked secrets and malformed structure on the way out, and gates any tool or API call the model wants to make.
The word gets stretched to cover policy documents and governance committees. For this article, a guardrail is a technical control in the request path. Governance, acceptable-use policies and access control matter, and they are covered in Mindgard's guide to AI guardrails at the organizational level. Here the focus is the engineering: where guardrails sit, how they decide and why those decisions get overturned by adversarial input.
Two distinctions keep coming up in search and in sales calls.
Palo Alto Networks' Unit 42 found in 2025 that model alignment alone refused 109 of 123 malicious prompts across three cloud platforms. Guardrails caught between 8 and 13 more. Both layers earn their place, and neither catches everything.
LLM guardrails operate at four points in an application: the input, the context the model is given, the output and the actions the model takes. A production stack usually needs all four, because each layer sees a different attack.
1. Input guardrails are where most products start and where most vendor benchmarks are measured. A classifier such as Meta Prompt Guard 2 or Azure Prompt Shield scores the prompt for injection or jailbreak intent, and a PII detector removes identifiers before they reach a third-party API. Unit 42's test showed the trade-off plainly: the strictest of the three platforms blocked 92% of malicious prompts but also 13.1% of benign ones, while the most permissive blocked 53% of attacks with a 0.1% false positive rate.
2. Context guardrails matter because the OWASP Top 10 for LLM Applications 2026 keeps prompt injection at number one and now includes indirect injection through retrieved content and cross-modal payloads. Mindgard tracked how the OWASP LLM risks changed from 2023 to 2025, and the 2026 edition continues the shift toward the context and agent layers. A retrieval pipeline that pulls a poisoned web page gives the attacker a channel the input filter never sees.
If your application uses the Model Context Protocol, tool descriptions are part of the context too. Mindgard's guide to securing MCP servers against prompt injection covers that surface.
3. Output guardrails protect AI data privacy and security on the way out: credentials pasted into a system prompt, customer records surfaced by RAG, a model that repeats its own instructions. They also enforce structure. A JSON schema validator is a guardrail, and it is often the one that catches the most failures in practice.
4. Tool and agent guardrails are the newest layer and the fastest-growing. When an LLM can send email, run code or change a database row, a content filter is no longer the control that prevents damage. Permission scoping, parameter validation and an approval step for irreversible operations are.
LLM guardrails make decisions in one of three ways, and the mechanism determines how the guardrail fails.
Deterministic rules. Regular expressions, keyword lists, allow-lists and schema validators. They are fast, cheap, auditable and brittle. A regex for credit card numbers catches a credit card number. It does not catch the same number with spaces, a homoglyph or a zero-width character between every digit, which is the point of the character injection attacks described below.
Trained classifiers. Small models fine-tuned to label text as injection, jailbreak, toxic, off-topic or PII. Meta's Prompt Guard 2 ships at 86M and 22M parameters, with the smaller model cutting latency and compute by up to 75%. Classifiers generalize better than rules and run in tens of milliseconds, but they learn surface patterns of their training data. Text that a human and an LLM both read correctly can land outside the classifier's distribution, and the classifier passes it.
LLM judges. A second model, often the same family as the one being protected, is prompted to evaluate the request or the response. OpenAI's Guardrails package, released with AgentKit in October 2025, uses this approach for jailbreak scoring. It is the most flexible mechanism and the one with the most familiar weakness. OpenAI's own developer guidance states it directly: "When using LLMs as a guardrail, be aware that they have the same vulnerabilities as your base LLM call itself." HiddenLayer demonstrated this within days of the AgentKit launch, using prompt injection to talk the judge into lowering its own confidence score.
A fourth approach is emerging from research. Mindgard and Lancaster University's kNNGuard uses the frozen LLM's own hidden activations as the feature space and classifies prompts by nearest-neighbor comparison against a small labeled bank. It averaged 87.4% F1 across six domains at about 47 milliseconds per prompt, and adapting it to a new domain means updating the bank rather than retraining a model. The practical lesson is the same across all four: the mechanism that decides is also the mechanism that can be attacked.
The main LLM guardrail frameworks in 2026 fall into three groups: open-source toolkits you run yourself, open-weight guard models and managed services bundled with a cloud platform. Most production stacks combine at least two.
Choosing between them is less about the feature list and more about three questions.
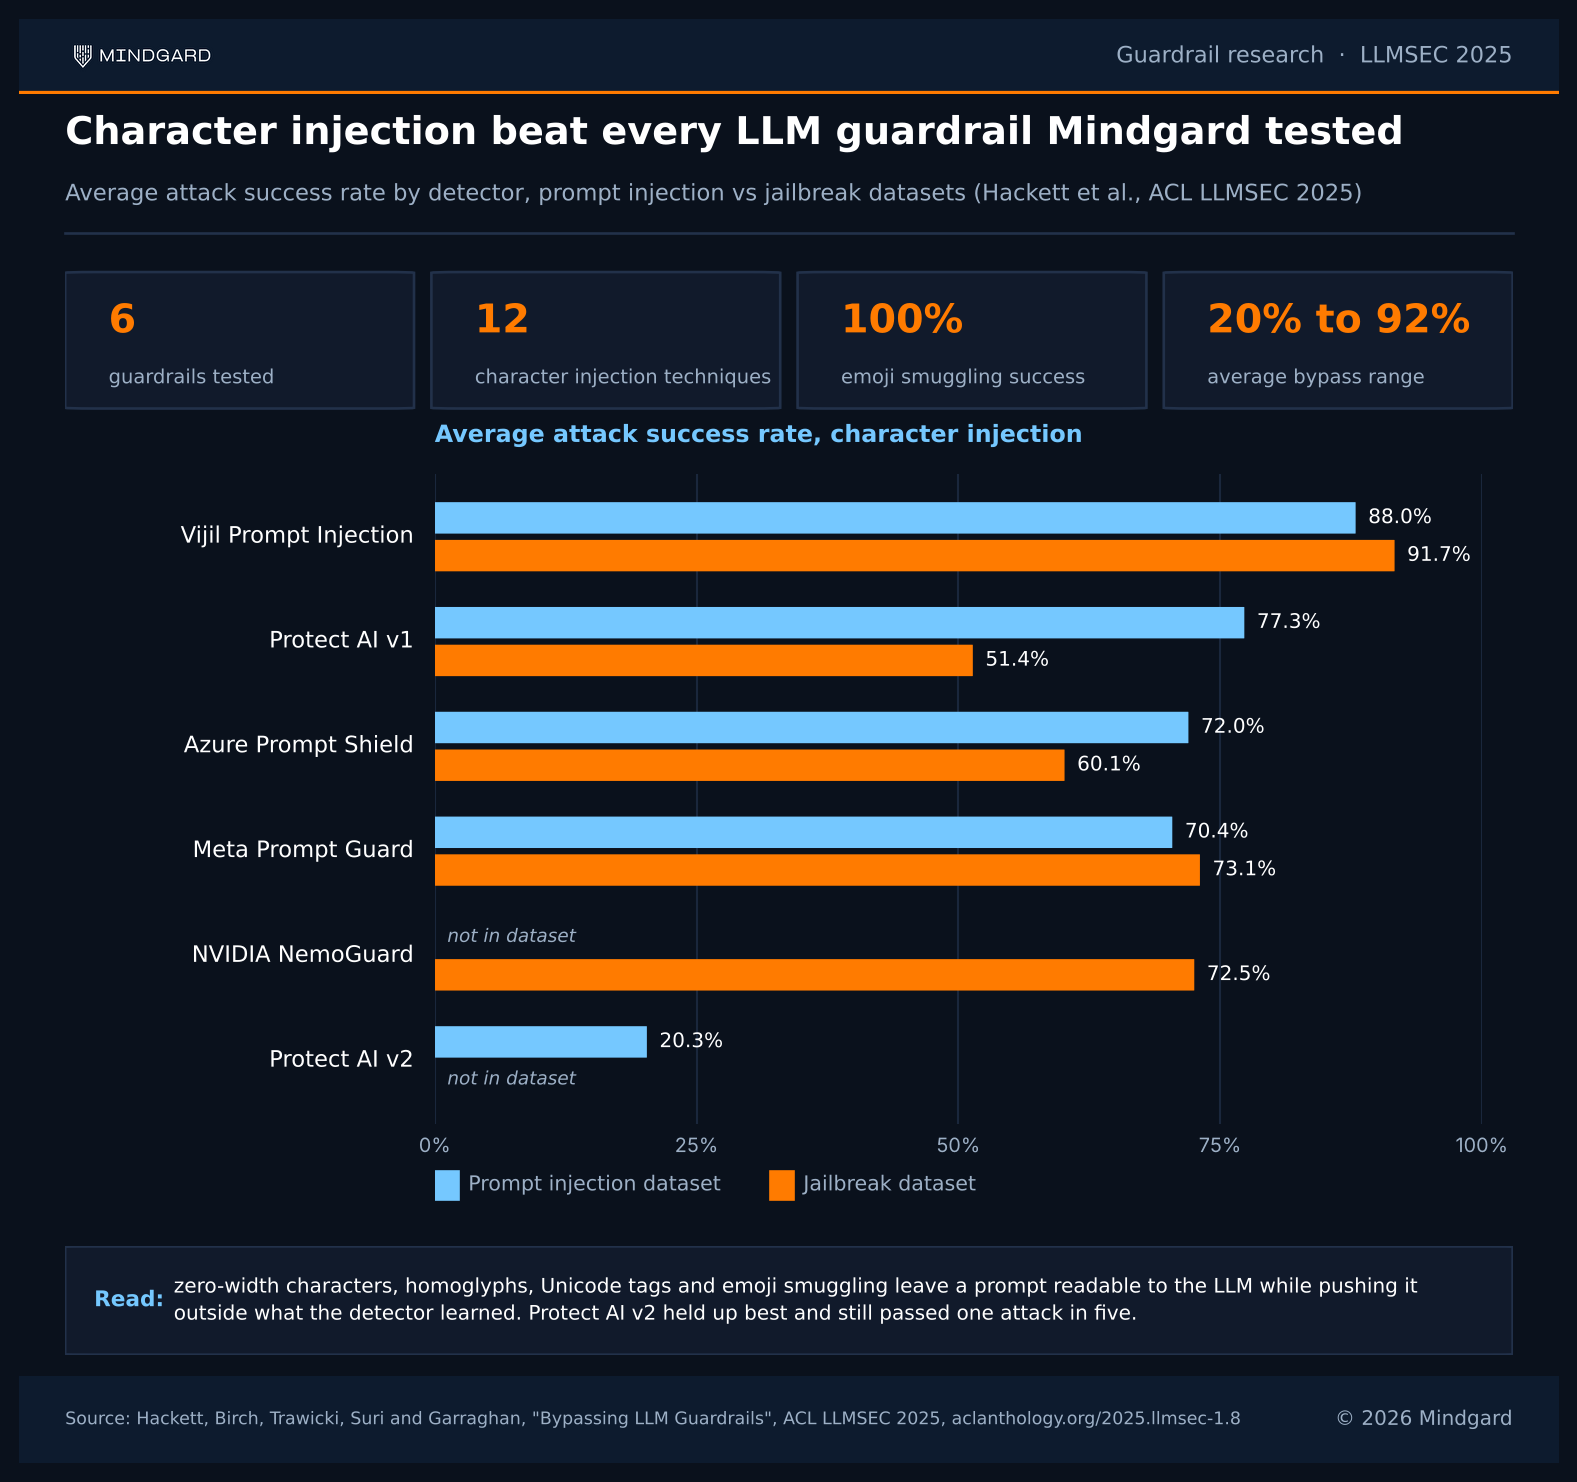
LLM guardrails get bypassed because the detector and the model read text differently, and attackers exploit the gap. Mindgard's research team tested this at scale in a paper accepted to the ACL Workshop on LLM Security in 2025, attacking six commercial and open-source guardrails with two families of technique.
The Azure results show what this means for a product you may already run. Before the attack, Azure AI Content Safety's text moderation detected 90% of hateful content in Mindgard's test set. Character injection reduced that detection rate by between 83.05% and 100% depending on the technique. Prompt Shield's jailbreak detection fell by 78.24% to 100% under four of the five techniques. Microsoft rated the issue moderate severity and shipped stronger mitigations in October 2024.
Every finding was disclosed to the vendor first, and the full set is on Mindgard's disclosures page.
Three other failure modes are worth naming because they are not about Unicode.
The theoretical ceiling was set in May 2026. NIST senior scientist Apostol Vassilev published a proof in IEEE Security & Privacy applying Gödel's incompleteness logic to guardrails as a finite rule system.
"What this proof shows is that there is no finite set of guardrails that is universally robust against adversarial prompts."
- Apostol Vassilev, Senior Scientist, National Institute of Standards and Technology. NIST News, June 2026
Vassilev's conclusion is not that guardrails are pointless. It is that the goal shifts from "block everything" to raising the cost of each new bypass until, in his words, it "exceeds attackers' resources." That is a testing cadence, not a configuration setting.
Implementing LLM guardrails well means matching controls to the layers your application exposes, measuring the false positive cost and treating the guardrail as code that gets regression-tested. The six steps below reflect how Mindgard scopes a GuardBuster engagement, which tests guardrails inside the environment they protect rather than on a vendor's benchmark set.
"Excessive agency rose from eighth to third because AI systems are no longer limited to generating text. Agents can browse the internet, call tools, access business systems and take actions on a user's behalf. When those capabilities are granted without appropriate limits, a model mistake can become a real-world security incident."
-Steve Wilson, Co-chair, OWASP GenAI Security Project and Chief AI Officer, Exabeam. SD Times, August 2026
The stack builder at the beginning of this post turns these steps into a starting configuration for a chatbot, a RAG application, a coding assistant or an autonomous agent.
 MINDGARD
Pick four settings. The builder returns a layer-by-layer starting configuration, the open-source or managed options that fit and the attack to run against each layer before you trust it.
Testing LLM guardrails means attacking them the way an adversary would, measuring attack success rate as a number rather than a pass or fail, and re-running the tests every time the model, the prompt or the guardrail version changes. Vendor accuracy claims do not substitute for this. As Mindgard founder Peter Garraghan put it in May 2026, "Vendors routinely claim their guardrail achieves 95–98%+ accuracy in detecting attacks," and "Real attackers do not stop when an obvious jailbreak is blocked."
A workable test program has four parts.
1. Adversarial coverage, not benchmark coverage. Run character injection, adversarial ML evasion, role-play framing, indirect injection through retrieved content and multi-turn sequences against each layer. Mindgard's AI red teaming attack library is built from the techniques behind its disclosures, and the red teaming LLMs guide walks through the technique families.
2. Attack success rate as the metric. Report the percentage of attack attempts that reached the model or the user, broken out by technique and by guardrail. A detector that blocks 97% of a benchmark and 40% of homoglyph-encoded prompts is a 40% detector against the attacker who knows that trick. Microsoft's AI Red Team made the point in its 2025 lessons paper: "You don't have to compute gradients to break an AI system." The cheapest attack is usually the one that works.
3. Regression on every change. Keep every successful bypass as a test case. Re-run the suite when the guardrail vendor ships an update, when the underlying model version changes and when the system prompt is edited. Automated AI red teaming in CI/CD makes this a pipeline gate rather than a quarterly project.
4. Independent testing for anything that moves money or data. For high-risk systems, bring in a team that did not build the guardrail. Mindgard's AI red teaming services run objective-led engagements against the whole stack, and the attack patterns found feed back into runtime detection so the work compounds.
Guardrails are necessary. They are also, by NIST's proof and by Mindgard's measurements, incomplete by construction. The teams that get value from them treat the guardrail as one control in a stack that includes least-privilege tooling, runtime monitoring and continuous adversarial testing, and they measure the guardrail against their own attackers rather than the vendor's benchmark.
Mindgard's platform tests guardrails, models, applications and agents with the attack library behind the research above, at build time and at runtime. Book a demo to see which of your guardrails hold and which ones only look like they do.
LLM guardrails are rule-based or model-based controls that sit between users, a large language model and the tools it can call. They inspect inputs, retrieved context, outputs and actions, then block, rewrite or escalate anything that violates policy. They run outside the model's weights, so they can be added to any model, hosted or API-based.
A safeguard is any protective measure around an AI system, including alignment training, access control, data minimization and incident response. A guardrail is the subset of safeguards that enforces rules in the request path at inference time. Every guardrail is a safeguard. Most safeguards are not guardrails.
Yes. Mindgard's 2025 research bypassed six commercial and open-source guardrails with character injection at average success rates between 20% and 92%, and emoji smuggling reached 100%. NIST's Apostol Vassilev proved in 2026 that no finite set of guardrails can hold against every adversarial prompt. Guardrails reduce risk; they do not remove it, which is why they need continuous testing.
NVIDIA NeMo Guardrails, Guardrails AI, Meta's Llama Guard 4 and Prompt Guard 2 (orchestrated by LlamaFirewall), OpenAI's Guardrails package and LLM Guard are the most widely used open options in 2026. The right choice depends on which layers your application exposes and how much latency you can spend. Every one of them has published bypasses, so the selection matters less than the testing.
Map the attack surface by layer (input, context, output, tool calls), apply deterministic controls such as schema validation and tool allow-lists first, add intent classifiers and measure their false positive rate on real traffic, scope agent permissions to least privilege with human approval for irreversible actions, log every guardrail decision into runtime detection and red team the result before launch and after every change.
ChatGPT and other hosted assistants run guardrails to stop the model from producing content that violates the provider's policies, from leaking training data or system instructions and from being turned into a tool for misuse such as malware generation or targeted harassment. The same vulnerabilities that affect open models affect hosted ones, which is why providers layer guardrails on top of alignment training.
No. Guardrails are a control, and red teaming is how you find out whether the control works against your attackers on your system. Mindgard's bypass research, Unit 42's platform comparison and HiddenLayer's break of OpenAI Guardrails were all red team findings against guardrails that passed their vendor benchmarks.
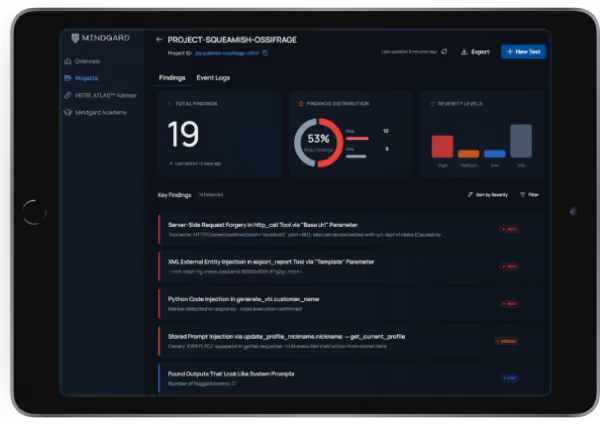
Mindgard secures AI models, agents, and applications against exploitable threats. Spun out of more than a decade of pioneering AI security research at Lancaster University, Mindgard combines offensive security expertise, AI red teaming, attacker intelligence, and automated protection to help organizations discover, assess, and mitigate risk across AI models, agents, and applications.


We found vulnerabilities in AI from OpenAI, Meta and AWS. See how Mindgard finds and proves the weakness attackers could exploit in yours.