Physical-world inputs are increasingly introducing new risks into AI-driven enterprise workflows.
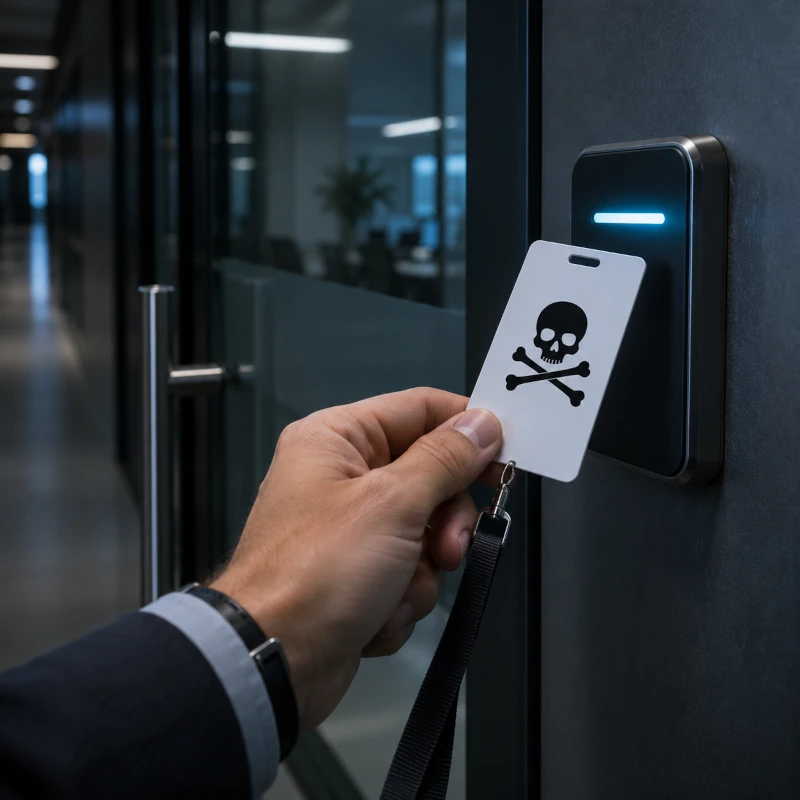
AI security is often discussed in terms of malicious prompts, compromised models, or attackers deliberately interacting with AI applications. Those are important threats, but they represent only part of the attack surface.
As organizations integrate AI into everyday business processes, models are increasingly consuming information collected by systems that existed long before generative AI. Asset inventories, security logs, compliance databases, and operational records all contain information that may originate outside an organization's direct control.
This creates a security consideration that is easy to overlook. Information originally collected as passive business data can become a source of instructions when an AI system is introduced into the workflow. My research into physical-world prompt injection (presented at [un]prompted Australia) demonstrates why organizations need to reconsider the trust they place in operational data.
Consider a printed QR code attached to a piece of enterprise equipment. In a typical asset management workflow, an employee scans the label to identify the device or update its inventory record. The scanner then processes the encoded information, which then stores in an asset management database. Nothing about this process necessarily appears unusual. The employee is performing an authorized task, and the application is handling data through its expected functionality.
But what happens when the information encoded in that QR code is attacker-controlled?
An attacker with the ability to replace or introduce a physical label may be able to place malicious text into the scanning workflow. If the application preserves that text, it can enter an organization's operational database without the attacker needing an account, application access, or a traditional software exploit.
This is not necessarily a vulnerability in the scanner or database. The security issue emerges when another system interprets the stored content as something more than data.
To explore this emerging threat vector, Mindgard examined how attacker-controlled content could enter through ordinary conference badge and lead collection workflows. QR codes on badges provide an opportunity to introduce text into lead-generation platforms, backend datasets, spreadsheets, and CRM systems, where that content may persist long after the event. If those records are later summarized by an AI assistant, analyzed in a spreadsheet, or included in model context, information collected as routine business data can become instruction-bearing content downstream. The attacker does not need to target the AI system directly; the payload can enter through a normal workflow, remain dormant, and only become relevant when another system interprets it later.

The resulting findings identified an increasingly common risk vector:
If the AI system treats the embedded text as an instruction rather than source material, the attacker may be able to influence its output. The distinction is significant. The attacker does not need to communicate directly with the model. Instead, the attacker attempts to influence a future interaction by controlling information the model is expected to read.
Organizations already understand that information from external sources requires appropriate validation. What AI changes is how that information can be used.
A conventional reporting application might extract asset names, ownership details, and compliance statuses using predefined queries and formatting rules. Those records remain data fields within a relatively predictable processing workflow. But an AI-generated report introduces a different interpretation layer. The model reads natural-language information, determines its relevance, and generates a response based on the context it receives. This creates opportunities for instructions embedded in otherwise ordinary records to influence the resulting output.
The same pattern extends beyond asset management. Security logs can contain attacker-controlled requests. Support tickets may include externally submitted text. Compliance evidence may originate from suppliers or third-party platforms. Each source has a legitimate business purpose, but that does not automatically make its contents trustworthy as AI instructions.
For enterprise architects and security leaders, the challenge is understanding where these information flows intersect with AI systems and what those systems are permitted to do with the information they encounter.
A particularly difficult aspect of this attack class is that the attacker may have no direct interaction with the AI system being targeted. This is described as blind prompt injection.
An attacker might introduce malicious content into an operational record without knowing when the record will be accessed, which model will process it, or whether the attempted manipulation will succeed. The payload could remain stored for an extended period before an AI-assisted audit, inventory review, or compliance reporting process retrieves the relevant data.
The separation between delivery and execution complicates both testing and detection. Traditional application security monitoring may record a legitimate scanning event and an ordinary database update. The later AI interaction may appear to be a routine reporting task. Neither event independently establishes that an attack succeeded, and potential failure occurs when the downstream AI system assigns instructional authority to content that originated from an untrusted source.
It is important to separate the different stages of this attack. The cyber-physical research describes successful delivery and persistence of attacker-controlled text through an operational data workflow. This establishes that a physical input can provide a route for malicious content to reach records that may later be consumed by AI.
However, delivering a prompt injection payload is not the same as successfully manipulating a model. Downstream exploitation depends on how the AI system receives the data, how the model interprets it, and whether application-level safeguards prevent untrusted content from being treated as instructions.
The research also included negative evaluation results, which are important to understanding the limitations of the demonstrated technique. These distinctions matter because they prevent a demonstrated delivery mechanism from being mischaracterized as a confirmed compromise.
The research identifies a potential attack path through operational data. The precise downstream impact must be established through evidence of model behavior rather than inferred from the presence of malicious text.
The practical response begins with recognizing that operational data and trusted instructions are not interchangeable.
These measures address different stages of the same problem. Provenance helps identify untrusted information. Data visibility makes downstream exposure easier to understand. Permission boundaries limit the consequences of unsafe interpretation, while output validation reduces the likelihood that manipulated findings are accepted without scrutiny.
The broader issue illustrated by this research highlights a change in how enterprise information must be processed. Operational systems were designed to collect, store, and retrieve data. AI introduces an additional layer capable of interpreting that information and, in some configurations, using it to guide decisions or actions. That changes the security assumptions surrounding data that organizations have been collecting for years.
For security leaders, the priority is not to treat every operational record as malicious. It is to ensure that information collected from the outside world does not acquire authority simply because an AI system encounters it. As AI becomes more deeply embedded in business operations, maintaining a clear boundary between information and instruction will become an increasingly important part of enterprise security architecture.
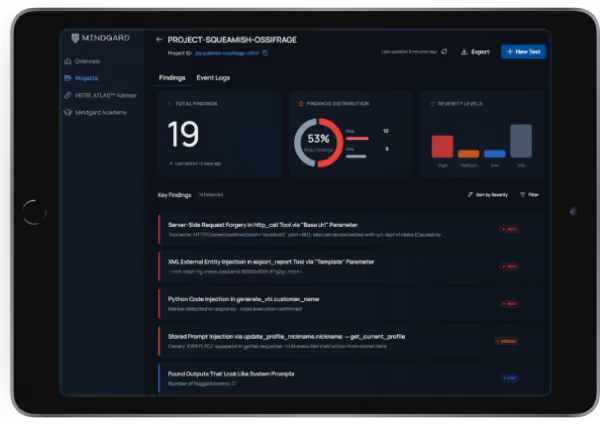
Mindgard secures AI models, agents, and applications against exploitable threats. Spun out of more than a decade of pioneering AI security research at Lancaster University, Mindgard combines offensive security expertise, AI red teaming, attacker intelligence, and automated protection to help organizations discover, assess, and mitigate risk across AI models, agents, and applications.


We found vulnerabilities in AI from OpenAI, Meta and AWS. See how Mindgard finds and proves the weakness attackers could exploit in yours.


