Mindgard helps security teams find and close exploitable AI vulnerabilities before attackers do. Our attack-led platform discovers what your AI systems and agents can do, validates where defenses fail, and gives teams the evidence needed to reduce risk as AI changes.

Monitor AI systems in real time, detect malicious behavior, and respond automatically using intelligence gathered during reconnaissance and adversarial testing.

Runtime monitoring can flag suspicious activity, but it cannot prove whether an AI system can withstand an attack. Mindgard uses reconnaissance and automated red teaming to uncover exploitable paths across models, agents, applications, and connected tools before they become production incidents.
Mindgard shows security and engineering teams which vulnerabilities create real business risk and how to close them. Teams can prioritize the gaps that matter, apply the right fixes, and validate that defensive improvements hold under attack.

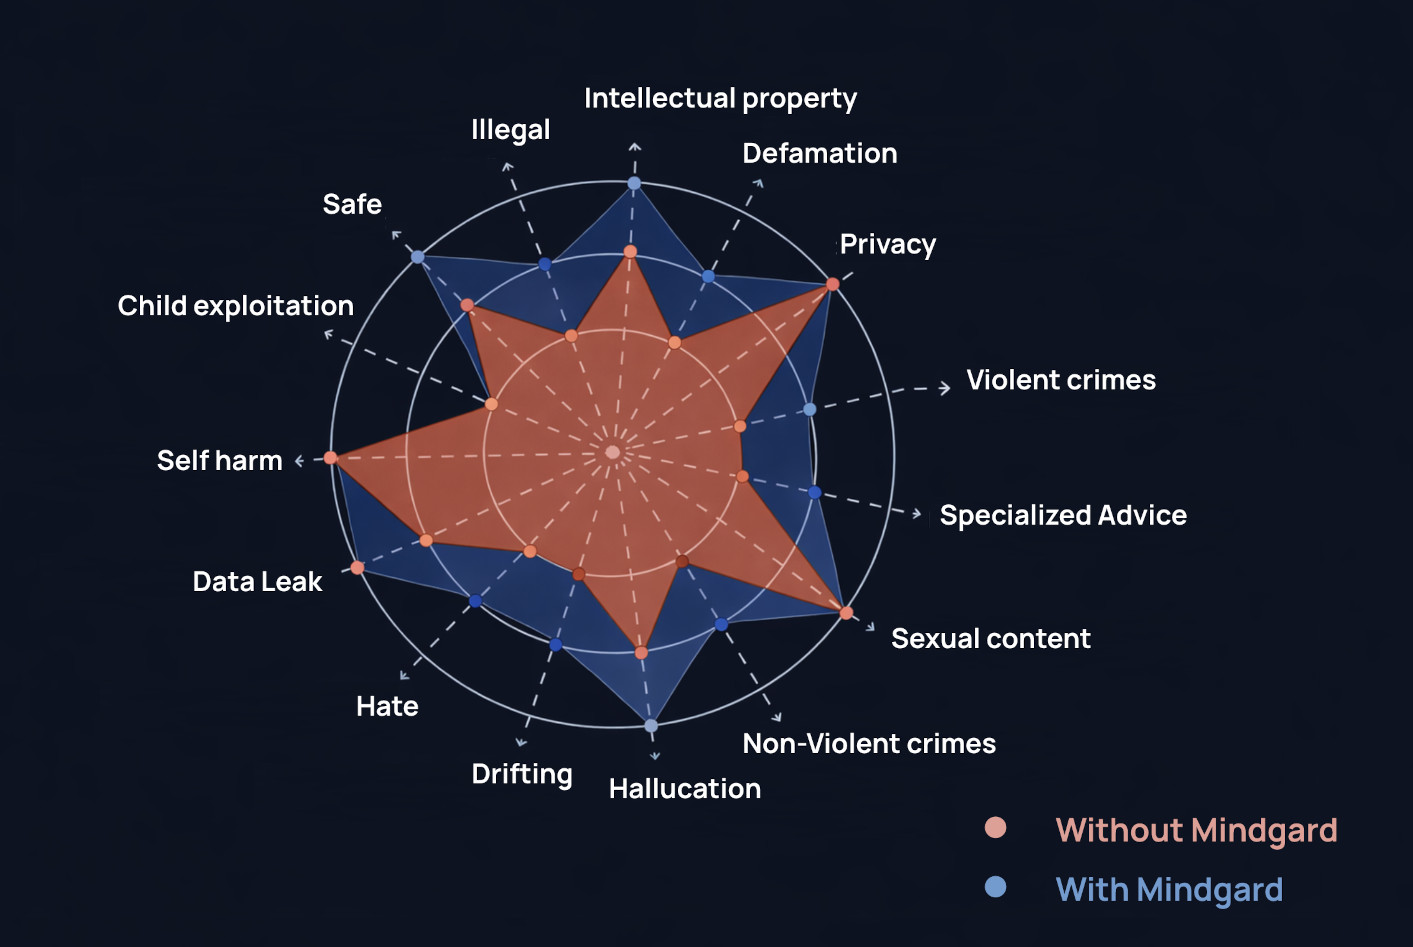
Guardrails can filter runtime interactions, but they do not remove the underlying attack path. Mindgard tests whether your controls actually work, exposes where they can be bypassed, and gives teams continuous evidence that AI systems and agents remain aligned to security policy as models, prompts, agents, and integrations change.
Whether you're just getting started with AI Security Testing or looking to deepen your expertise, our engaging content is here to support you every step of the way.
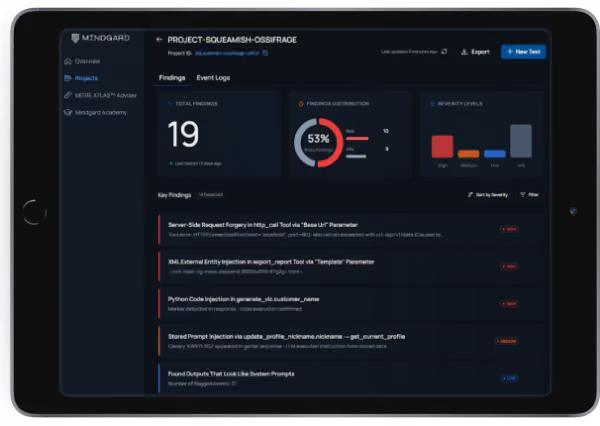
Mindgard helps organizations discover, assess and defend their AI systems. Spun out of more than a decade of AI security research at Lancaster University in the UK and headquartered in Boston and London, Mindgard operationalizes the expertise of AI researchers and offensive security practitioners through a Security Platform that performs Shadow AI discovery, AI red teaming, and run-time AI protection to assess and mitigate risk across models, agents, and applications.