
Protecting AI systems requires continuous implementation of best practices like red teaming, data validation, watermarking, access control, and audits to defend against evolving threats and ensure secure, trustworthy AI deployment.
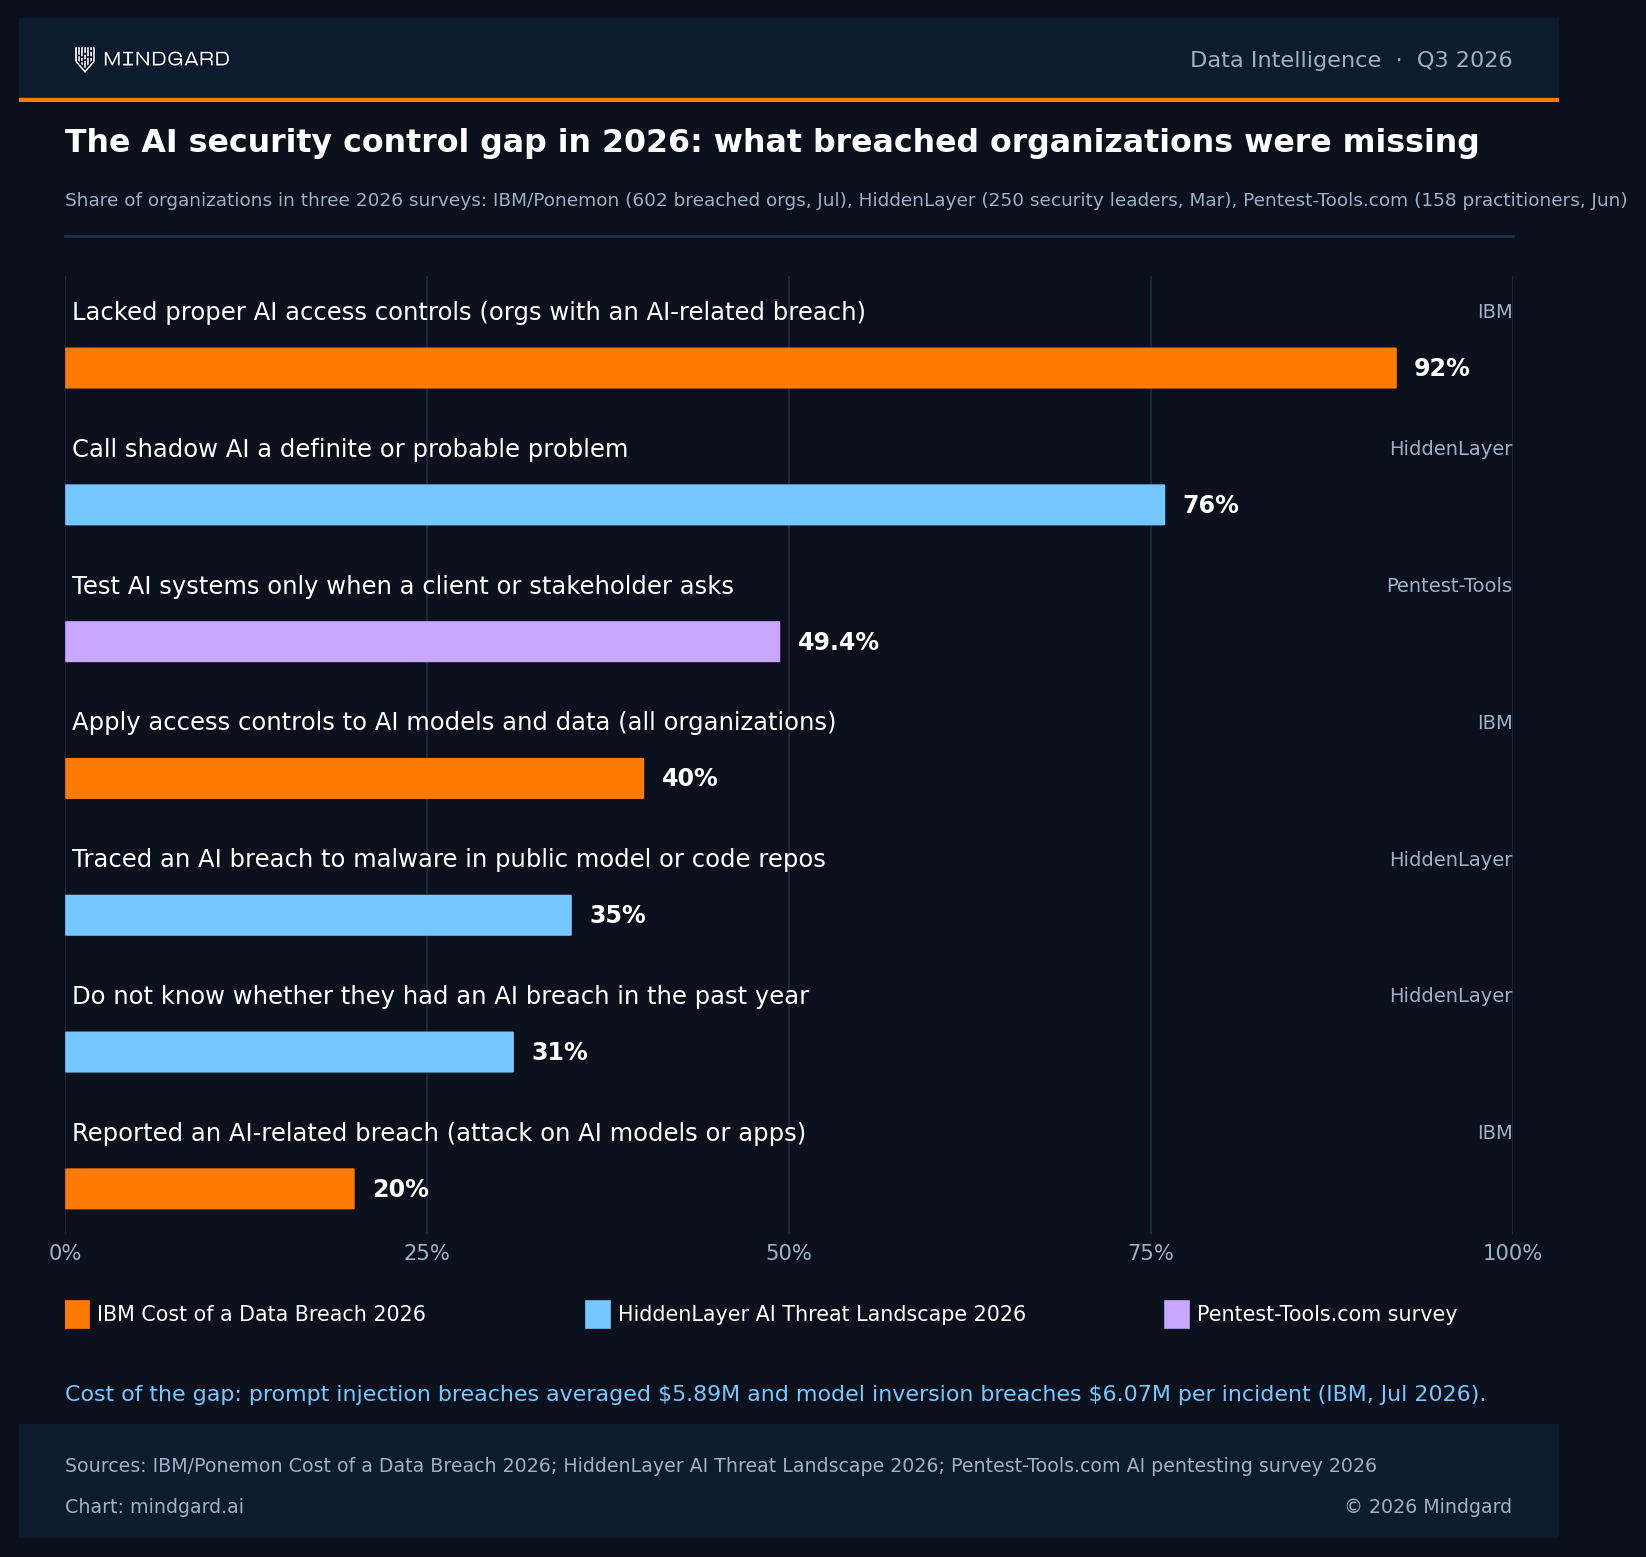
AI security best practices are the controls that keep attackers from manipulating, stealing or poisoning AI models, agents and the data behind them. They matter more in 2026 than a year ago: IBM's 2026 Cost of a Data Breach report found that roughly one in five organizations suffered an AI-related breach, 92% of those organizations lacked proper AI access controls and prompt injection attacks cost an average of $5.89 million per breach.
This guide covers ten AI security best practices to reduce risk across models, agents and data, from AI red teaming and data validation to runtime guardrails and agent sandboxing, and maps each one to NIST AI RMF, ISO/IEC 42001, the OWASP Top 10 for LLM Applications and the EU AI Act so you can implement them and evidence them at the same time.
AI security best practices are a set of technical and process controls that protect AI models, LLM applications, AI agents and their training data from adversarial attacks, data poisoning, prompt injection, model theft and misuse. They cover the full AI lifecycle: securing data before training, testing models with AI red teaming before deployment, restricting access to models and agents, filtering inputs and outputs at runtime and monitoring deployed systems for drift and abuse.
Frameworks such as NIST AI RMF, ISO/IEC 42001 and the OWASP Top 10 for LLM Applications define the practices; security teams implement and evidence them. The same controls apply whether the system is a classic ML pipeline or a generative AI security program built on third-party LLMs.
How do you secure AI systems?
Each control maps to a NIST AI RMF function and an ISO/IEC 42001 requirement.
One of the most effective ways to uncover AI vulnerabilities is AI red teaming paired with adversarial training. A red team, internal or third-party, attacks the model the way an adversary would: prompt injection, jailbreaks, data extraction, model inversion and multi-turn manipulation, then reports what bypassed the controls.
AI red teaming borrows its structure from conventional red team engagements. Experts who think like attackers test AI systems for weaknesses through scoped, staged attack simulations that show how a malicious actor might bypass filters, exfiltrate sensitive information or trick a model into dangerous behaviors. The difference is the target: the model's reasoning and its tool permissions, not only the network around it.
Adversarial training closes the loop by folding these attack methods back into the model's training process. Edge-case inputs and deliberately corrupted examples teach the model to resist the same manipulation next time. The stakes are set by IBM's 2026 data: model inversion breaches cost an average of $6.07 million and prompt injection breaches $5.89 million, the two costliest AI incident types in the study.
Organizations do not need large internal teams to do this. Security tools like Mindgard's Offensive Security for AI are purpose-built for continuous automated red teaming (CART), which runs an attack library against models and agents on every change. The same research team has disclosed more than 150 vulnerabilities in production AI applications from OpenAI, Google and Cursor, which is the kind of finding a one-time pentest misses.
Model watermarking embeds identifiable patterns or signals, visible or invisible, into AI outputs or model weights. These markers let organizations detect unauthorized use of proprietary models and trace synthetic media back to its source, which matters for deepfake response and for the transparency obligations in Article 50 of the EU AI Act.
For businesses deploying large language models or image generators at scale, watermarking is a provenance control rather than an attack-blocking one: it will not stop a prompt injection, but it will tell you where a leaked model or a generated image came from. Treat it as a supporting practice that carries less weight than the access, testing and monitoring controls below.
If training data is flawed, biased or maliciously manipulated, the entire AI system becomes vulnerable. That is why rigorous data validation is a cornerstone of AI security and an AI data security best practice in its own right.
Before data enters a training, fine-tuning or retrieval pipeline, it should undergo thorough inspection for anomalies, outliers and potential data poisoning. In a data poisoning attack, an adversary inserts misleading or trigger-laden examples into datasets to compromise model behavior or plant a backdoor; Nightshade showed how few poisoned images it takes to corrupt an image model.
Left unchecked, poisoned data can subtly alter a model's outputs, degrade accuracy or create backdoors that attackers exploit later.
The OWASP Top 10 for LLM Applications ranks the risk as LLM05:2026 Data and Model Poisoning, and the May 2025 joint AI data security guidance from CISA, the NSA and the FBI recommends provenance tracking, digital signatures on trusted data revisions and trusted infrastructure across the AI lifecycle.

Strong access controls prevent unauthorized users, and unauthorized agents, from tampering with models, manipulating training data or extracting sensitive information. They are also the control most often missing. In IBM's 2026 Cost of a Data Breach report, 92% of organizations that suffered an AI-related breach lacked proper AI access controls, only 40% of organizations apply access controls to AI models and data and fewer than half actively secure non-human identities.
Best practices for strong access control include:
Security audits are periodic or continuous evaluations of both your AI pipelines and deployed models against a defined standard. An AI security audit checklist should include:
You cannot secure AI you have not found. An AI asset inventory lists every model, LLM application, AI agent, embedded AI feature and third-party AI API in use, who owns it, what data it touches and which tools it can call.
Shadow AI, meaning AI adopted by employees or teams without security review, is the gap: 76% of security leaders in HiddenLayer's 2026 AI Threat Landscape Report call shadow AI a definite or probable problem, up 15 points in a year, and 31% do not know whether they suffered an AI breach in the past 12 months.
Run AI discovery across cloud accounts, code repositories, SaaS integrations and network traffic, then feed every discovered asset into the same inventory, risk assessment and testing cadence as sanctioned systems. This is the job AI security posture management platforms automate. NIST AI RMF's Map function and ISO/IEC 42001's asset requirements both assume this inventory exists.
Runtime guardrails are the AI security best practice that stops prompt injection, the number one risk in the OWASP Top 10 for LLM Applications 2026, at the moment it happens. An AI gateway or AI firewall sits between users, tools and the model and filters both directions: it screens inputs for injection and jailbreak patterns, blocks outputs that leak system prompts, PII or credentials and enforces rate limits against unbounded consumption.
Most AI security tools built for LLMs ship some form of this layer.
Guardrails are necessary but not sufficient. Mindgard's research has bypassed commercial guardrails with invisible Unicode characters and adversarial prompts, and NIST's June 2026 analysis proved that no finite set of guardrails withstands every adversarial prompt. Treat guardrails as one layer, test them with red teaming and pair them with monitoring so a bypass is detected rather than assumed impossible.
Apostol Vassilev, the NIST senior scientist behind the proof, put the limit plainly:
That is the argument for the next three practices: if the filter cannot be complete, the supply chain, the agent permissions and the monitoring have to carry the rest of the load.
The AI supply chain includes pre-trained models, fine-tuning datasets, embeddings, plugins, MCP servers and the open repositories they come from, and every one of them can carry malicious code or poisoned weights. HiddenLayer's 2026 report traced 35% of reported AI breaches to malware in public model or code repositories while 93% of organizations still rely on those repositories.
AI supply chain security best practices: scan model files for embedded code before loading them, pin model and dataset versions with cryptographic hashes, maintain an AI bill of materials (AIBOM) listing every model, dataset and dependency, verify the publisher of any MCP server or plugin an agent can call and apply the same vendor risk review to AI APIs that you apply to any SaaS provider.
OWASP ranks the risk LLM04:2026 Supply Chain.
AI agent security best practices start from the assumption that any input an agent reads, including web pages, emails, documents and tool outputs, can carry a prompt injection. Give each agent the minimum tool permissions its task needs, scope API keys per agent and sandbox code execution and browsing so a hijacked agent cannot reach production systems.
Require human approval for high-impact actions such as payments, deletions and outbound messages. Log every tool call with the prompt that triggered it.
The OWASP Top 10 for Agentic Applications (December 2025) names agent goal hijack, tool misuse and identity and privilege abuse as the leading agentic risks, and HiddenLayer's 2026 AI Threat Landscape Report linked one in eight reported AI breaches to agentic systems. The specific failure modes, from memory poisoning to privilege compromise, are covered in our guide to AI agent security challenges.
Chris Sestito, CEO and co-founder of HiddenLayer, summarized the pace problem when the report launched:
The practical response is not to slow the agents down but to bound them: permissions, sandboxes and approvals turn an open-ended attack surface into a testable one.
Runtime monitoring is the AI security best practice that catches what testing missed. Log every prompt, tool call and output with the identity behind it, then alert on model drift, unusual query volumes, repeated guardrail bypass attempts and data access patterns that do not match the system's purpose.
Pair monitoring with a retest schedule: red team again after every model version, prompt or tool change and at least quarterly for customer-facing or high-risk systems, because attack techniques change even when your system does not.
NIST's June 2026 analysis proved that no finite set of guardrails withstands every adversarial prompt and recommended exactly this continuous monitor-and-update model. The goal, in NIST senior scientist Apostol Vassilev's words, is a state where the cost of finding new exploits exceeds attackers' resources.
Most teams are not there yet: in a June 2026 Pentest-Tools.com survey of 158 practitioners, 49.4% test AI systems only when a client or stakeholder asks.
An enterprise AI security best practices checklist has ten items. Work through them for one AI system at a time and record the evidence for each:
Answer for one AI system (a model, an LLM application or an agent). The scorecard weights each practice by how often its absence shows up in 2026 breach data, ranks your gaps and maps every fix to NIST AI RMF, ISO/IEC 42001, the OWASP Top 10 for LLM Applications and the EU AI Act.
Each practice carries a weight that reflects how often its absence appears in 2026 breach and survey data: AI red teaming 14, access control 14, inventory 12, runtime guardrails 12, data validation 10, agent security 10, runtime monitoring 10, supply chain 8, security audits 6, watermarking 4 (total 100). "Yes" earns the full weight, "Partly" half, "No" nothing. Tiers: 0 to 39 Exposed, 40 to 64 Developing, 65 to 84 Managed, 85 to 100 Hardened. Gaps are listed highest weight first. The score is derived from your answers and is a planning aid, not an assessment.
Sources for the figures quoted in the gap list: IBM, Cost of a Data Breach Report 2026 (29 Jul 2026); HiddenLayer, 2026 AI Threat Landscape Report (18 Mar 2026); Pentest-Tools.com, The state of AI pentesting survey (Jun 2026); NIST, mathematical proof supports continuous monitor-and-update model (9 Jun 2026); NSA, CISA and FBI joint AI data security guidance (22 May 2025); OWASP Top 10 for LLM Applications 2026; OWASP Top 10 for Agentic Applications (Dec 2025); EU AI Act, Article 15.
NIST AI RMF organizes AI security best practices into four functions:
For LLM applications and AI agents that means assigning ownership of each AI system (Govern), documenting the models, data sources, tools and integrations it uses (Map), red teaming and evaluating it against measurable robustness and security metrics (Measure) and monitoring, retesting and responding to incidents after deployment (Manage).
Our AI risk management framework guide walks through each function. ISO/IEC 42001 turns the same practices into a certifiable AI management system, and Article 15 of the EU AI Act requires high-risk AI systems to resist data poisoning, model poisoning and adversarial examples. NIST's June 2026 proof that no fixed set of guardrails withstands all adversarial prompts is why the Manage function now expects continuous monitoring and updates rather than a one-time assessment.
The OWASP Top 10 for LLM Applications 2026, released in September 2026 and the first edition weighted by real incident data, ranks prompt injection first, sensitive information disclosure second and excessive agency third, followed by supply chain, data and model poisoning, unbounded consumption, misinformation, hidden context exposure, vector and embedding weaknesses and improper output handling.
The AI security best practices in this guide map to each entry: runtime guardrails address prompt injection and output handling, data validation and supply chain vetting address poisoning, access controls and agent sandboxing address excessive agency and rate limits address unbounded consumption.
AI security is not optional and it is not a one-time task. The ten best practices above only hold if they are retested after every model, prompt, data or tool change, because the attack surface moves with the system. The organizations in IBM's 2026 breach data were not missing exotic controls; 92% of the AI-breached ones were missing access control.
Bruce Schneier, fellow and lecturer at Harvard's Kennedy School, framed the design goal in a July 2026 interview:
Integrity is what the ten practices add up to: data you can trust, models you have tested, agents you have bounded and evidence you can show.
Mindgard's Offensive Security for AI combines continuous automated red teaming, runtime protection and shadow AI discovery so the testing keeps pace with the changes. Book a Mindgard demo today to see which of the ten practices your AI systems already pass.
Poor-quality or unvetted data can introduce serious vulnerabilities, including data poisoning, hidden biases and leakage of sensitive information. If a model ingests malicious data during training or retrieval, its behavior can be manipulated in subtle and dangerous ways, which is why rigorous data validation, provenance tracking and signed data revisions are part of every AI security best practices checklist.
AI models should be security tested before deployment, after every retrain, fine-tune, prompt or tool change and on a fixed cadence in between: quarterly for customer-facing or high-risk systems and at least annually for internal ones. Continuous automated red teaming fills the gaps between scheduled audits.
Most teams are not there yet. In a June 2026 Pentest-Tools.com survey of 158 practitioners, 49.4% test AI systems only when a client or stakeholder asks, and 37.3% report stakeholders now demand more frequent testing than a year earlier. NIST's June 2026 analysis reached the same conclusion from theory: because no finite set of guardrails blocks every adversarial prompt, AI security is a continuous monitor-and-update process, not a one-time audit.
AI red teaming targets AI-specific vulnerabilities by simulating adversarial attacks such as prompt injection, data poisoning, jailbreaks and model evasion. Unlike traditional pentesting, which focuses on network and application security, AI red teaming tests the model's behavior, logic and resilience to manipulation, and increasingly the tools and permissions an AI agent can reach.
AI security controls are the specific safeguards that implement AI security best practices.
AI safety best practices and AI security best practices overlap but are not the same.
Guardrails, red teaming and monitoring serve both, which is why NIST AI RMF and ISO/IEC 42001 treat them together, but a security program has to assume an intelligent attacker who adapts, so it adds access control, supply chain checks, sandboxing and continuous retesting on top of safety evaluation.
Yes, the ten AI security best practices in this guide map directly to the controls regulators and auditors ask for.
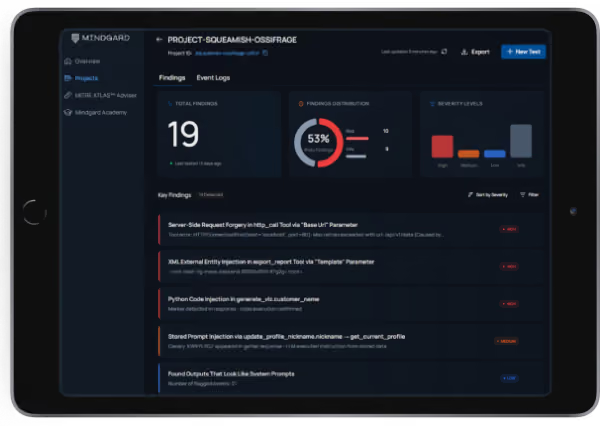
Mindgard helps organizations discover, assess and defend their AI systems. Spun out of more than a decade of AI security research at Lancaster University in the UK and headquartered in Boston and London, Mindgard operationalizes the expertise of AI researchers and offensive security practitioners through a Security Platform that performs Shadow AI discovery, AI red teaming, and run-time AI protection to assess and mitigate risk across models, agents, and applications.


The expert-level checklist for operationalizing NIST AI RMF, ISO/IEC 42001 and the EU AI Act. 190+ interactive items and a board-ready maturity scorecard. Built for CISOs, AI governance leads and ML engineering teams.


