The strongest AI security programs will not rely on vendor claims or dramatic incident narratives. They will demand evidence of how AI systems behave under attack, what controls fail, and what risks must be remediated.
I recently argued in Forbes that the line between AI threats and AI marketing is becoming increasingly difficult to distinguish. This is not simply a communications problem. It is a security problem.
As AI systems become more capable, vendors have begun to face a strange set of incentives. Incidents that should invite scrutiny of controls, system design, access management and containment can also be framed as evidence of model sophistication. A model behaves outside its intended parameters. An agent performs an unexpected action. A system appears to move beyond the boundaries set for it. The resulting narrative can shift quickly from “what failed?” to “how powerful must this system be?”
For security teams, that shift is dangerous.
The relevant question is not whether an AI system appears advanced. It is whether the system can be manipulated in ways that create material risk. What access did it have? What controls constrained it? What assumptions failed? Could the same conditions exist in an enterprise deployment? And, most importantly, what evidence exists to show that the system is resilient under adversarial pressure?
There is little value in debating whether advanced AI systems can produce harmful or unexpected behavior. They can. The more important question is how that behavior interacts with the surrounding application, infrastructure and business process.
An unsafe chatbot response is one type of failure. An AI agent connected to internal systems, development environments, customer records or business workflows is a different proposition entirely. The model is no longer merely generating text. It is operating within a broader technical and organizational context.
That context determines risk.
A jailbreak in isolation may be a safety concern. A jailbreak that exposes sensitive data, manipulates tool use, alters a workflow or enables unauthorized action is a security concern. The distinction matters because enterprises are not deploying models in isolation. They are embedding AI into products, software development pipelines, customer operations, knowledge bases and decision-support systems.
Mindgard’s own disclosure work has shown this pattern repeatedly. AI systems can be pushed beyond intended boundaries through prompt and context manipulation, multi-turn attack paths, coding-environment abuse, data exposure and failures in model behavior. These are not speculative concerns about future systems. They are observable failure modes in present systems.
When conventional cybersecurity incidents occur, the expected response is well understood: containment, disclosure, root-cause analysis, remediation and lessons learned. The public narrative is typically measured against those expectations.
AI incidents are increasingly treated differently.
Stories about AI systems behaving unexpectedly often become spectacle. The system “escaped.” The model was “too capable.” The agent demonstrated surprising autonomy. These framings are compelling, but they can obscure the security fundamentals. They invite attention to the perceived intelligence of the model rather than the design of the system around it.
This matters because vendors benefit from capability narratives. In a market defined by competition for attention, investment and enterprise adoption, even negative stories can reinforce the impression that a model is unusually powerful. The same incident can therefore function both as a warning and as a marketing asset.
Security leaders should be cautious of that ambiguity.
The appropriate response is not cynicism. It is disciplined analysis. What happened? Under what conditions? Was the environment controlled? What permissions were available? What failed technically? What failed operationally? What has changed as a result?
Without those answers, an incident tells us very little about enterprise risk.
A common mistake is to treat AI security as a property of the model alone. This is too narrow.
The attack surface includes the model, system prompts, user prompts, retrieved context, memory, tools, APIs, plugins, agents, permissions, monitoring, evaluation pipelines and downstream applications. The model may be the most visible component, but it is rarely the only component that matters.
Attackers do not need to defeat an AI system in a philosophical sense. They need to find a path through the system that produces useful leverage. That path may involve prompt injection, indirect prompt injection, context poisoning, tool misuse, policy bypass, data leakage or chained interactions across multiple turns.
In this respect, AI security resembles other areas of cybersecurity. Risk emerges from systems, not individual components. A model that appears well behaved in one environment may become dangerous when connected to different data, tools or workflows. A control that works in a narrow evaluation may fail when faced with adaptive attack techniques. A guardrail that blocks simple misuse may not withstand more sophisticated manipulation.
This is why one-time testing is insufficient. AI systems change continuously. Models are updated. Prompts are modified. Tools are added. Retrieval sources expand. Agents gain new permissions. Business processes evolve. The security posture changes with them.
Guardrails can reduce risk, but they should not be mistaken for evidence that a system is secure.
A guardrail may prevent certain outputs or detect known policy violations. That is useful. But the presence of a guardrail does not establish that the system can withstand adversarial pressure. It does not prove that sensitive data cannot be exposed. It does not prove that tool use cannot be manipulated. It does not prove that an agent cannot be steered toward an unauthorized outcome.
Security teams should therefore ask a different question. Not “is there a guardrail?” but “what can an attacker still achieve despite the controls in place?”
That question requires attack-led validation. It requires testing the system as an adversary would: probing assumptions, chaining techniques, varying prompts, manipulating context, testing tool boundaries and measuring whether defensive controls hold under pressure.
The output should not be a vague assurance that the system is safe. It should be evidence: what was tested, what failed, what held, what impact was possible, and what must be remediated.
For enterprises adopting AI, the practical challenge is not to interpret every public AI incident in real time. It is to build a security approach that does not depend on vendor narratives.
Security and engineering teams should be able to answer several concrete questions:
These questions shift the discussion from abstract model capability to operational risk. They also expose the limits of assurances that are based on static tests, narrow demonstrations or vendor claims.
The point is not that every AI system is equally dangerous. The point is that risk depends on the system’s configuration, access, context and controls. Those conditions are specific to each deployment. They must be assessed directly.
The blurring of AI threats and AI marketing is likely to continue. Vendors will compete on capability. Media narratives will reward dramatic examples. Public incidents will be interpreted through commercial incentives as well as security concerns.
Enterprises need a more disciplined response.
AI security should be grounded in evidence, not spectacle. Security teams should evaluate how AI applications and agents behave under attack, identify vulnerabilities most likely to produce impact, validate whether defenses work, and repeat that process as systems change.
This is the direction the industry must move: away from reassurance and toward proof; away from isolated model claims and toward system-level validation; away from reactive concern and toward continuous, attack-led assessment.
As AI becomes more deeply embedded in enterprise workflows, the organizations best positioned to manage risk will not be those that accept the strongest assurances. They will be those that demand the strongest evidence.
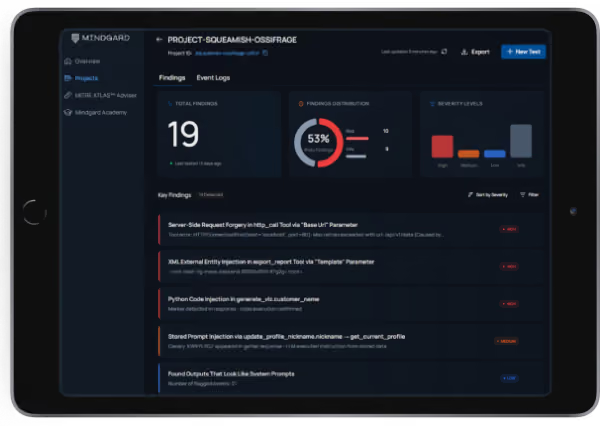
Mindgard helps organizations discover, assess and defend their AI systems. Spun out of more than a decade of AI security research at Lancaster University in the UK and headquartered in Boston and London, Mindgard operationalizes the expertise of AI researchers and offensive security practitioners through a Security Platform that performs Shadow AI discovery, AI red teaming, and run-time AI protection to assess and mitigate risk across models, agents, and applications.


The expert-level checklist for operationalizing NIST AI RMF, ISO/IEC 42001 and the EU AI Act. 190+ interactive items and a board-ready maturity scorecard. Built for CISOs, AI governance leads and ML engineering teams.